
Before promoting a multi-agent workflow in Microsoft Foundry, product owners must score groundedness and task success on a labeled set. Automated metrics alone are not trusted yet. What should you design?
Select an answer to reveal the explanation.
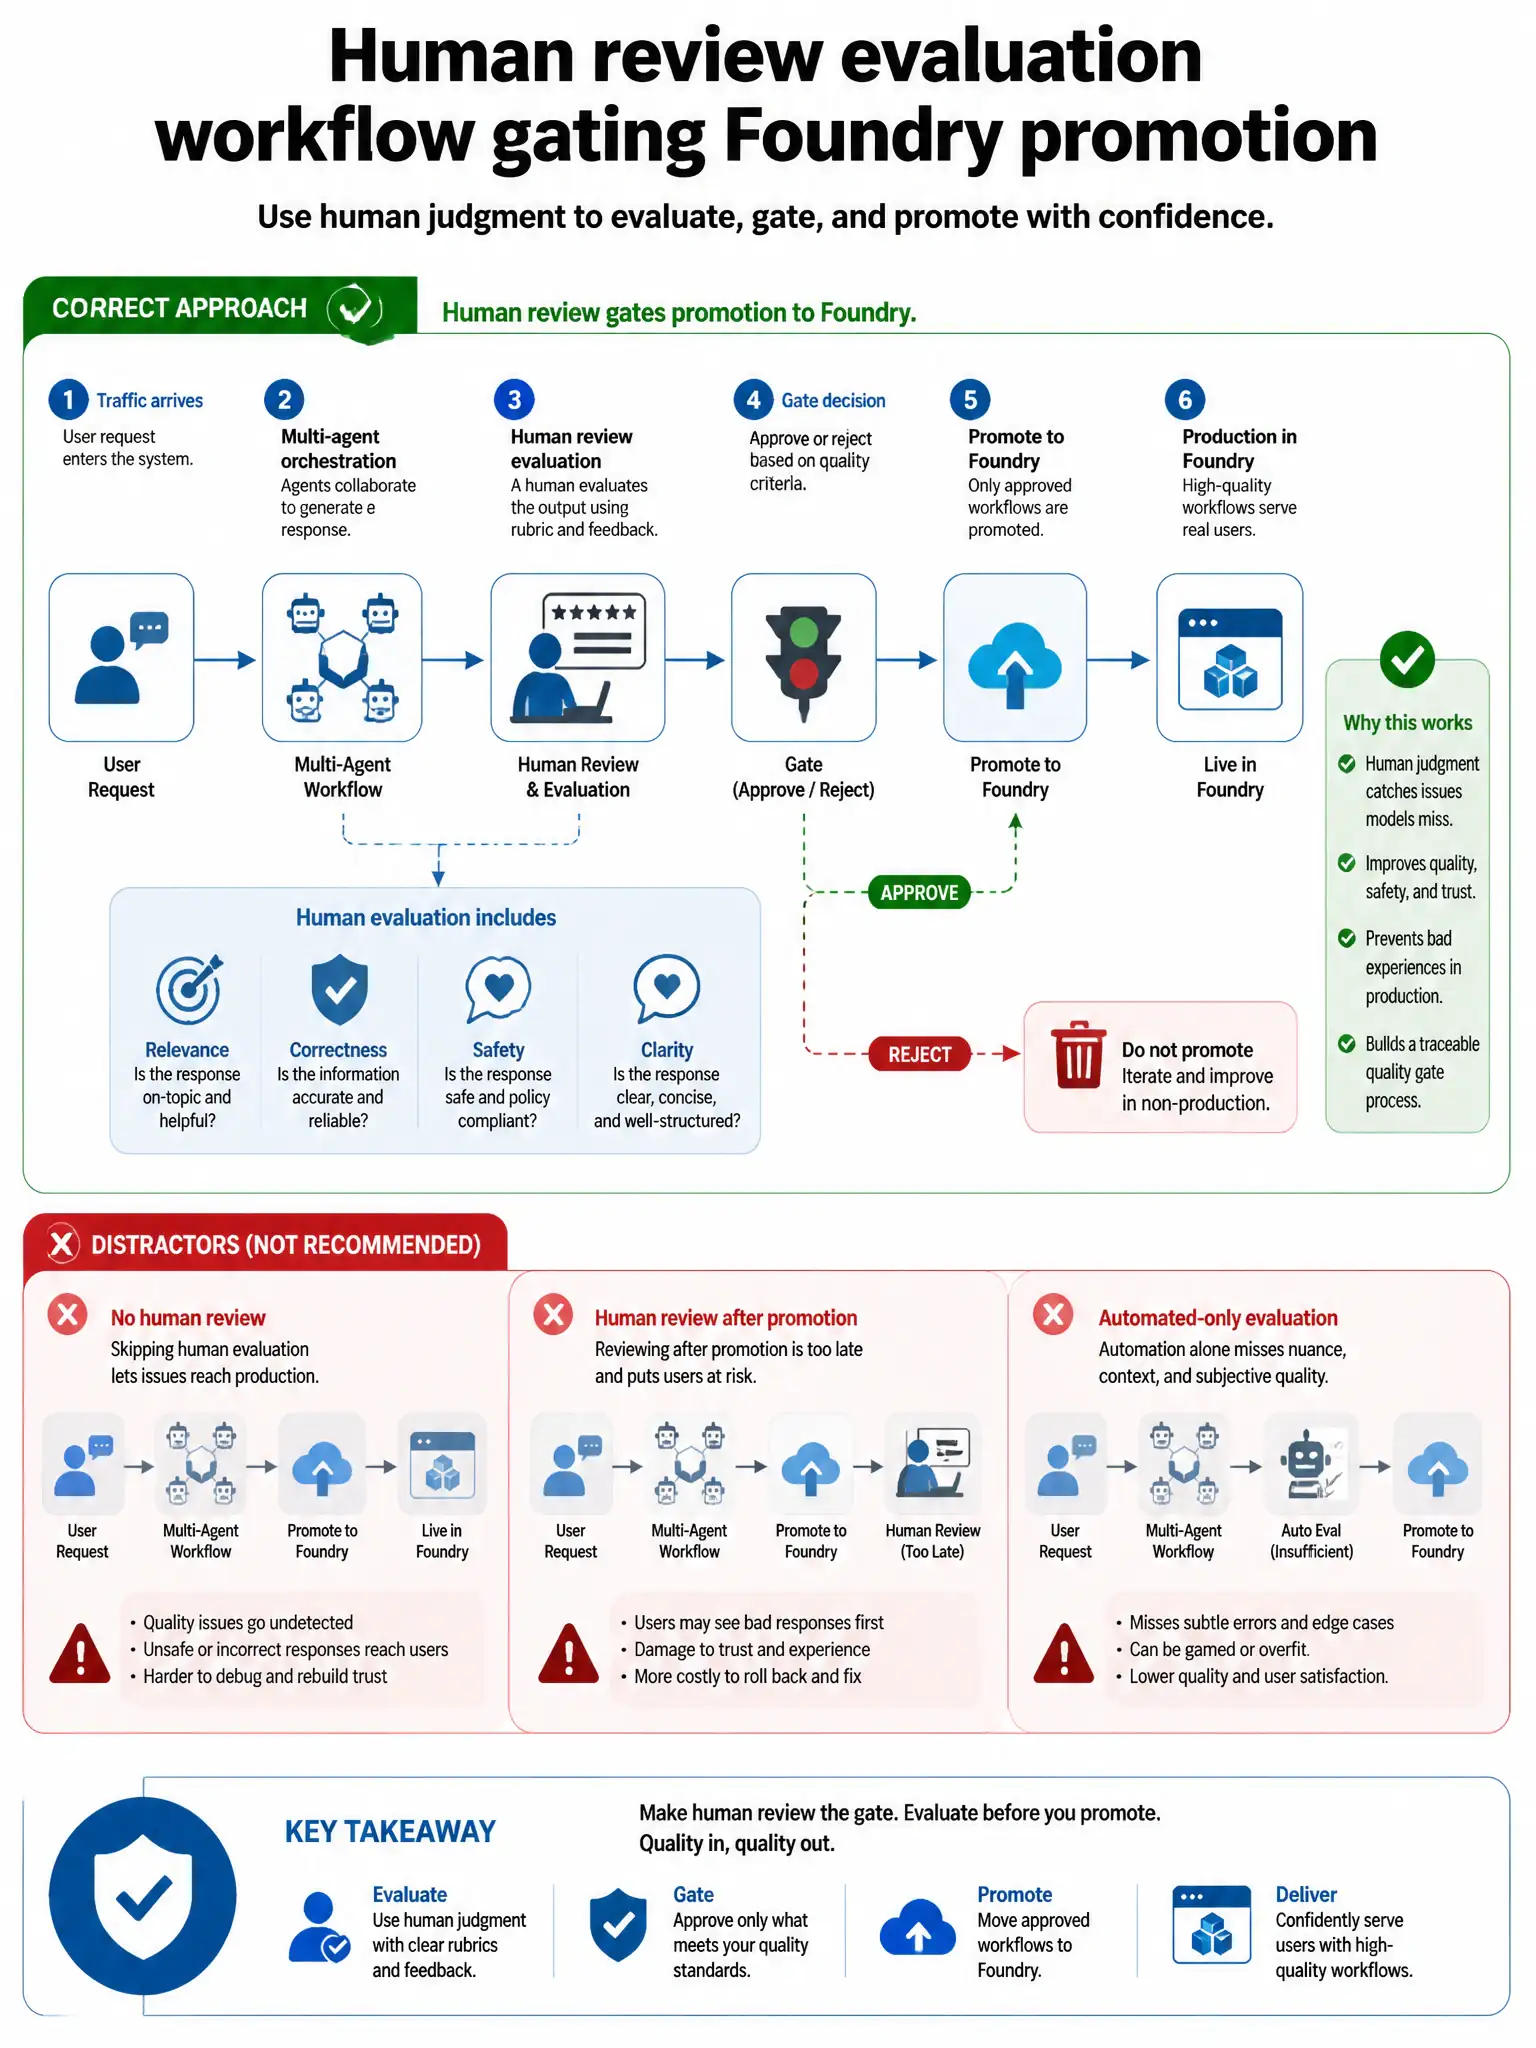
Short Explanation
You need a human review process in Foundry that scores curated cases and gates promotion. Compile-only checks, interface screenshots, and model self-confidence do not prove groundedness or task success. Pair human review with later automated judges, but do not skip human evaluation when owners must score quality.
Full Explanation
Designing and implementing a human review process in Foundry is a core evaluation skill. Curated cases, human scores, and promotion gates establish quality baselines for multi-agent systems. Pair human review with later automated judges, but do not skip human evaluation when owners must score quality. Skipping human review and shipping if unit tests compile is wrong because compilation does not measure agent task success or groundedness. Reviewing only marketing screenshots of the UI theme is wrong because interface cosmetics are not multi-agent quality evaluation. Relying solely on the model’s self-reported confidence tokens is wrong because model self-confidence is unreliable as a sole gate. Exam tip: Foundry human review is an explicit AI-500 evaluation lever.