
During a parallel multi-agent research run, one MCP tool returns intermittent 429 and timeout errors. Without handling, the whole workflow fails. What should you implement?
Select an answer to reveal the explanation.
Short Explanation
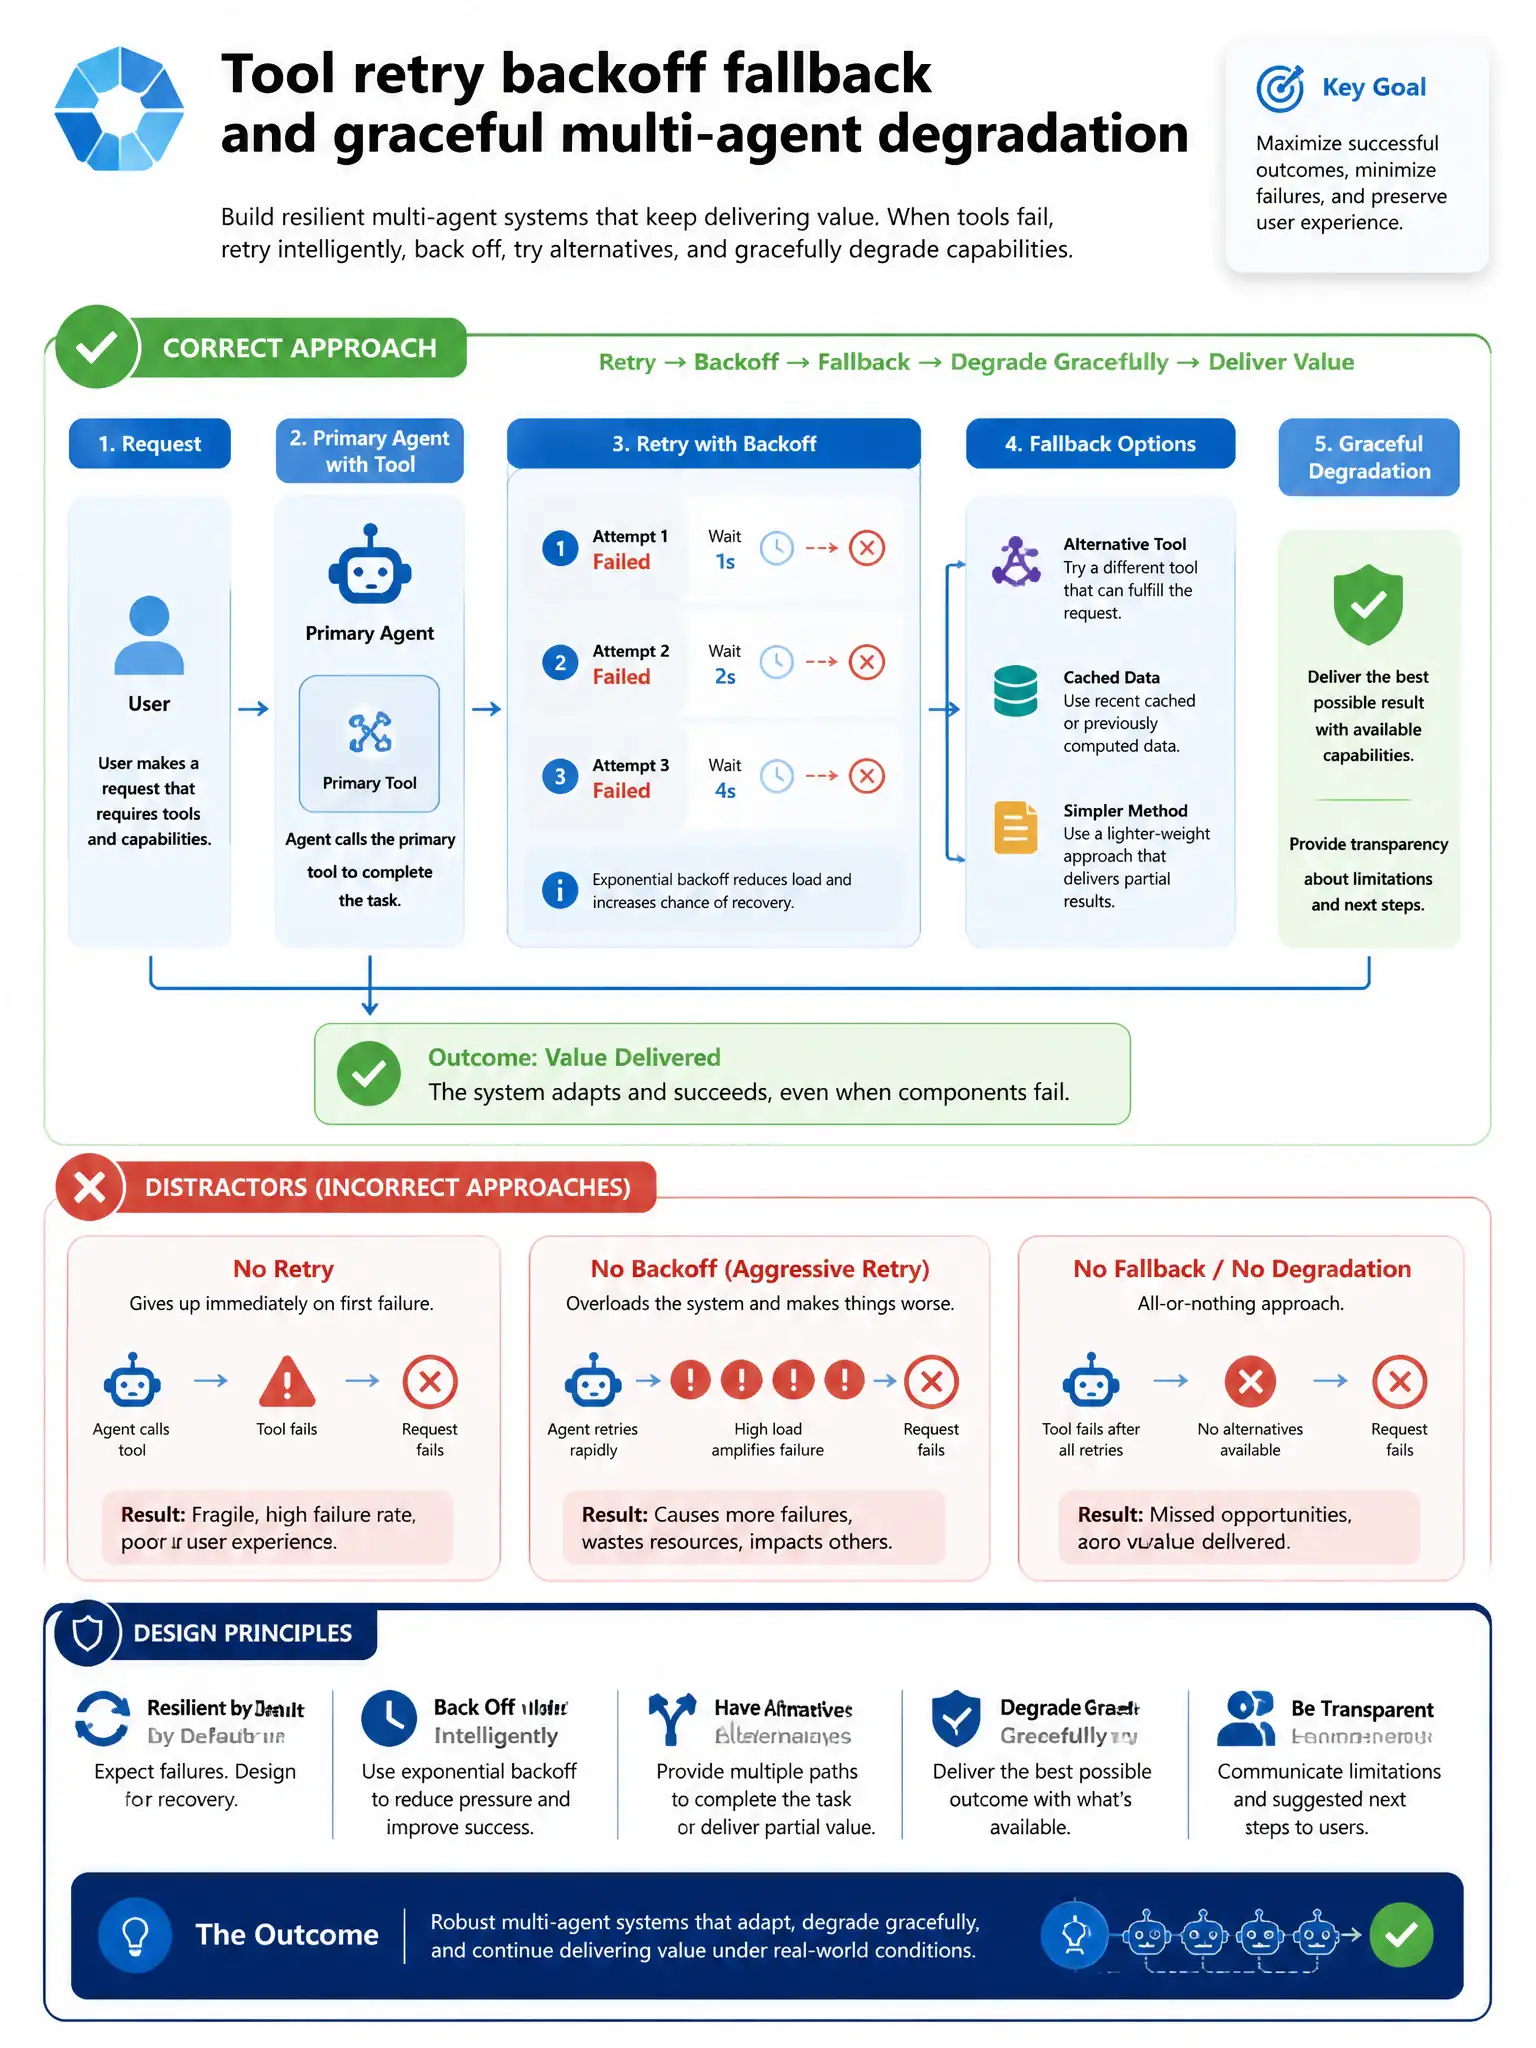
You need tool error-handling and fallbacks: retry transient MCP 429 and timeout faults with backoff, switch to alternate tools or cached results when safe, and let independent agents keep working. You're not supposed to let one flaky tool nuke the run, because tight retries can get you banned and empty fake successes corrupt agent reasoning.
Full Explanation
Tool error-handling and fallbacks are the right pattern: retry transient MCP or API faults such as 429 and timeouts with backoff, use alternate tools or cached results when safe, and degrade gracefully so independent agents finish. Immediate full-graph failure is brittle for intermittent errors. Infinite tight-loop retry with no backoff worsens throttling and can cause bans. Converting failures into empty successes misleads agents and hides outages. Exam tip: pair tool resilience with parallel-orchestration isolation.