
You are implementing specialist agents in Microsoft Foundry for a claims-processing multi-agent system. The extraction agent sometimes invents policy numbers when source text is incomplete. You need advanced prompt engineering that improves consistency without fine-tuning. Which approach best fits production multi-agent practice?
Select an answer to reveal the explanation.
Short Explanation
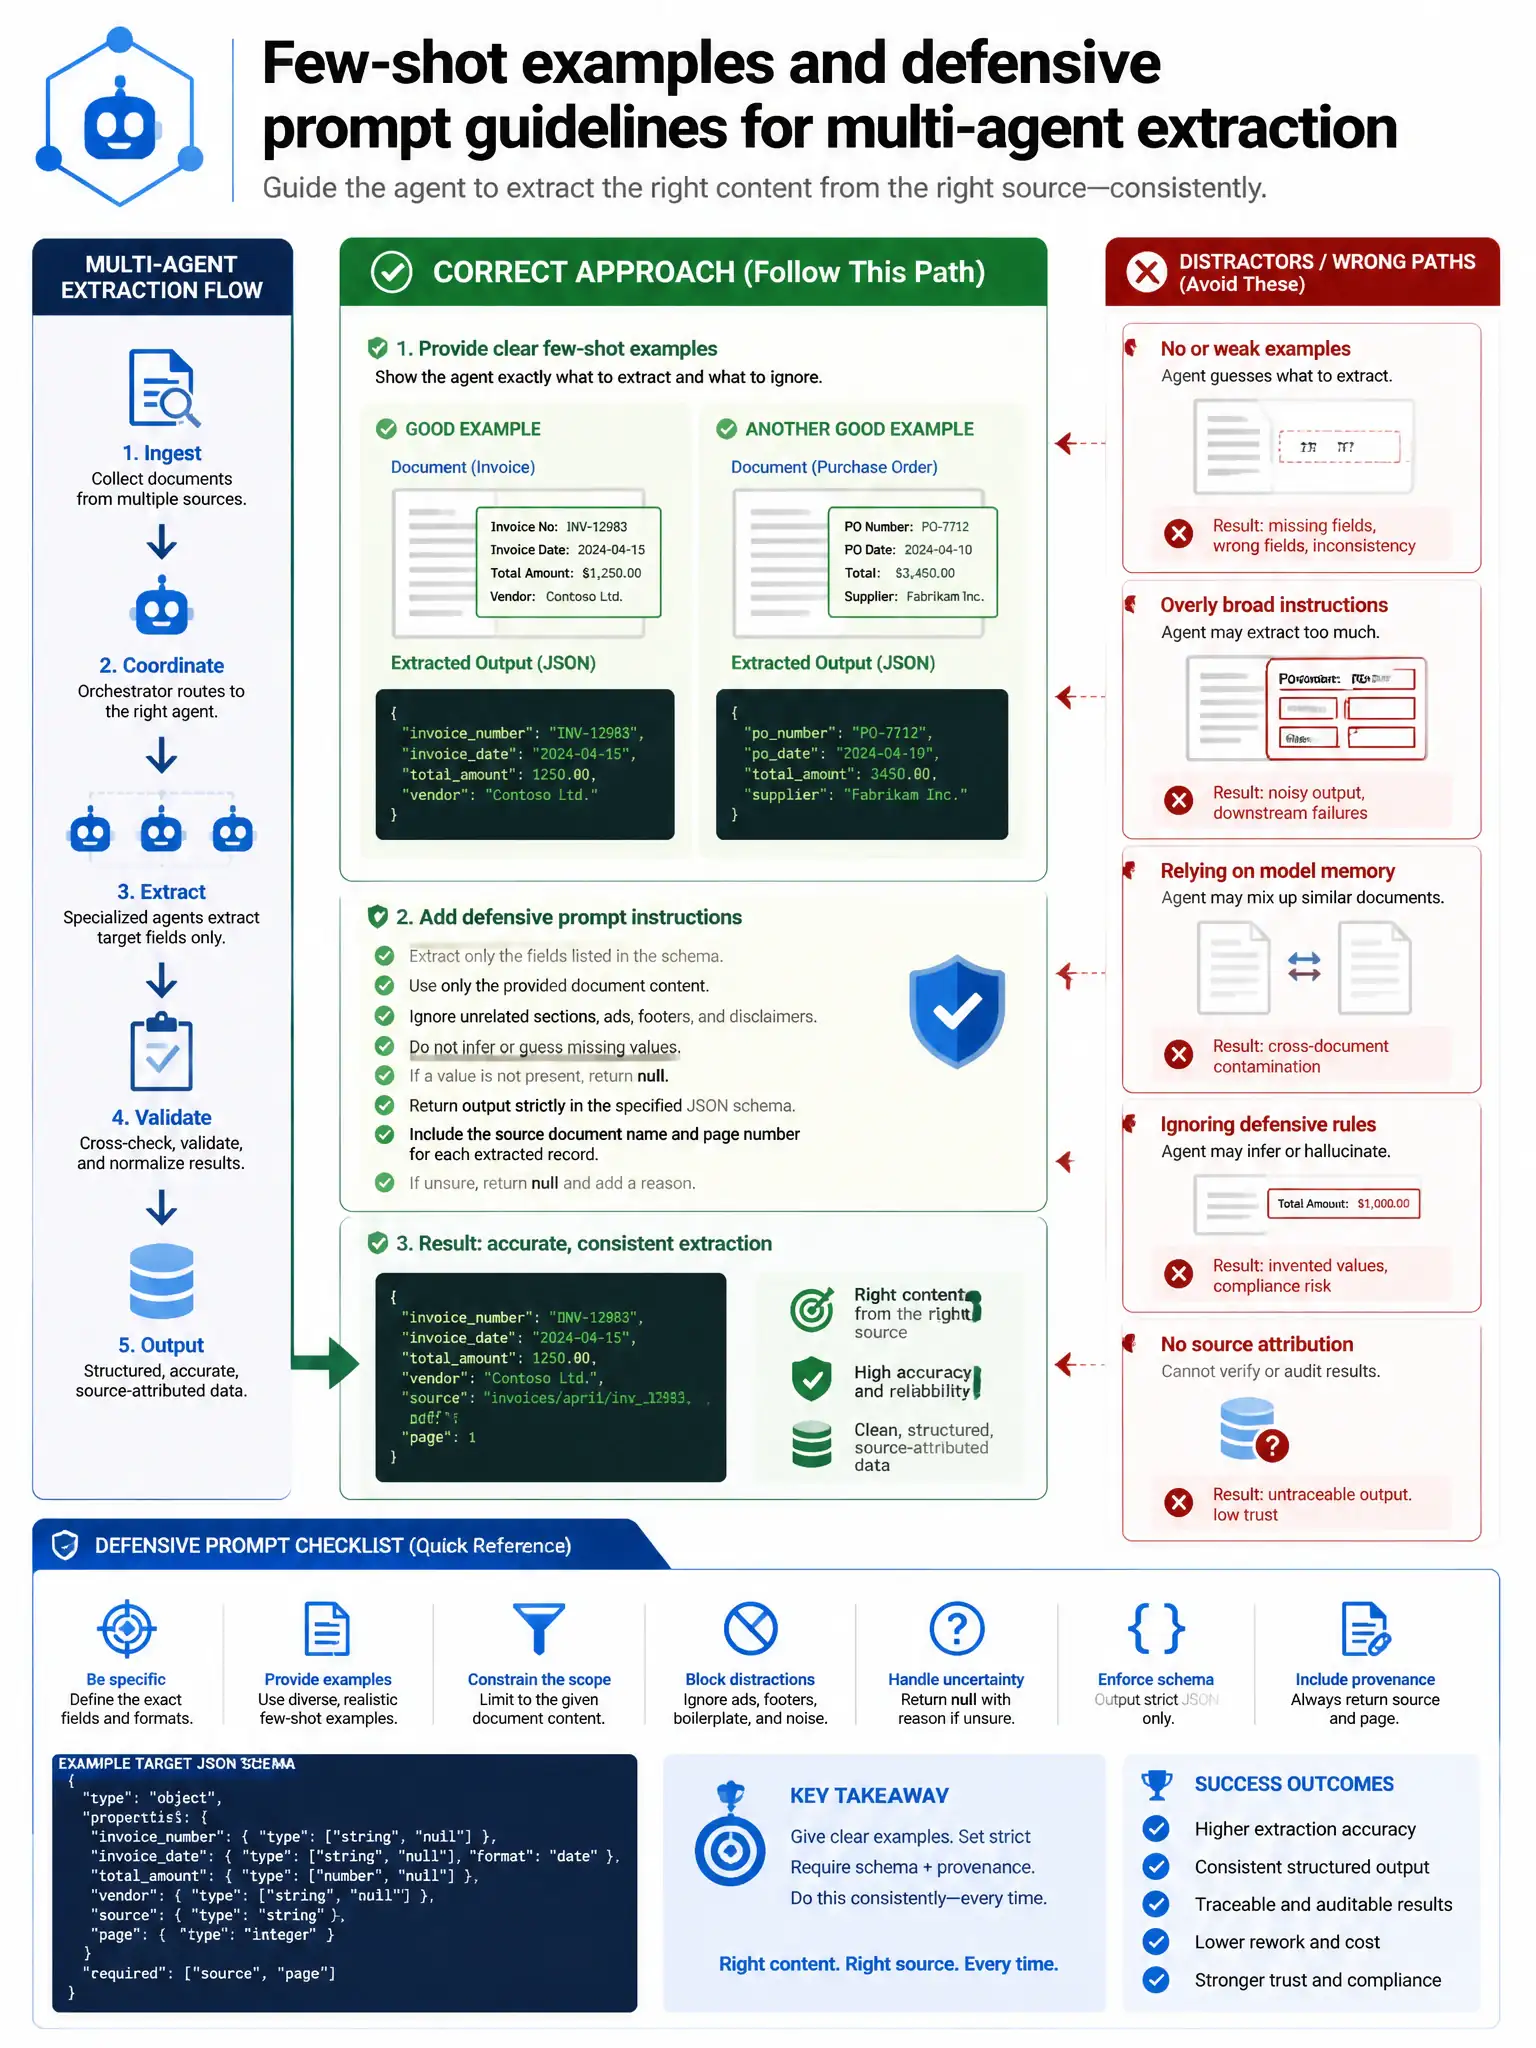
When an extraction agent starts inventing policy numbers, you don't start with full fine-tunes or empty prompts. You use curated few-shot examples that show incomplete inputs and correct refuse-or-flag behavior, inject dynamic claim context, and add defensive guidelines that forbid fabricating identifiers. That combo teaches pattern and constraint without retraining.
Full Explanation
Correct approach
Advanced prompt engineering for multi-agent solutions includes few-shot examples, dynamic context injection, defensive guidelines, and prompt lifecycle management. For an extraction agent that fabricates policy numbers on incomplete input, curated few-shot pairs that show incomplete sources and correct refuse-or-flag outcomes, plus runtime claim context and explicit anti-fabrication rules, improve reliability without an immediate fine-tune.
Why the weekly generic instruction set with disabled tool calling is wrong: Lengthening a generic prompt and disabling tools reduces grounding and does not teach incomplete-input behavior.
Why the per-claim-type fine-tuning approach is wrong: Per-claim-type fine-tuning before prompt work is costly and premature; removing examples removes a primary control.
Why the client-side JavaScript validation approach is wrong: Client-side validation cannot replace agent-side extraction discipline or multi-agent orchestration requirements.
Exam tip: Map “invented identifiers” symptoms to few-shot examples, defensive guidelines, and dynamic context first.