
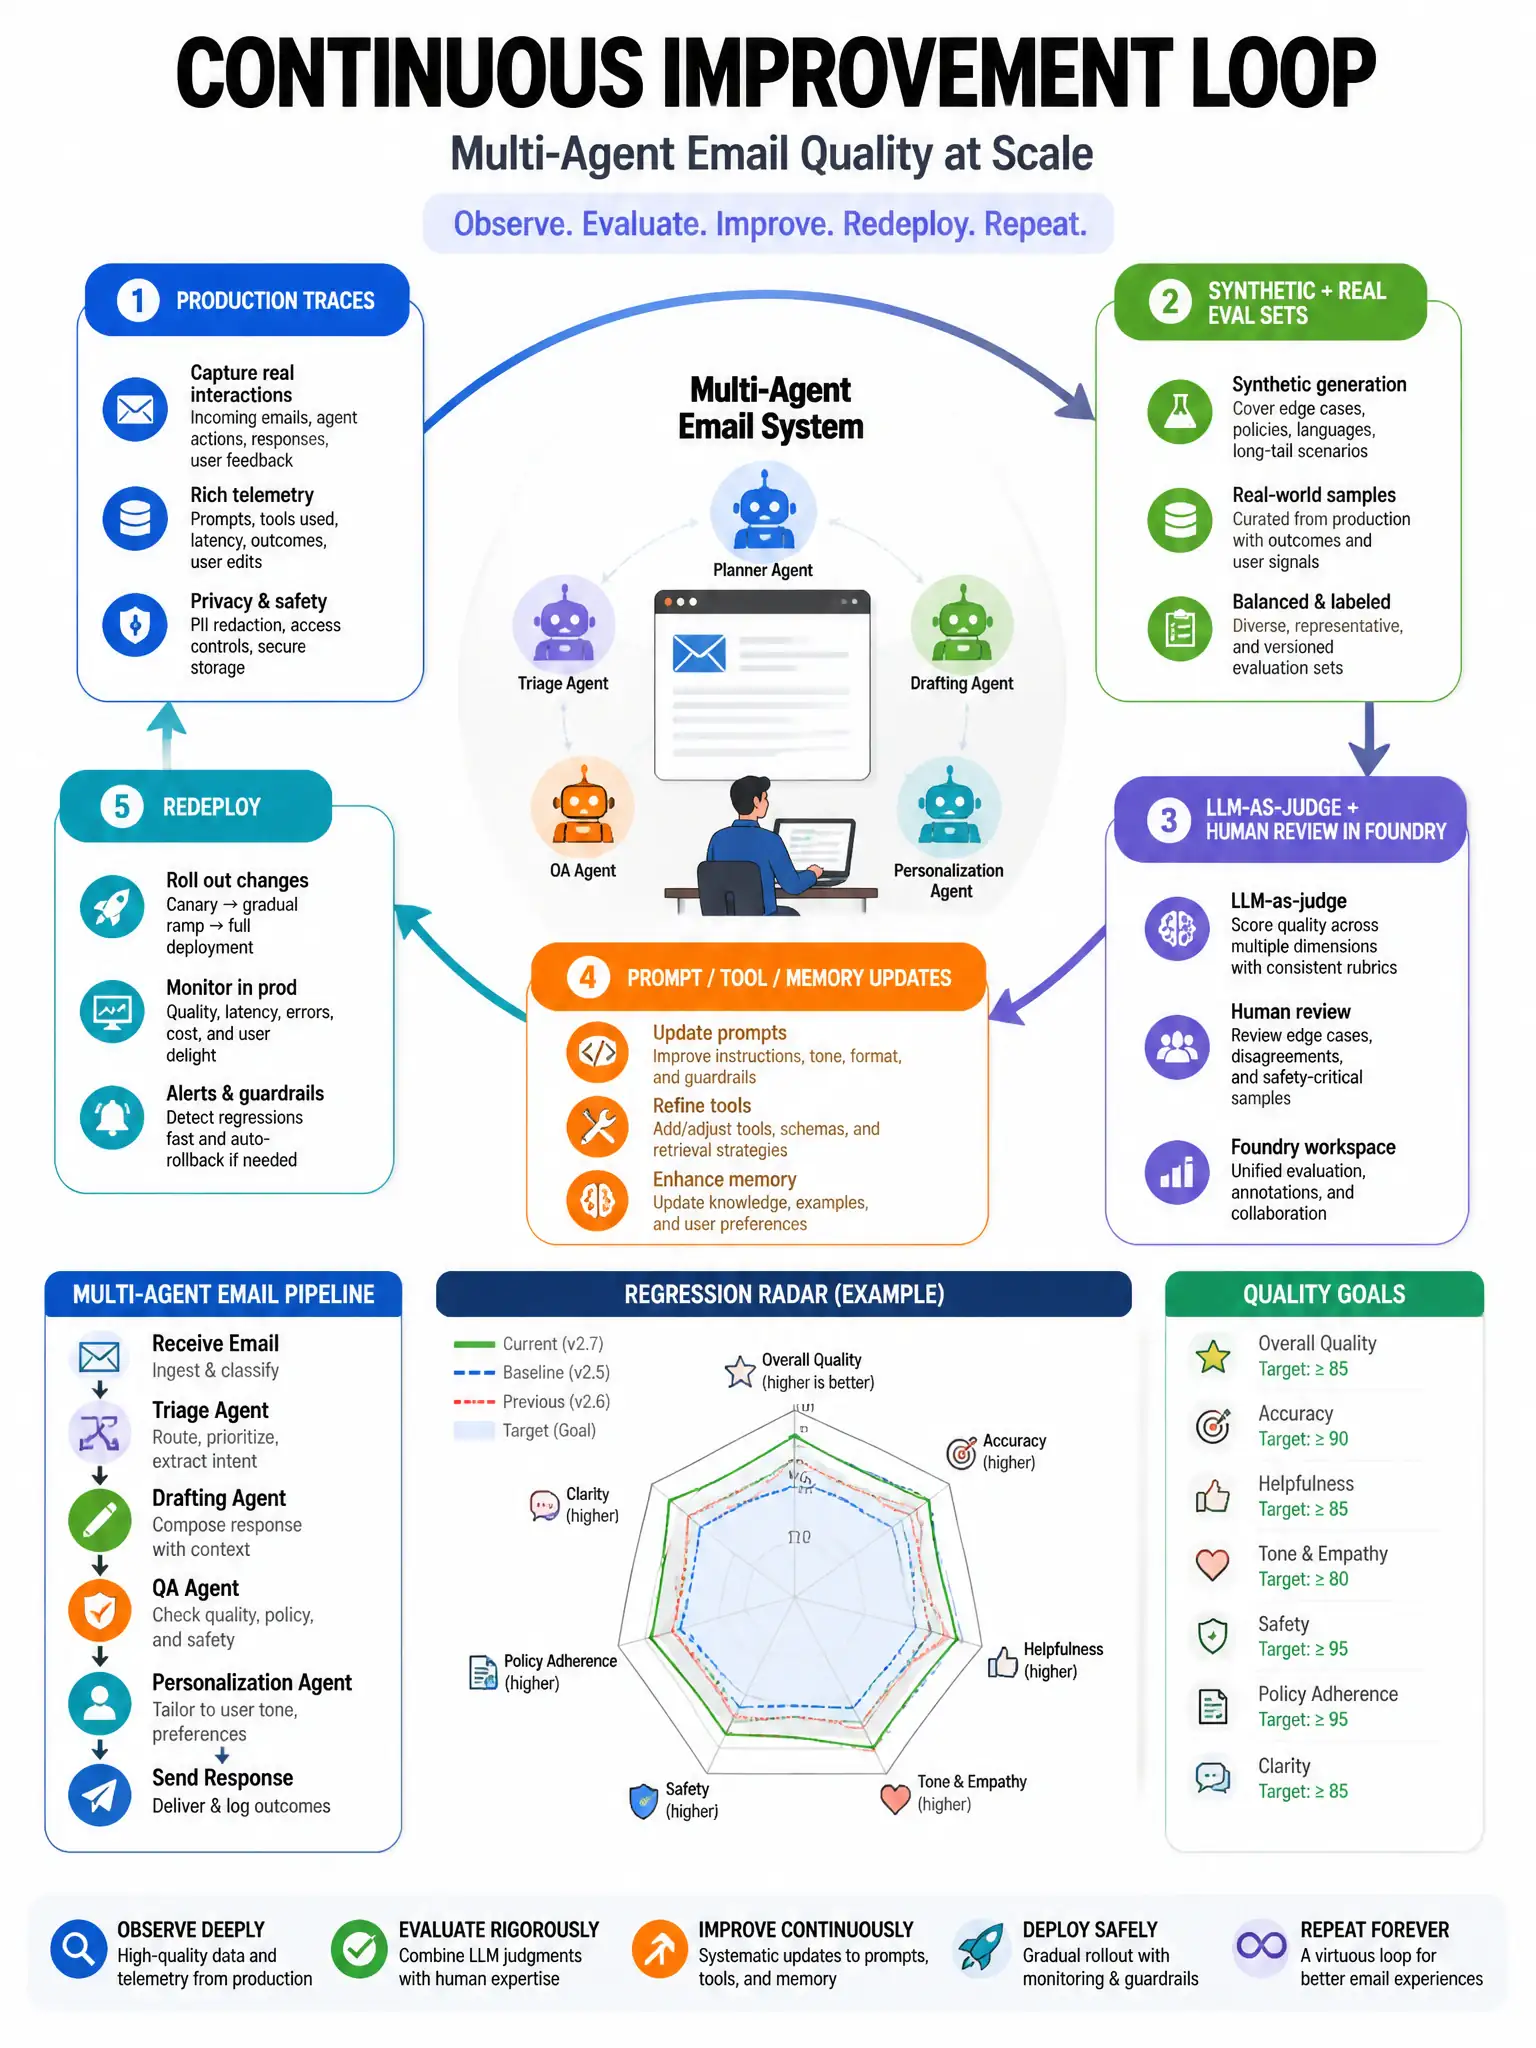
After deploying a multi-agent customer-email system in Microsoft Foundry, quality fluctuates weekly. You need continuous improvement beyond occasional manual spot checks. Which evaluation approach best fits?
Select an answer to reveal the explanation.
Short Explanation
You need the continuous improvement stack: LLM-as-a-judge for scalable scoring, targeted human review in Foundry, synthetic test sets for coverage, and user feedback loops. That's how you catch regressions in memory, tools, prompts, and end-to-end workflows. Automate evals in CI/CD for agent changes, and keep humans on high-risk samples.
Full Explanation
Continuous improvement is correct because optimizing multi-agent solutions includes LLM-as-a-judge frameworks, synthetic data generation, semantic optimization loops, user feedback, targeted human review in Foundry, and evaluations for memory, knowledge, tools, and prompts. Never measuring after go-live because production traffic is the only test that matters is wrong because production without measurement delays drift detection. Replacing all human review with coin-flip acceptance is wrong because random acceptance is not evaluation. Shipping prompt changes with no regression suite and relying on user complaints as the KPI is wrong because complaint-driven quality is lagging and incomplete. Track groundedness, task success, tool error rates, and end-to-end workflow completion alongside judge scores.