
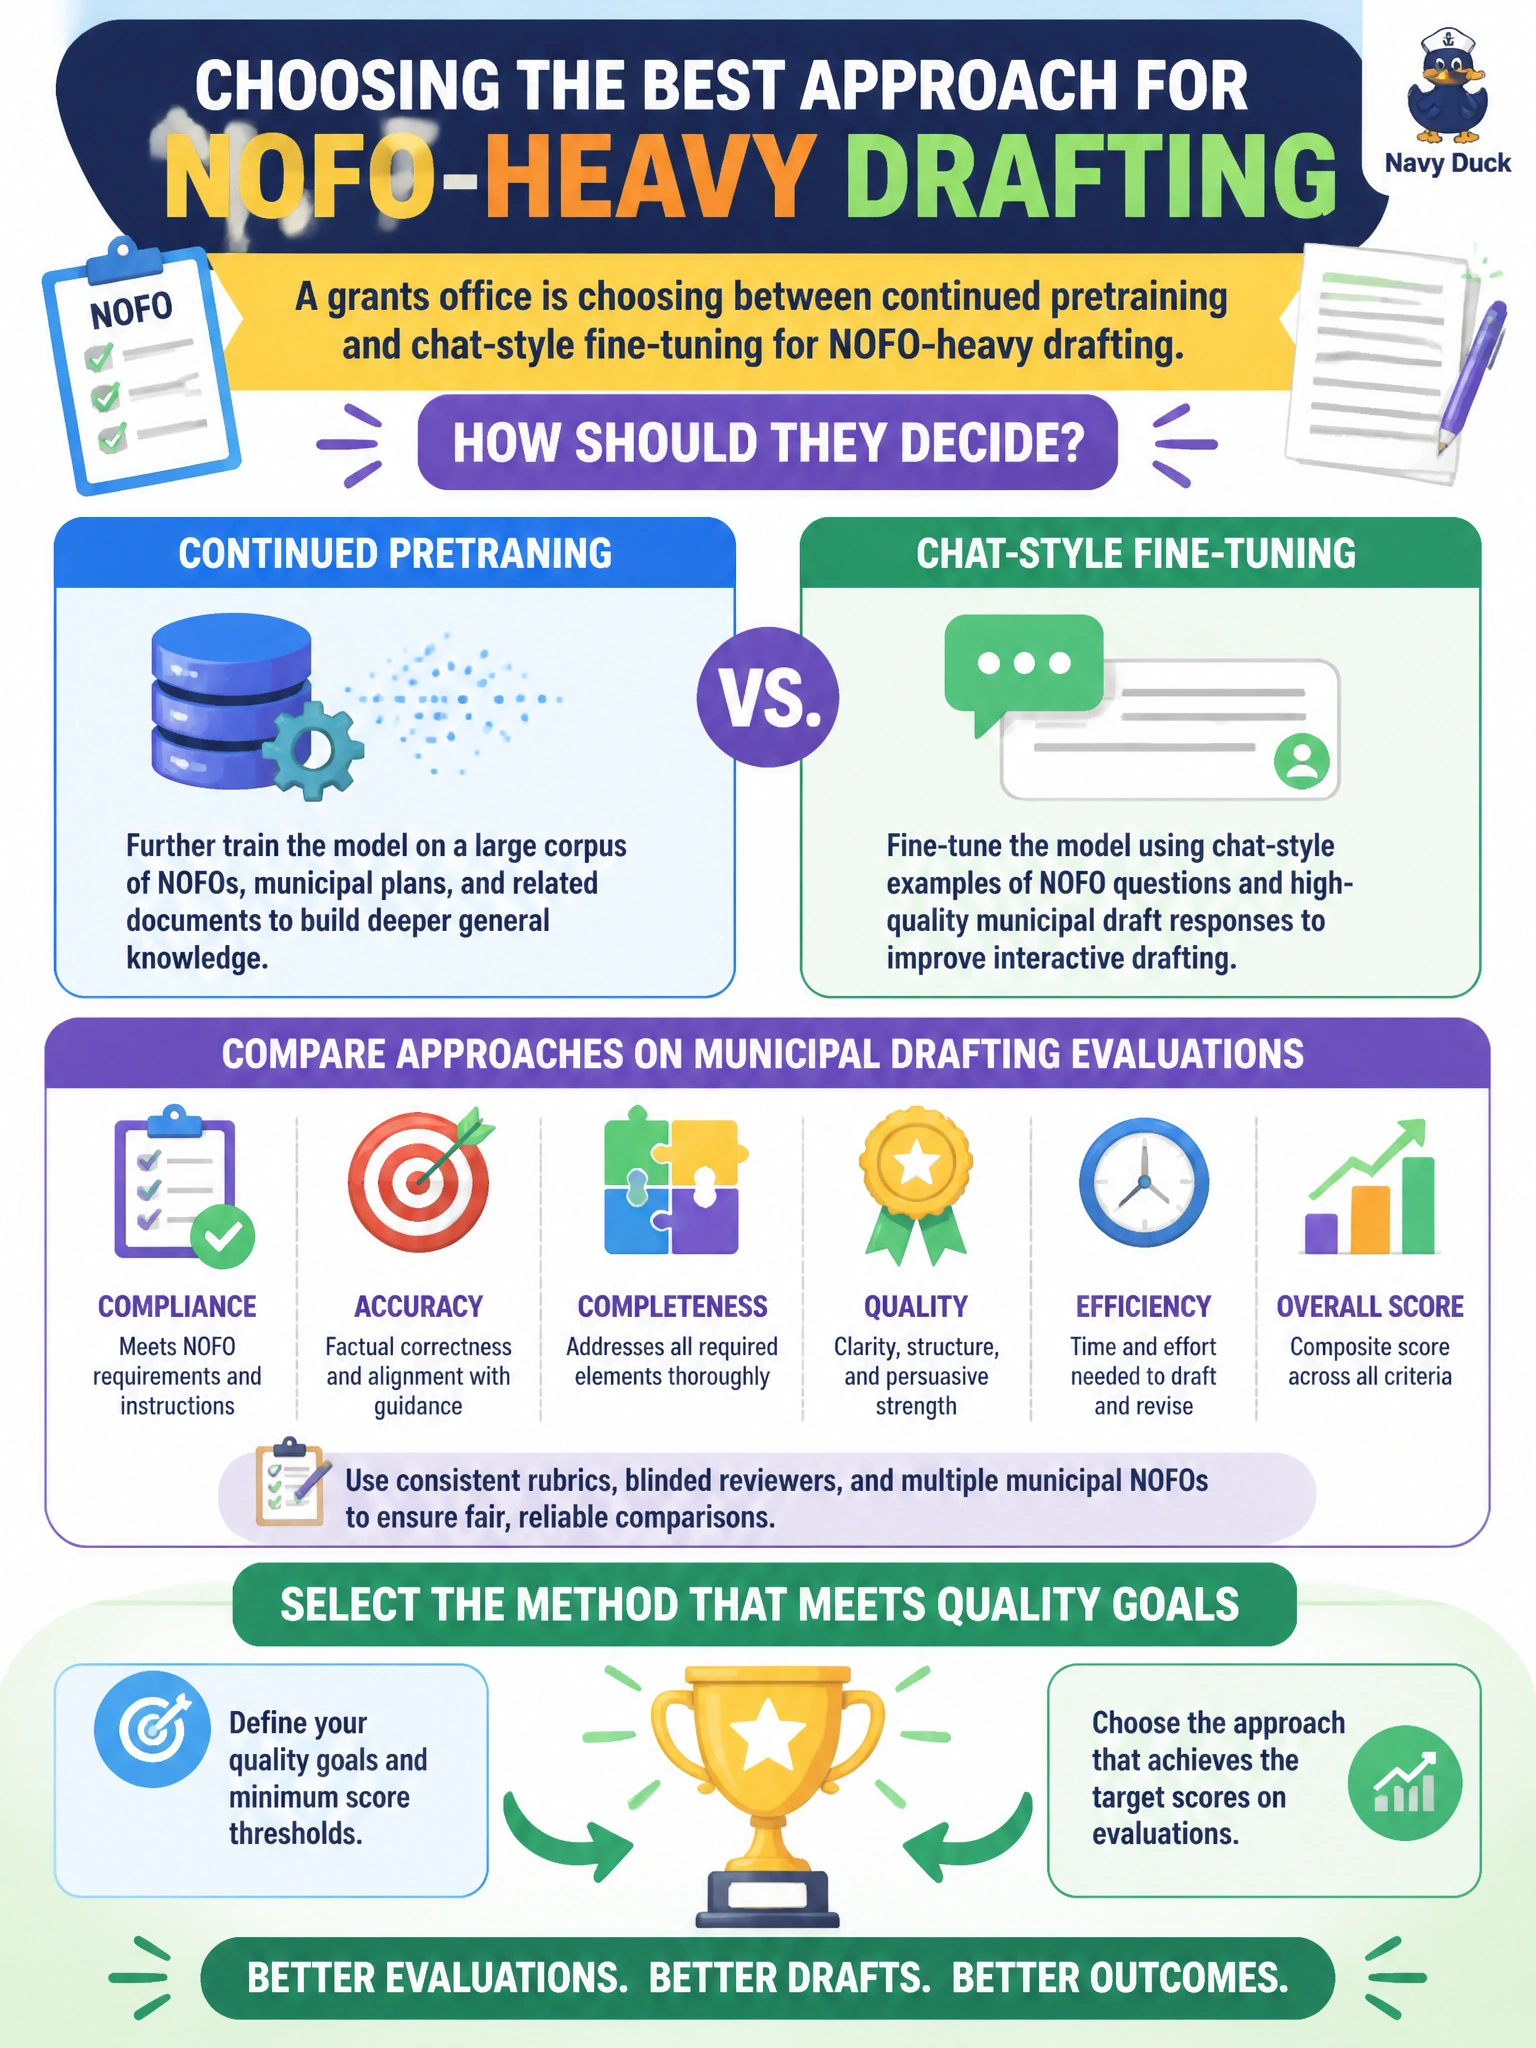
A grants office is choosing between continued pretraining and chat-style fine-tuning for NOFO-heavy drafting. How should they decide?
Select an answer to reveal the explanation.
Short Explanation
Continued pretraining and chat fine-tuning are different tools—test them on your NOFO drafting evals. Don't settle for NOFO vocabulary recall checks or chat formatting ratings since they won't show if you'll hit your drafting quality goals. Comparing on general web loss benchmarks won't tell you about NOFO drafting either.
Full Explanation
Comparing approaches on municipal drafting evaluations and selecting the method that meets quality goals is how a grants office should choose between continued pretraining and chat-style fine-tuning for NOFO-heavy drafting. Continued pretraining and instruction/chat fine-tuning optimize different objectives; only task evaluations on NOFO drafting quality show which method meets the office’s bar. Evidence over buzzwords is the GenAIOps decision rule.
Comparing approaches on NOFO vocabulary recall checks and selecting the method that meets quality goals tests isolated term memory, not NOFO-heavy drafting quality, so it ignores task fit and cost. Comparing approaches on curated chat formatting ratings and selecting the method that meets quality goals rates surface formatting without checking whether it actually produces better NOFO-heavy drafting quality for this office’s specific corpus and goals. Comparing approaches on general web loss benchmarks and selecting the method that meets quality goals abandons quality goals entirely because general web loss does not indicate NOFO drafting quality.
Exam caveat: method-selection items want comparison on the civic drafting task itself, not comparison on proxies like vocabulary recall, chat formatting, or general web loss. When both advanced fine-tuning methods appear, the correct answer is comparison on the civic task metrics.
Operational check: define NOFO drafting evals (instruction following, citation of opportunity terms, tone), run continued-pretraining and chat fine-tuning candidates under comparable data budgets where feasible, score both, pick the method that meets quality and cost goals, and document the decision for the grants GenAIOps record.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.