
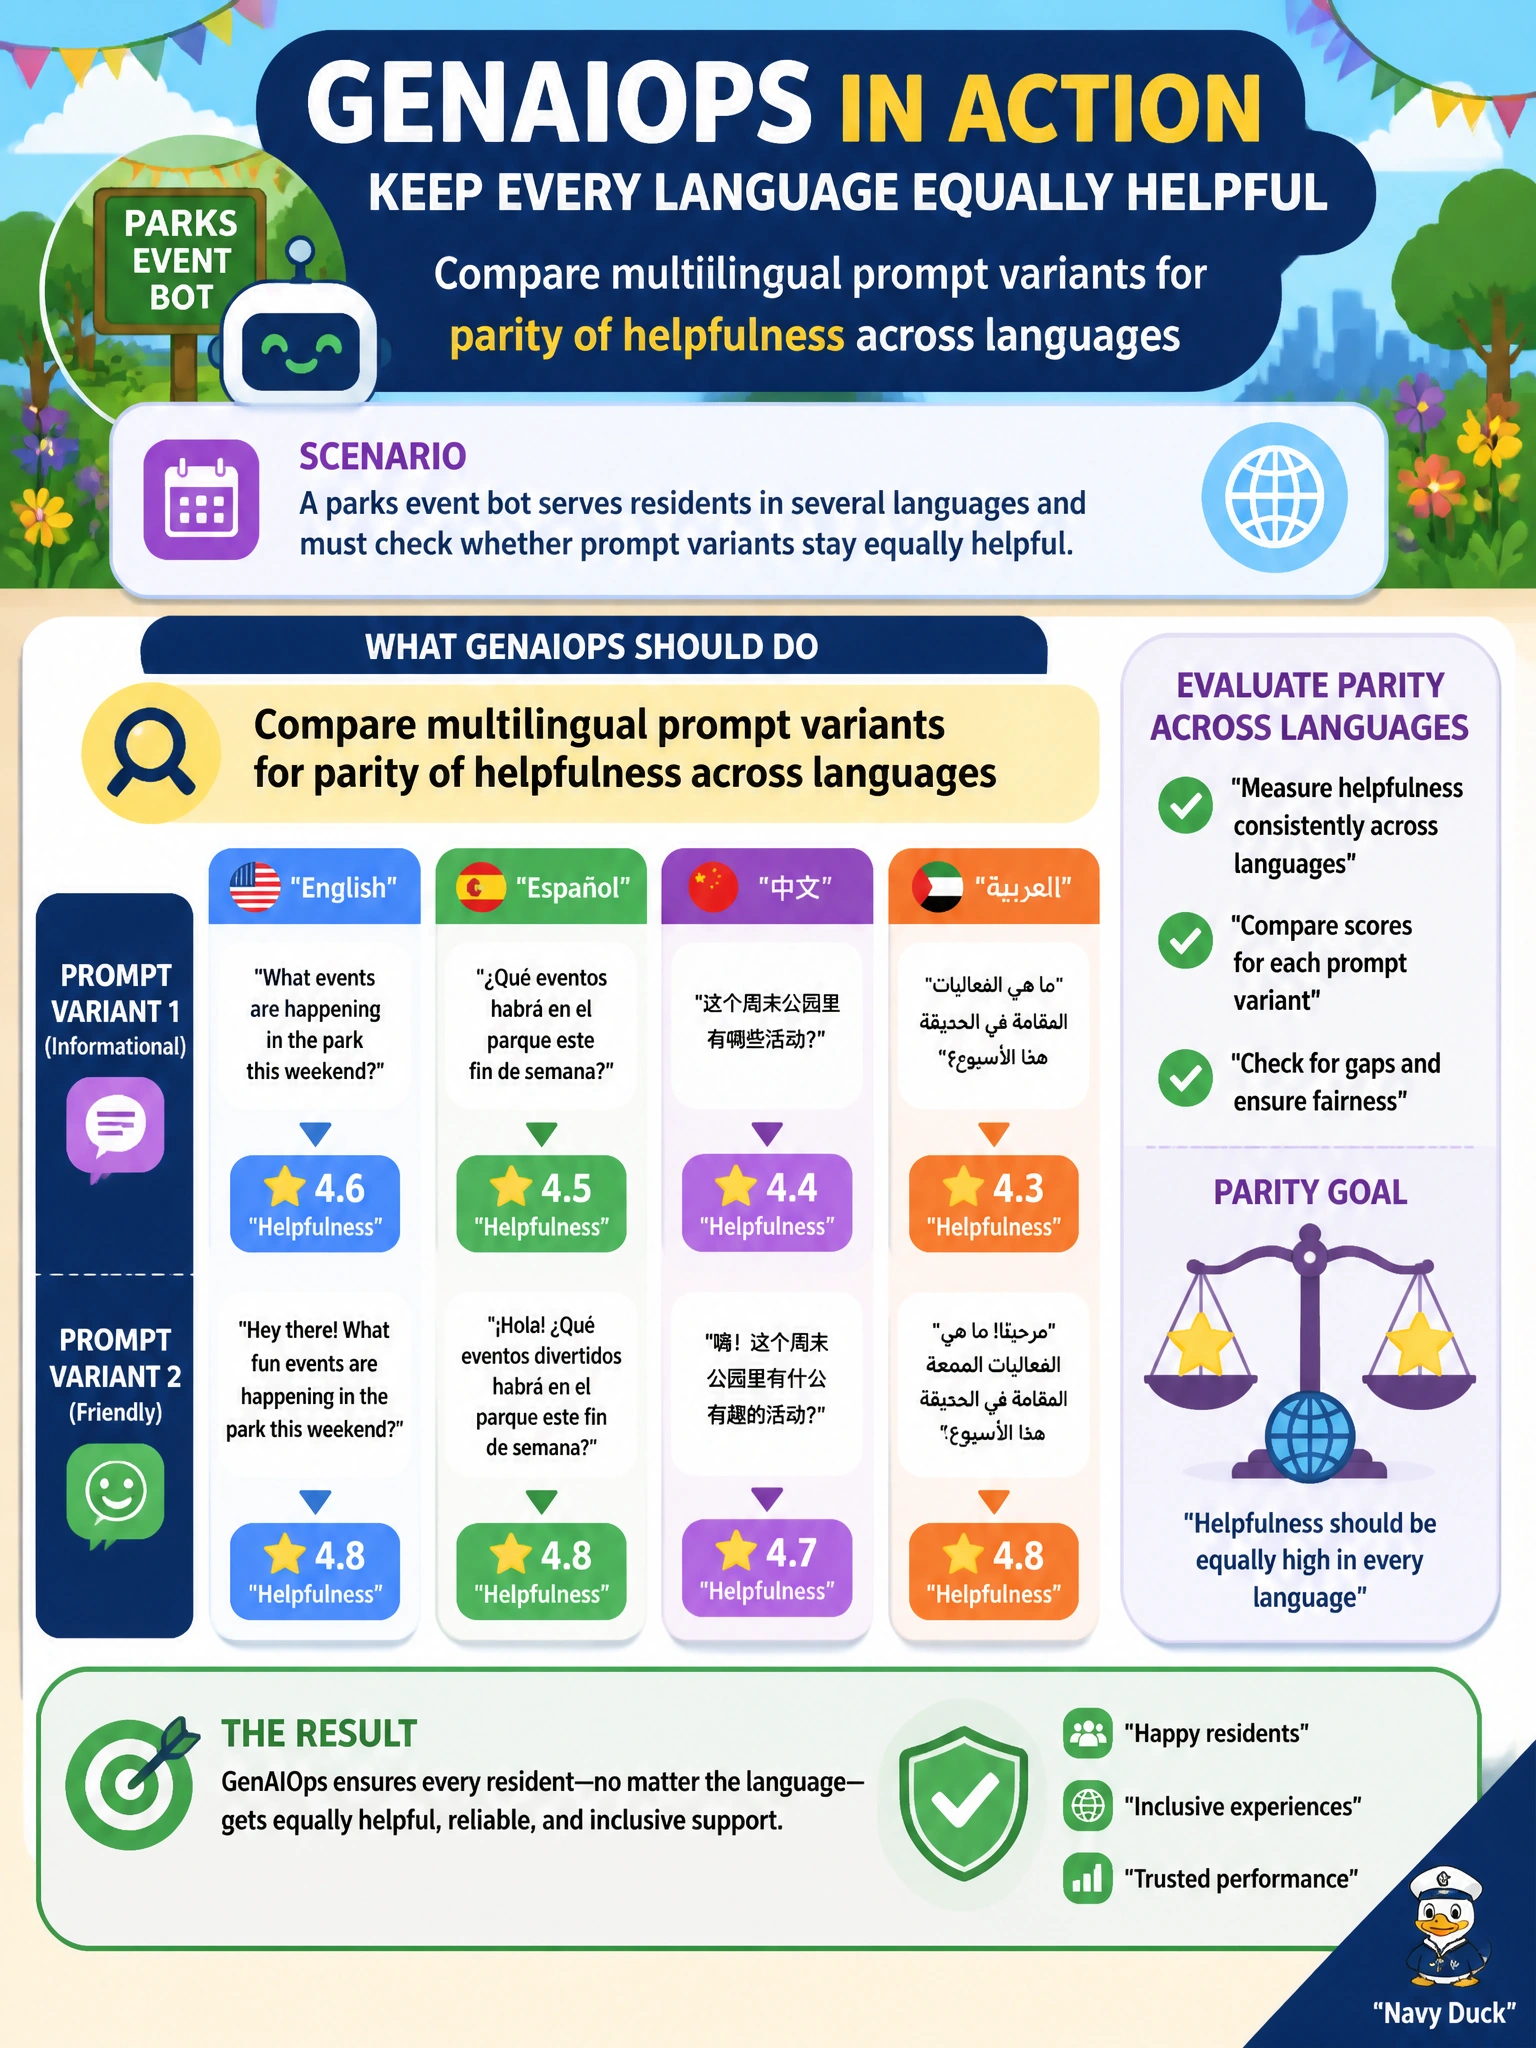
A parks event bot serves residents in several languages and must check whether prompt variants stay equally helpful. What should GenAIOps do?
Select an answer to reveal the explanation.
Short Explanation
Even if grounding, fidelity, and fluency parity look even, you won't know if you're equally helpful in every language. Compare multilingual prompt variants until helpfulness is actually even.
Full Explanation
Comparing multilingual prompt variants for parity of helpfulness across languages is the GenAIOps quality practice for a parks event bot serving residents in several languages. Parity means Spanish, English, and other supported channels achieve comparable task success, groundedness, and tone—not that English alone looks good. Measuring each language variant on parallel or carefully localized eval sets surfaces under-served communities before event registration season, when inequitable bot quality becomes a civic access issue.
Comparing multilingual prompt variants for parity of grounding across languages fails to establish equal helpfulness; it checks only factual alignment to event data and leaves gaps in task success, tone, and cultural appropriateness invisible. Comparing multilingual prompt variants for parity of fidelity across languages fails because fidelity only estimates translation faithfulness, not whether each language variant is equally helpful to residents, so helpfulness parity is assumed rather than actually measured. Comparing multilingual prompt variants for parity of fluency across languages fails validation—fluency is a language-quality metric, and it says nothing about whether each language variant delivers comparable helpfulness or avoids factual and cultural errors in fee, time, and location details.
Exam caveat: Language parity evaluation needs native or qualified reviewers and metrics that account for retrieval corpora gaps per language. Identical English prompts pasted into other languages without localization often underperform even if the base model is multilingual.
Operational check: Maintain per-language eval sets for parks FAQs; score helpfulness, groundedness, and refusal quality per locale; set promotion gates that require parity within an agreed delta of the English baseline; monitor production language-mix success rates; and escalate corpora gaps when a language systematically lacks retrieved event facts.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.