
A 311 assistant team wants to try concise versus detailed system prompts and compare how residents react. What should they do?
Select an answer to reveal the explanation.
Short Explanation
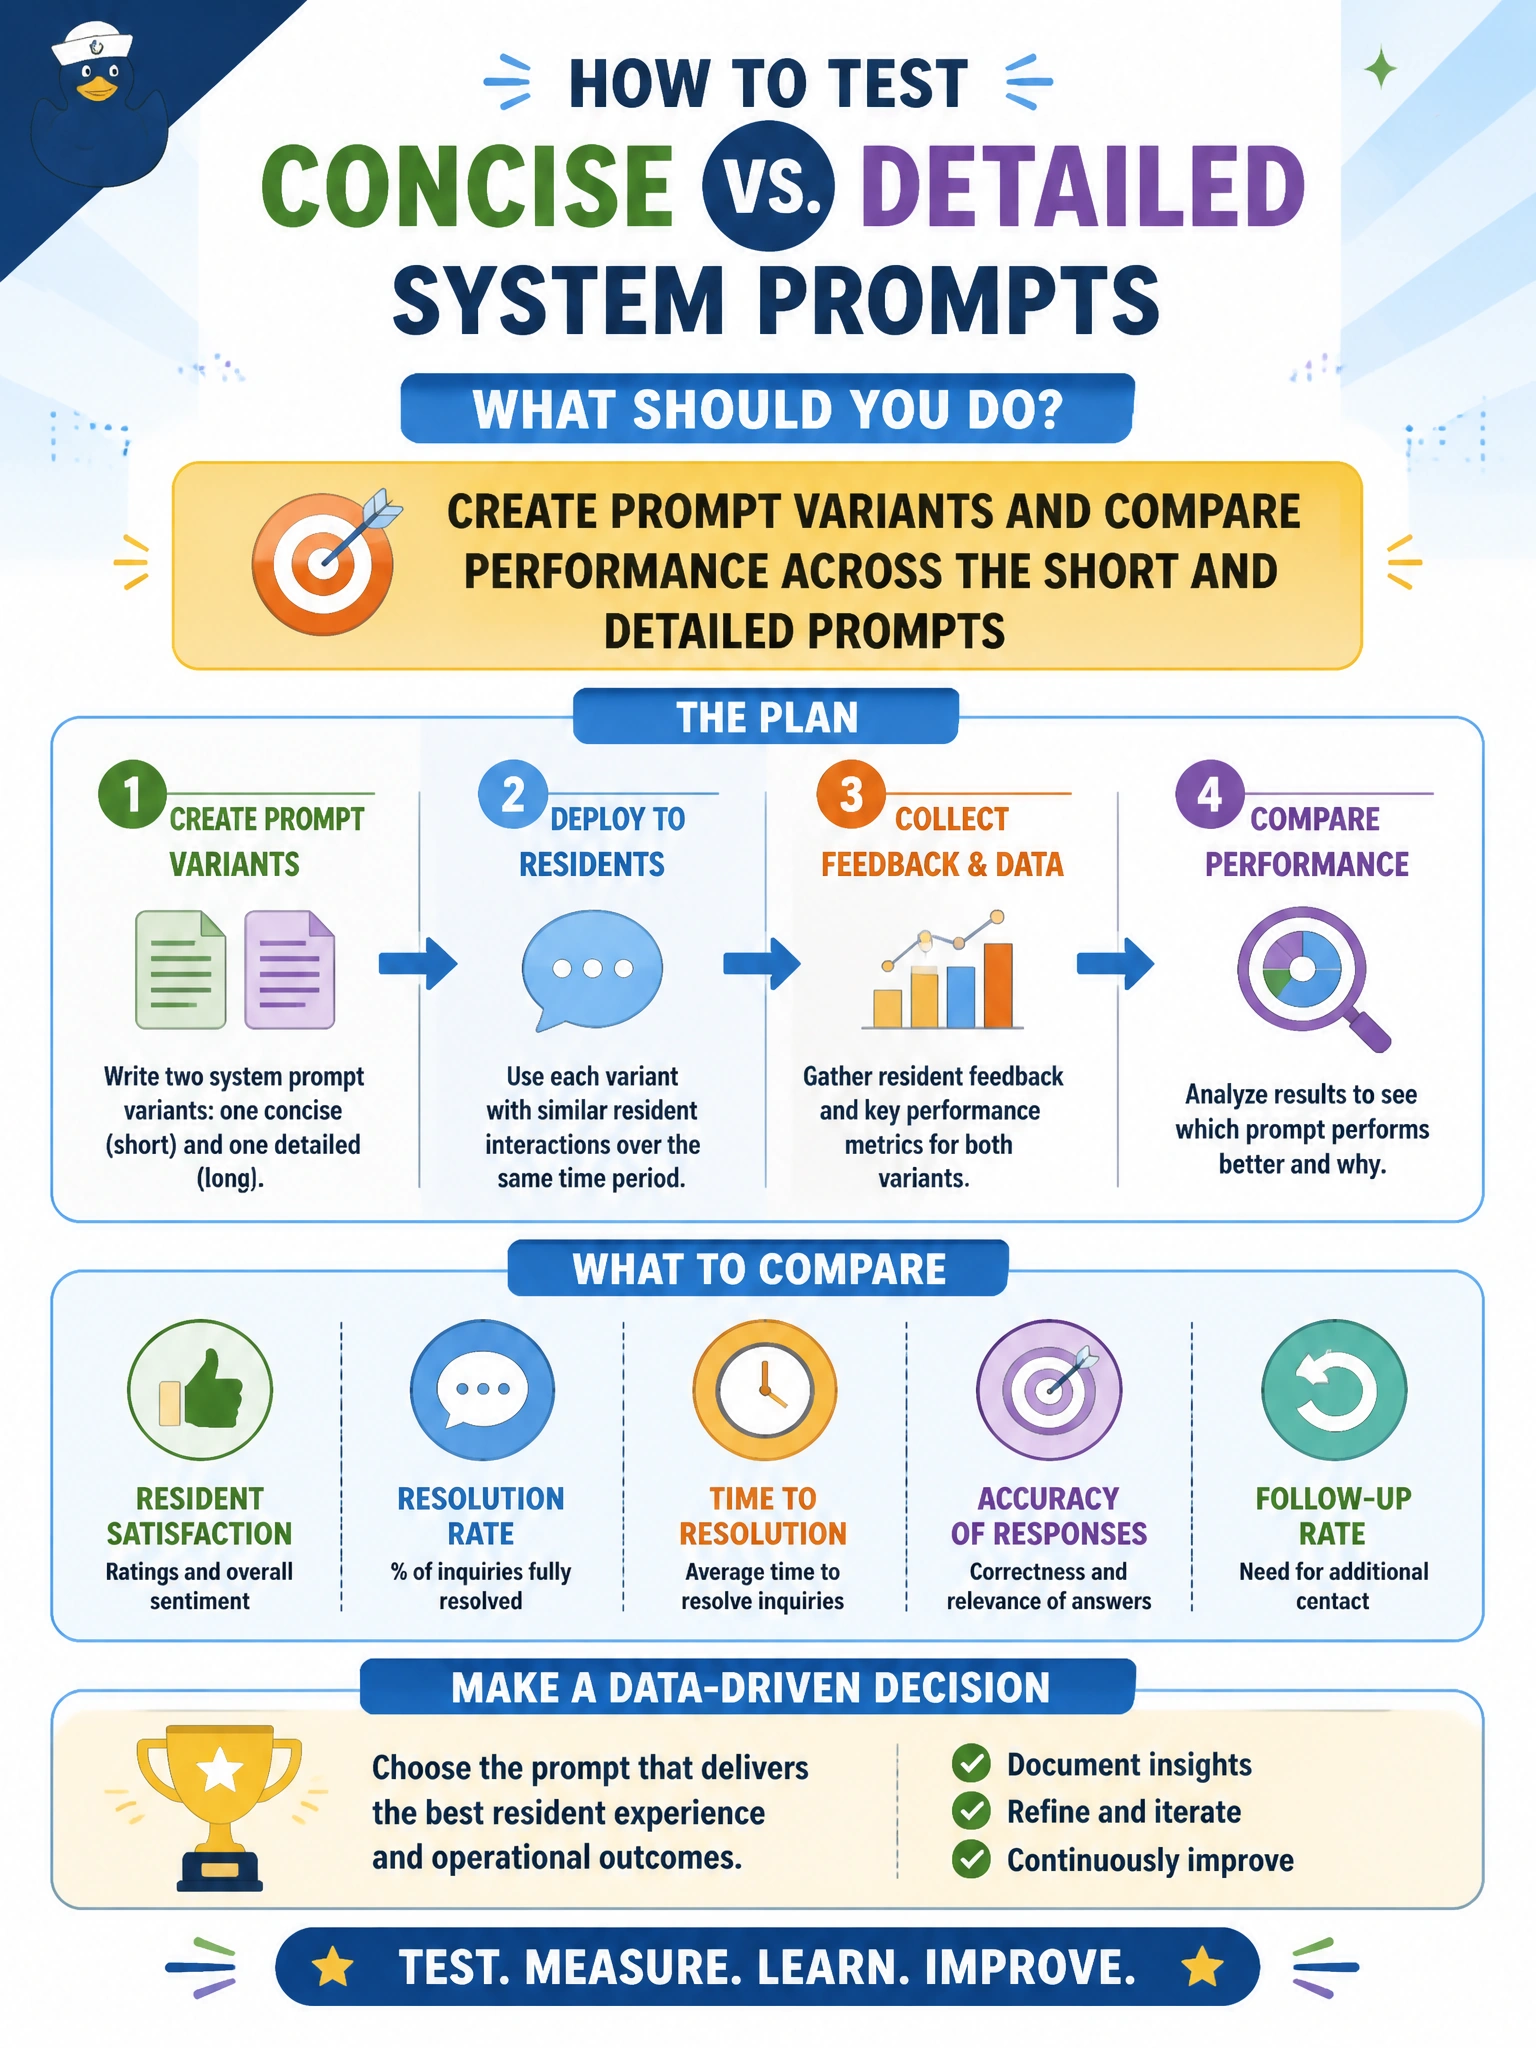
Short and chatty versus long and thorough — try both, but keep score. Build prompt variants and compare them so 311 learns what actually helps residents instead of guessing.
Full Explanation
Creating prompt variants and comparing performance across concise versus detailed system prompts is controlled experimentation for a 311 assistant. GenAIOps defines two (or more) prompt designs, runs them against the same resident-outcome metrics—task completion, groundedness, escalation rate, CSAT proxies—and promotes only the variant that wins on civic goals. Comparing short versus detailed instructions on identical evaluation sets reveals whether brevity reduces latency and confusion or whether detail improves policy adherence for complex service requests.
Creating prompt variants and comparing grounding accuracy across the short and detailed prompts is too narrow for resident reaction: grounding alone cannot show which variant improves task completion, satisfaction, or equity across channels. Creating prompt variants and comparing preference using ratings from internal reviewers fails to answer how residents react: internal preference is not a substitute for live resident response in 311 channels. Creating prompt variants and comparing quality using automated scores from offline test datasets fails to capture resident reaction—offline scores are not a substitute for how people actually respond in live 311 channels.
Exam caveat: Prompt A/B or variant comparison must keep model version, retrieval corpus, and evaluation set constant so differences attribute to the prompt, not confounders. Also distinguish offline eval promotion from live multi-armed experiments that need traffic controls and ethics review for resident-facing 311 channels.
Operational check: Store each prompt variant in source control with an ID; run both against the same labeled 311 eval set and record groundedness, relevance, and refusal correctness; decide promotion with a documented threshold; after go-live, monitor channel-level outcome metrics for regressions; and never mix unmeasured random prompts in production without telemetry.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.