
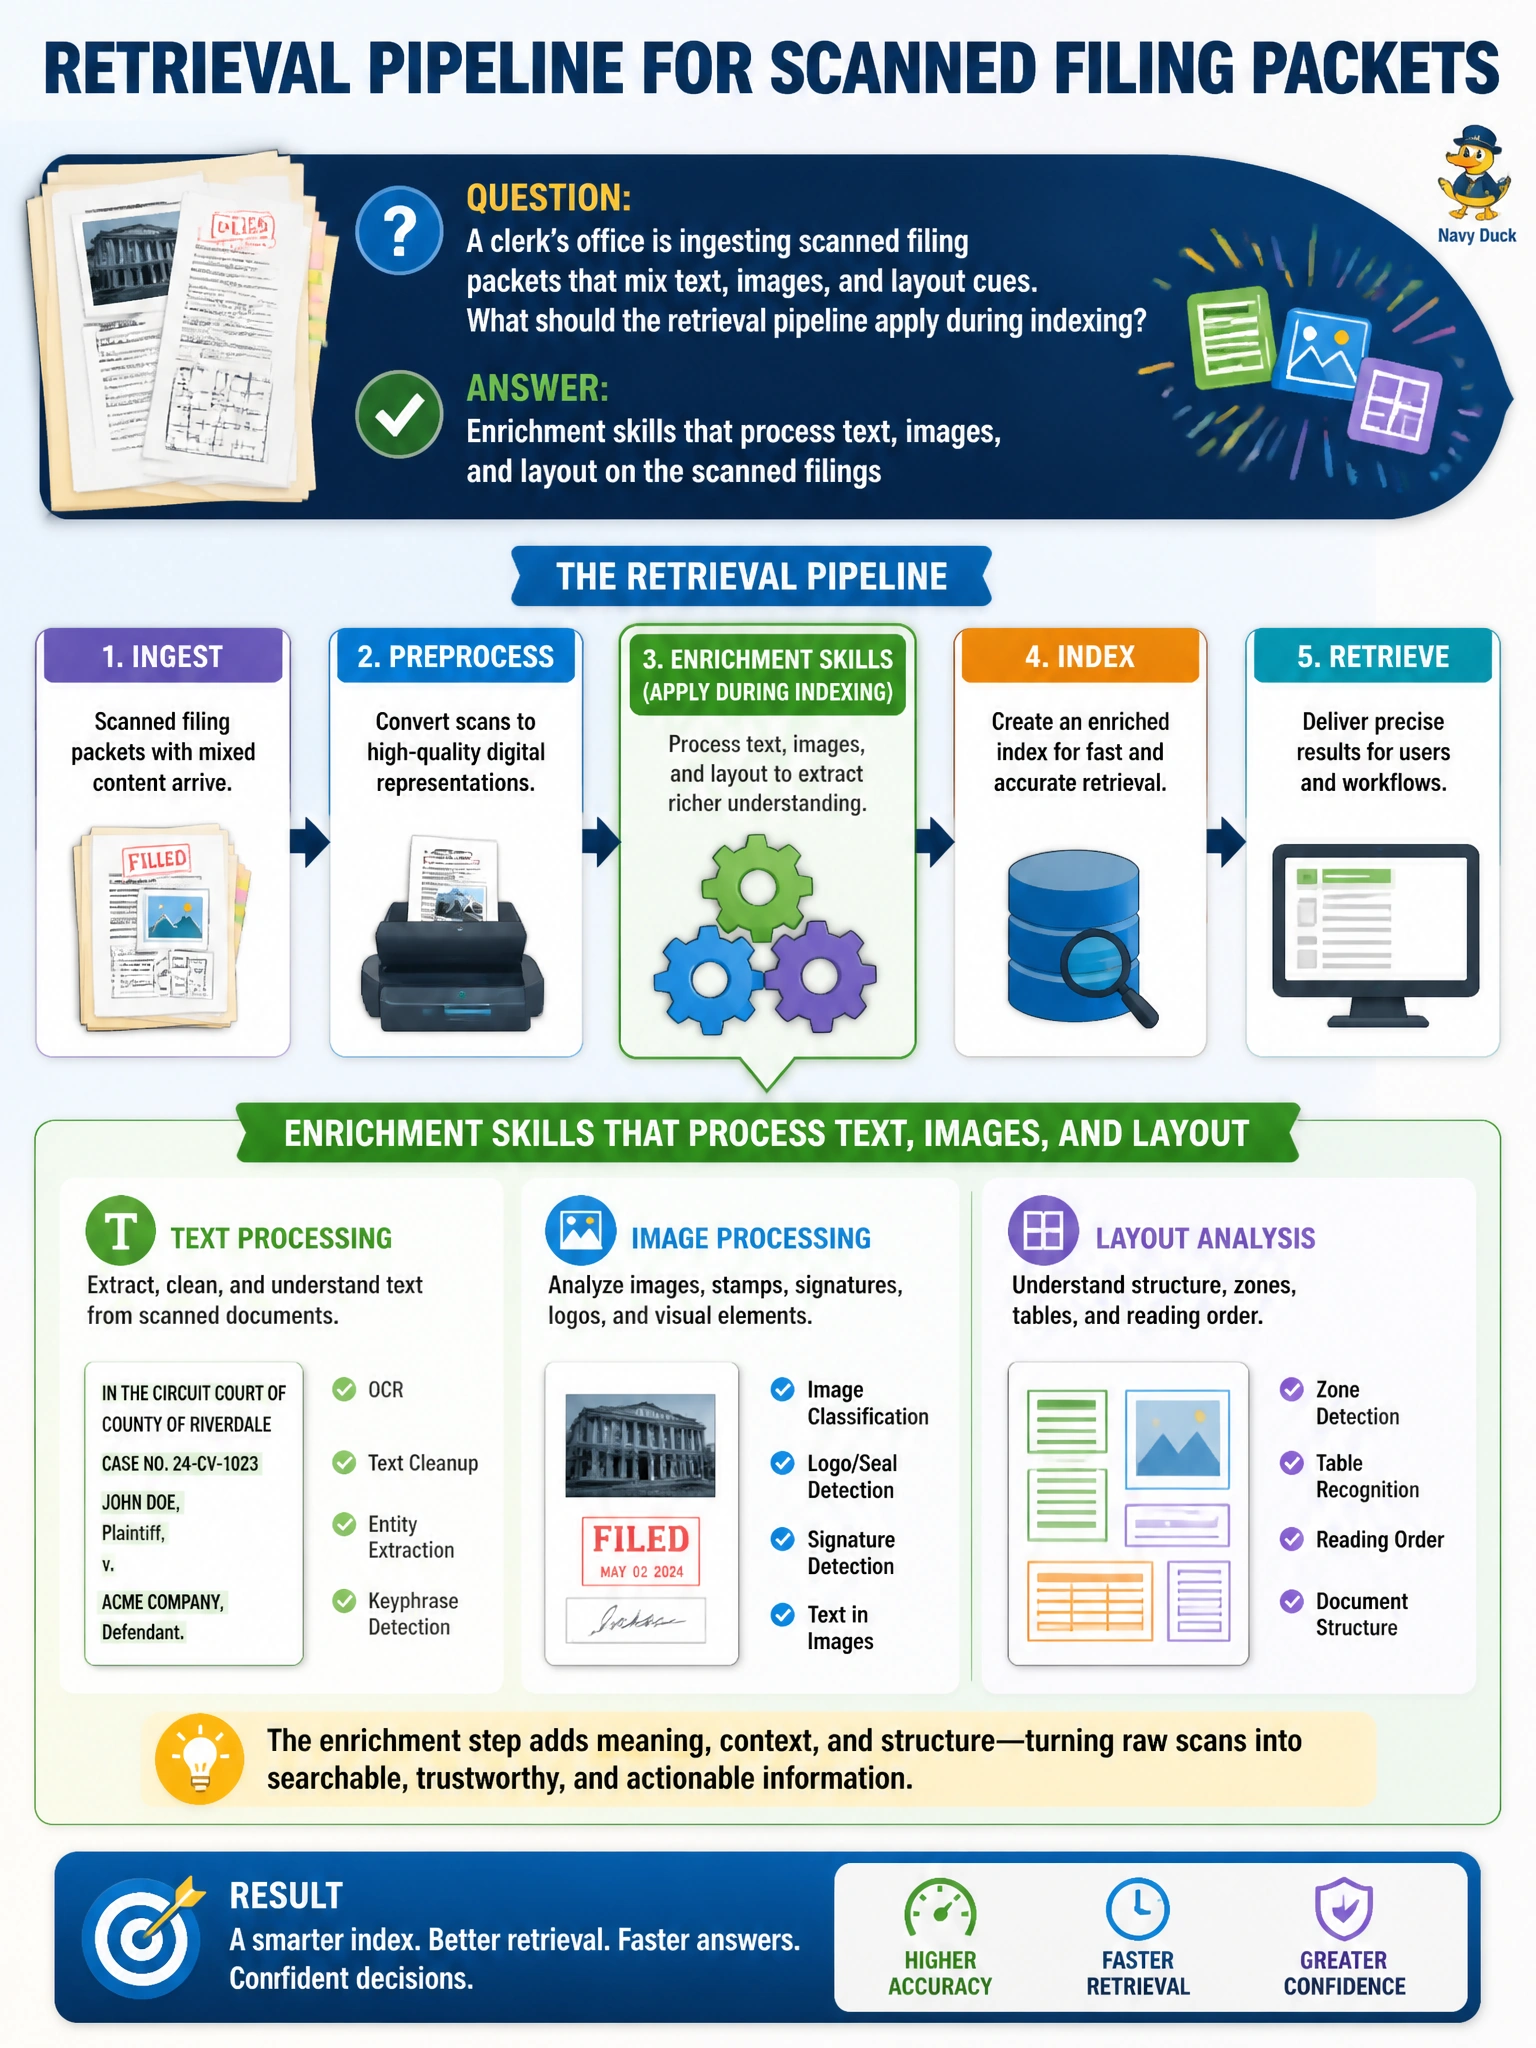
A clerk’s office is ingesting scanned filing packets that mix text, images, and layout cues. What should the retrieval pipeline apply during indexing?
Select an answer to reveal the explanation.
Short Explanation
Scanned filing packets are a messy mix of words, stamps, and layout. Enrichment skills turn that pile into searchable signals before the index goes live. An OCR skill alone can't process images and layout, and scoring profiles or semantic ranking only weight and re-rank at query time, so they won't build you the multimodal index you need.
Full Explanation
A clerk’s office indexing scanned filing packets that mix text, images, and layout cues must apply enrichment skills that process those modalities during ingestion. Scans are not plain text: stamps, seals, form boxes, handwritten marks, and reading-order layout all carry filing meaning. Enrichment turns pixels and structure into searchable fields and chunks so the municipal retrieval index can answer clerk and public queries against packet content. An OCR skill that extracts text, images, and layout on the scanned filings overstates OCR, which extracts printed text but does not supply full image and layout enrichment, so it cannot meet the multimodal indexing requirement. A scoring profile that weights text, images, and layout on the scanned filings only adjusts field weights for relevance tuning at query time and does not process those modalities during indexing. Semantic ranking that interprets text, images, and layout on the scanned filings re-ranks results at query time but does not enrich or index packet content during ingestion. Exam caveat: for multimodal scanned municipal packets, enrichment that handles text, images, and layout is the indexing requirement—not an OCR skill alone, a scoring profile weighting, or query-time semantic ranking. Operational check: run enrichment on representative filing packets covering typed forms, stamped pages, and mixed layouts; verify extracted text, image-derived signals, and layout-aware chunks land in the index; sample retrieval queries for docket and party facts before production cutover.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.