
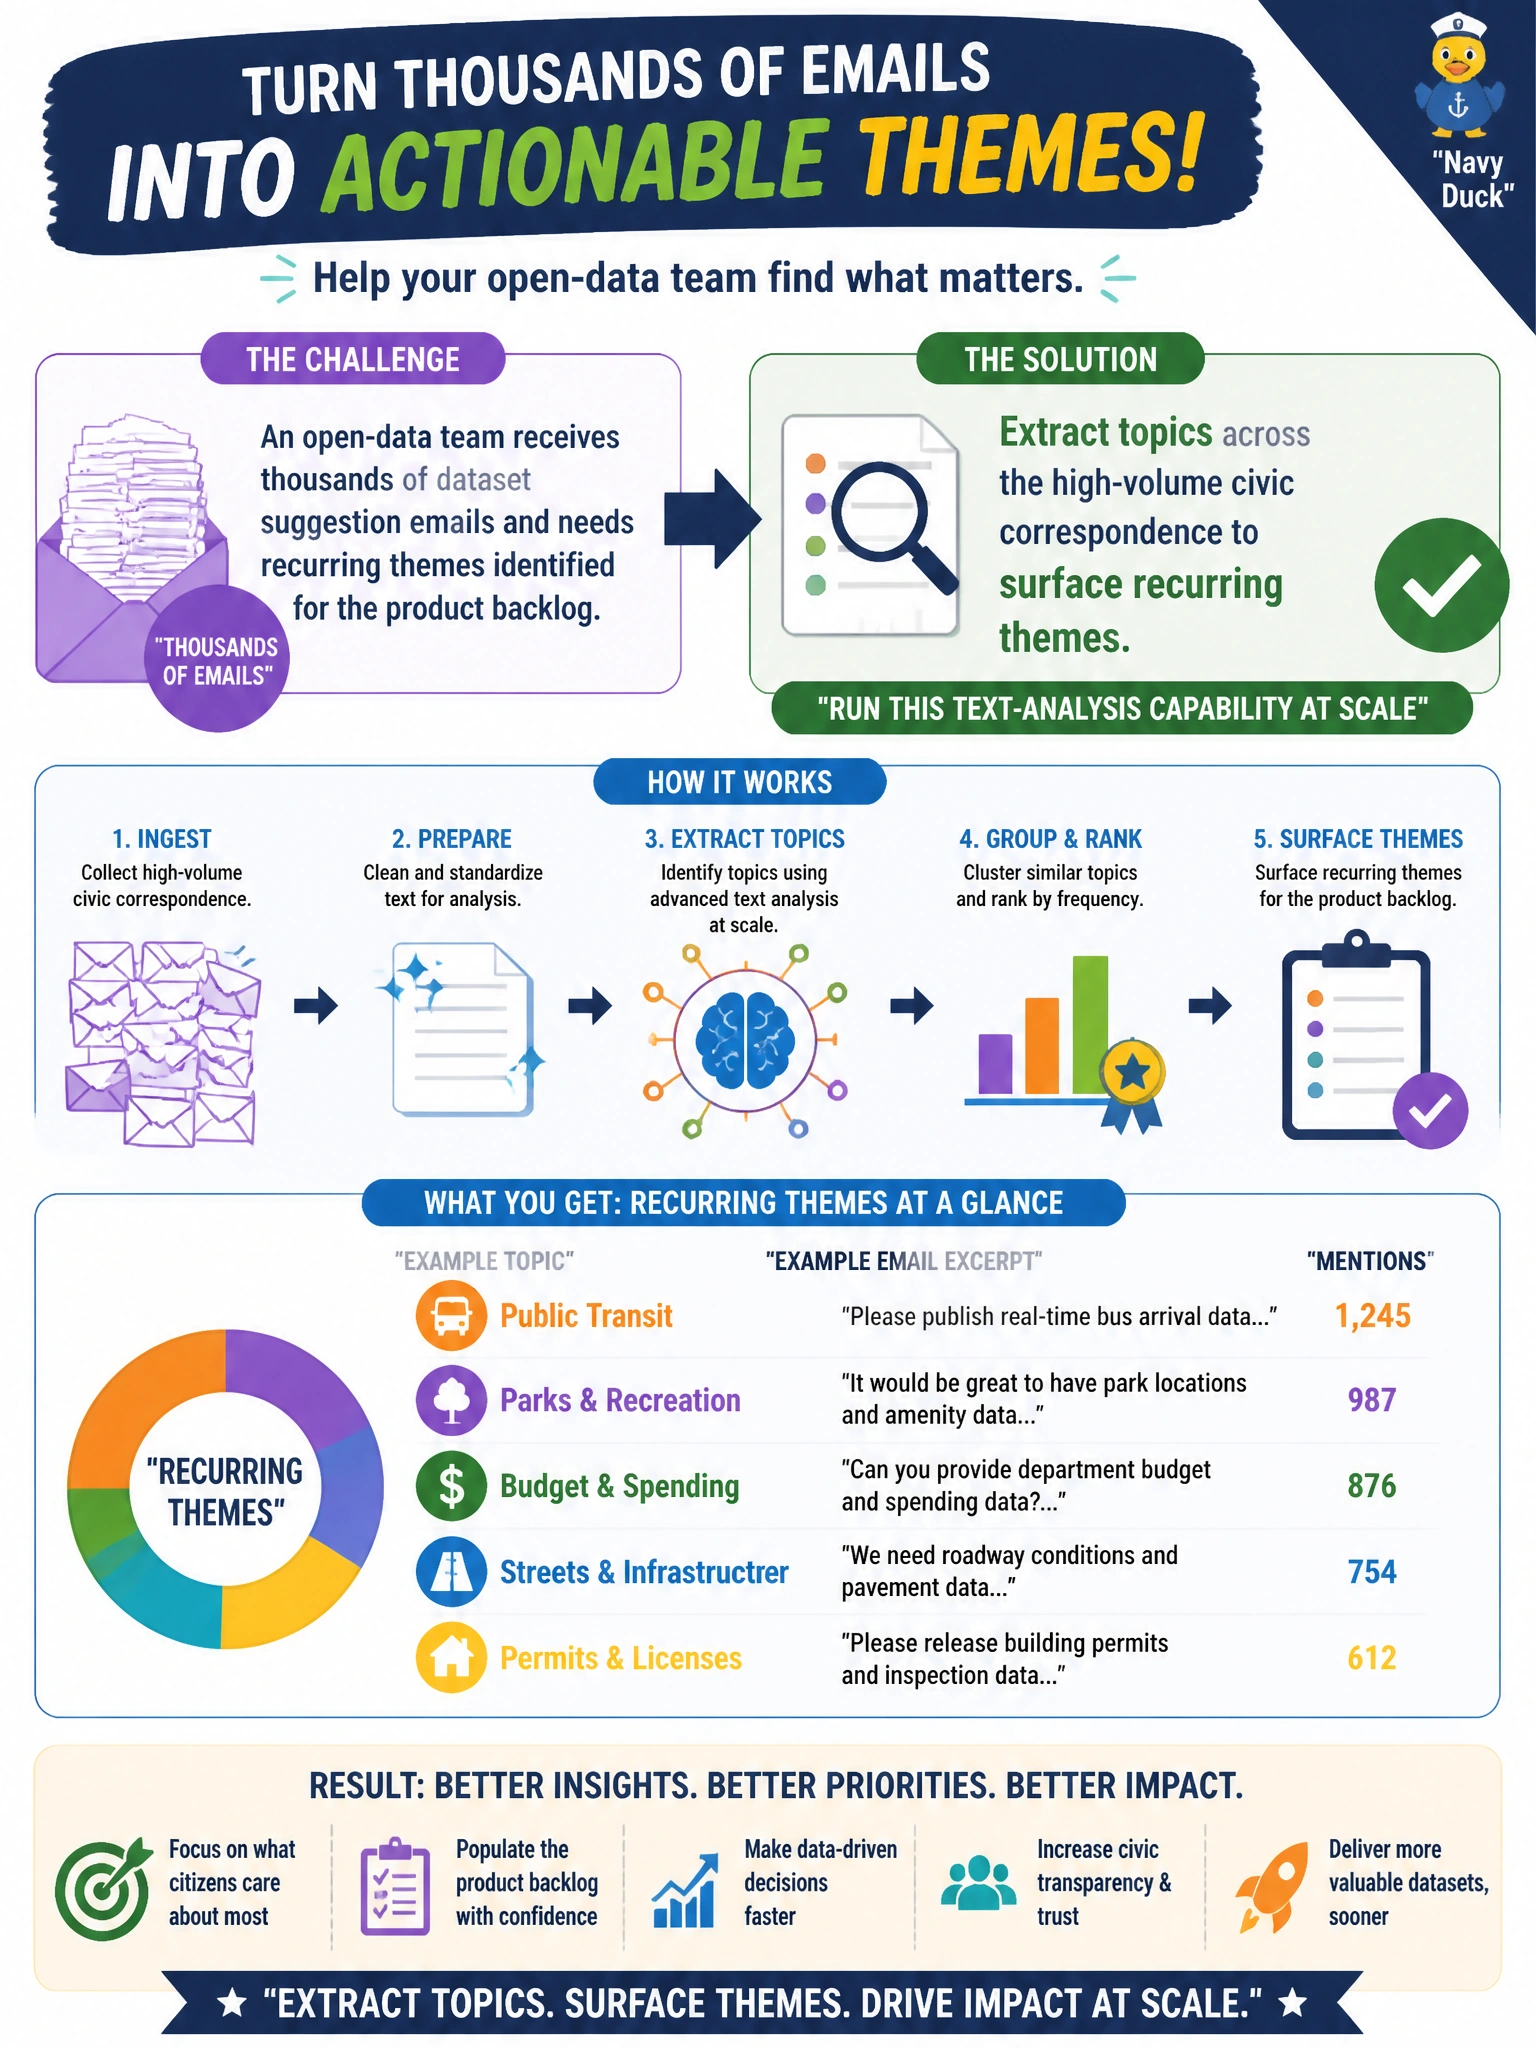
An open-data team receives thousands of dataset suggestion emails and needs recurring themes identified for the product backlog. Which text-analysis capability should they run at scale?
Select an answer to reveal the explanation.
Short Explanation
A flood of suggestion emails is like sorting a warehouse of sticky notes by theme. Topic extraction at scale finds the recurring asks so the open-data backlog is driven by patterns, not inbox panic. You'll still miss the patterns if you classify emails into preset buckets, pull out key phrases, or tag named entities, since none of those clusters feedback into true recurring topics.
Full Explanation
The open-data team receives thousands of dataset suggestion emails and needs recurring themes identified for the product backlog. Topic extraction (or topic modeling / theme clustering) at scale is the right text-analysis capability: it surfaces recurring asks across high-volume civic correspondence so backlog prioritization follows patterns rather than whoever emailed last. This keeps the municipal open-data roadmap evidence-based.
Classifying emails across the high-volume civic correspondence to surface recurring themes still assigns messages to a pre-defined taxonomy, so it cannot discover emergent themes nobody anticipated, which is exactly what open-ended topic extraction is for. Extracting key phrases across the high-volume civic correspondence to surface recurring themes pulls out salient terms but never clusters them into higher-level topics across the thousands of emails the backlog needs. Detecting named entities across the high-volume civic correspondence to surface recurring themes catalogs people, places, organizations and other entity mentions but never groups them into recurring topics, so the cross-corpus theme question stays unanswered. Each distractor performs a genuine text-analysis step that still leaves the cross-corpus theme question unanswered.
Exam caveat: topic extraction finds themes across a corpus; it is not the same as classifying emails, extracting key phrases, or detecting named entities across the correspondence, even when those are framed as surfacing recurring themes. When stems emphasize “recurring themes” and “at scale,” prefer topic/theme extraction over classification, key-phrase extraction, or named-entity detection alone.
Operational check: batch a month of suggestion emails, extract topics, map clusters to backlog epics, and have product owners validate that clusters match real constituent demand (e.g., parcel APIs, transit GTFS gaps). Re-run periodically, archive outdated themes, and keep example emails per topic so engineers can inspect the underlying civic asks.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.