
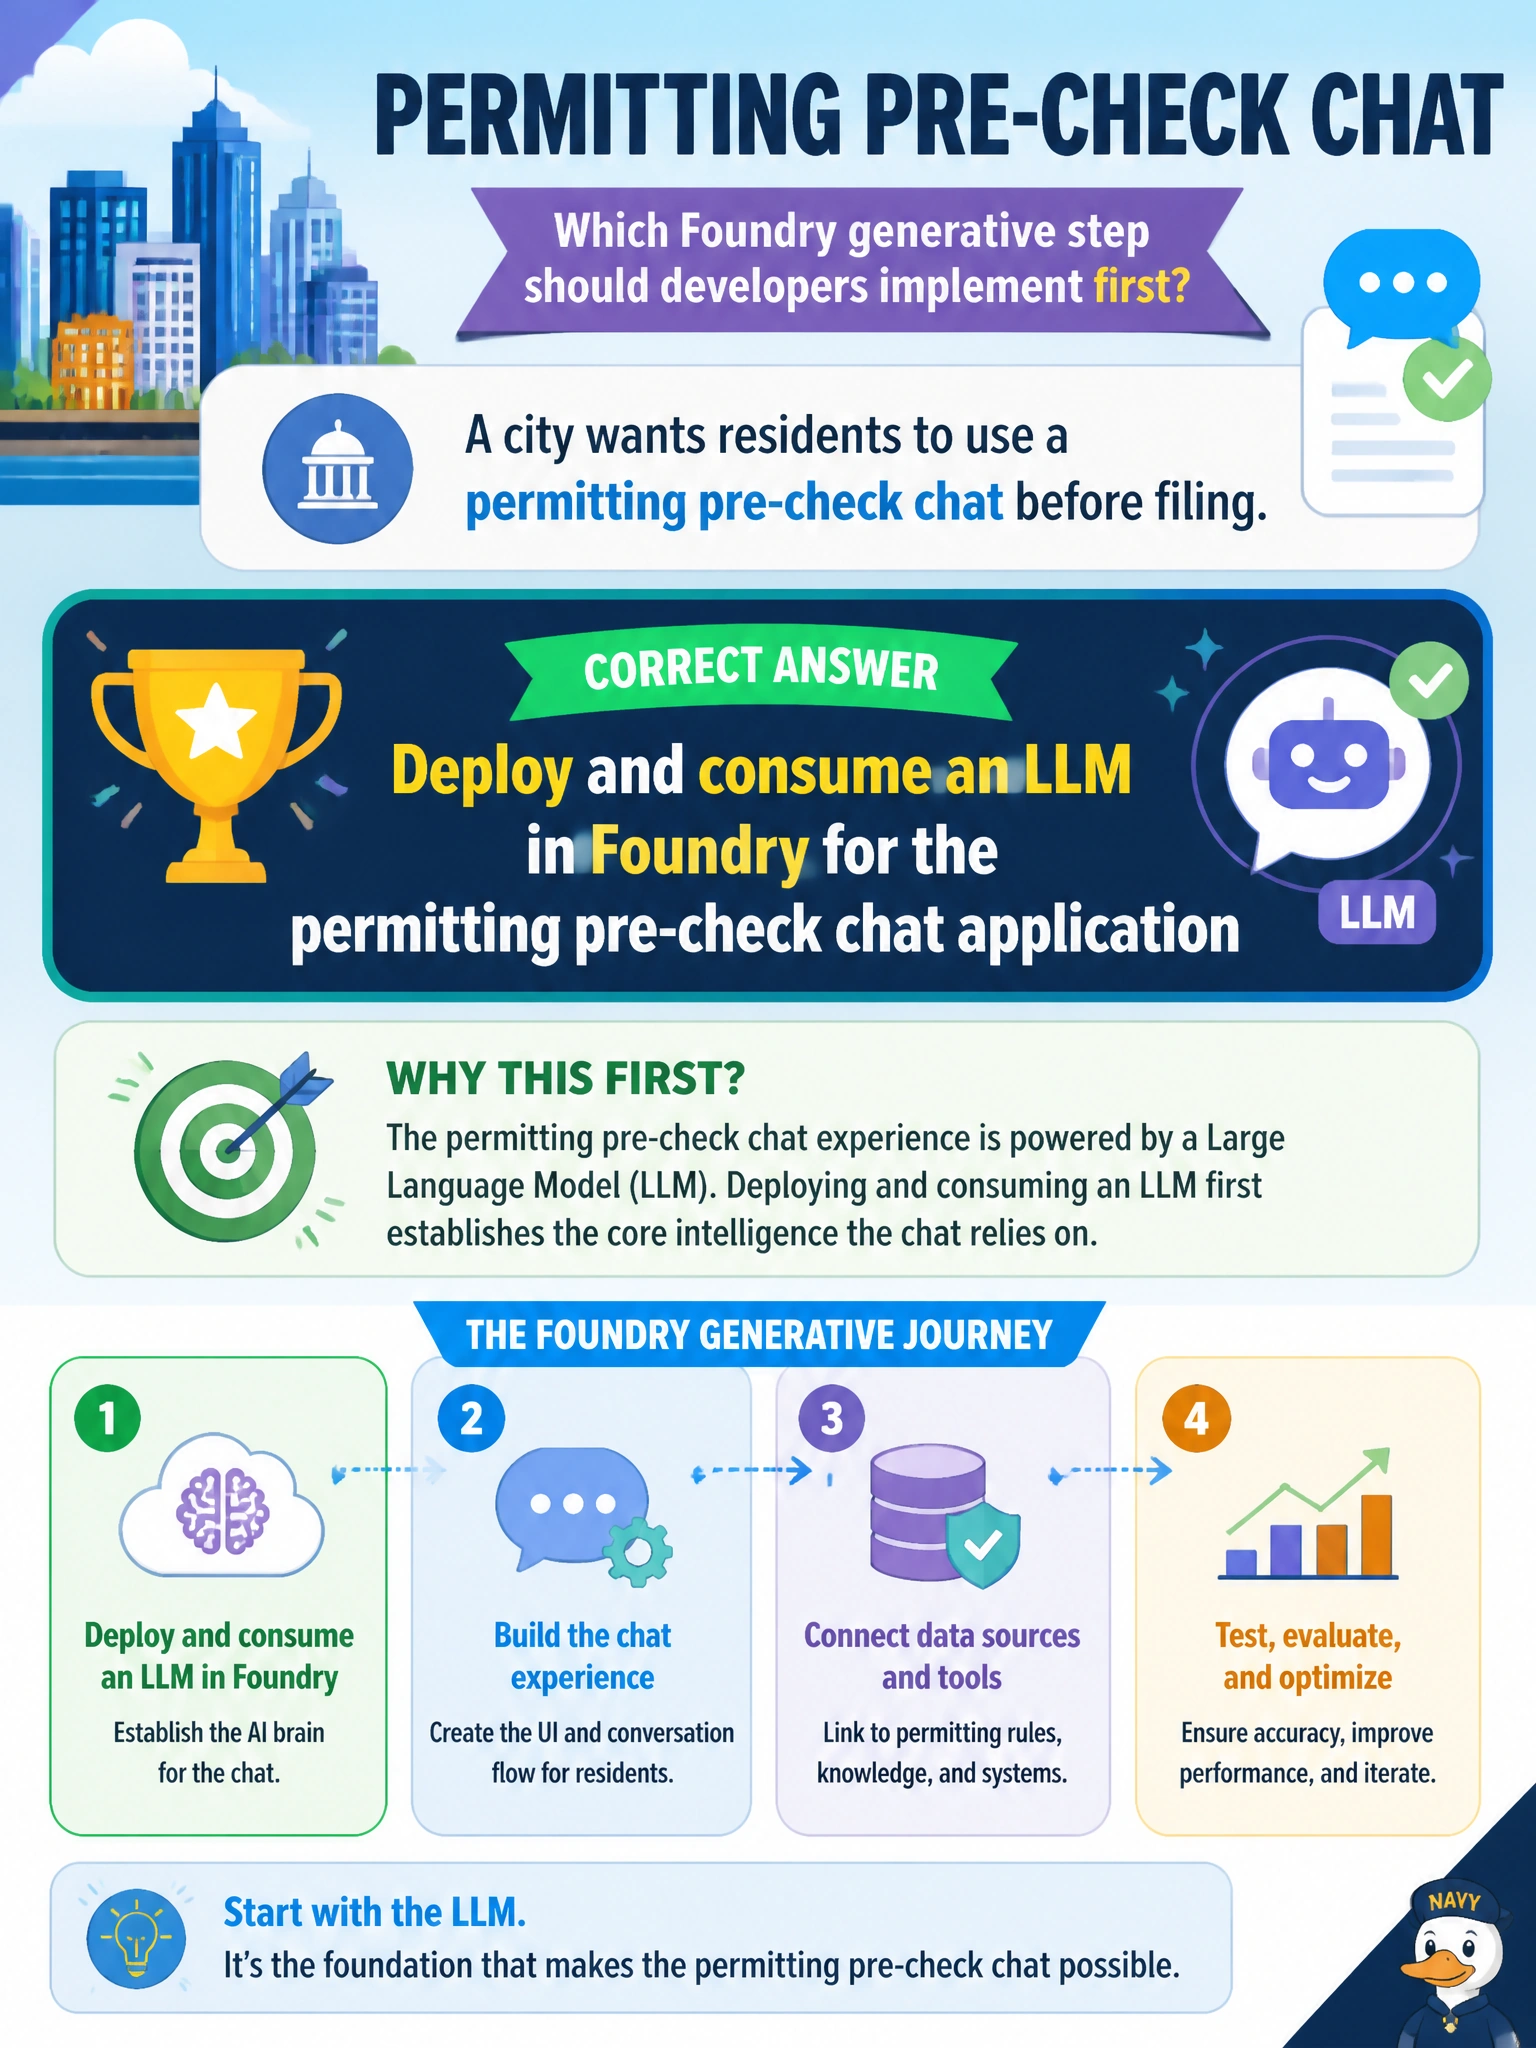
A city wants residents to use a permitting pre-check chat before filing. Which Foundry generative step should developers implement first for that experience?
Select an answer to reveal the explanation.
Short Explanation
Pre-check chat is a conversation, so you'll need a living language model on the other end—not just a Foundry vector index over permit codes for the pre-check chat that can't generate replies by itself. Deploy the LLM in Foundry and wire the city app to consume it. That's the foundation before you add prompt workflows, retrieval, or content filters.
Full Explanation
Deploying and consuming an LLM in Foundry for the permitting pre-check chat is the first generative step that matches the city's resident experience goal. A pre-check chat must interpret natural-language questions about requirements, documents, and eligibility hints, then generate helpful conversational replies. That pattern starts with a deployed language model in Microsoft Foundry and an application path that authenticates and calls it—not with a Foundry vector index over permit codes for the permitting pre-check chat that cannot generate replies by itself. Building a Foundry vector index over permit codes for the permitting pre-check chat supports retrieval but does not deliver a chat pre-check without a deployed language model to generate responses. Designing a Prompt Flow chat workflow with permit prompts for the pre-check chat application organizes prompts and conversation logic but does not deliver the interactive generative assistance residents need until a model is deployed and consumed. Configuring Foundry content filters for permit prompts in the permitting pre-check chat provides safety guardrails for a running system but does not create the real-time conversational pre-check until the LLM is deployed and consumed. Exam caveat: Foundry generative solutions begin with deploy-and-consume LLM patterns; later RAG, tools, and evaluations build on that foundation. Operational check: confirm the permitting app configuration points at a Foundry deployment endpoint, can obtain a token, and returns generative responses for representative pre-check prompts before layering retrieval or workflow orchestration.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.