
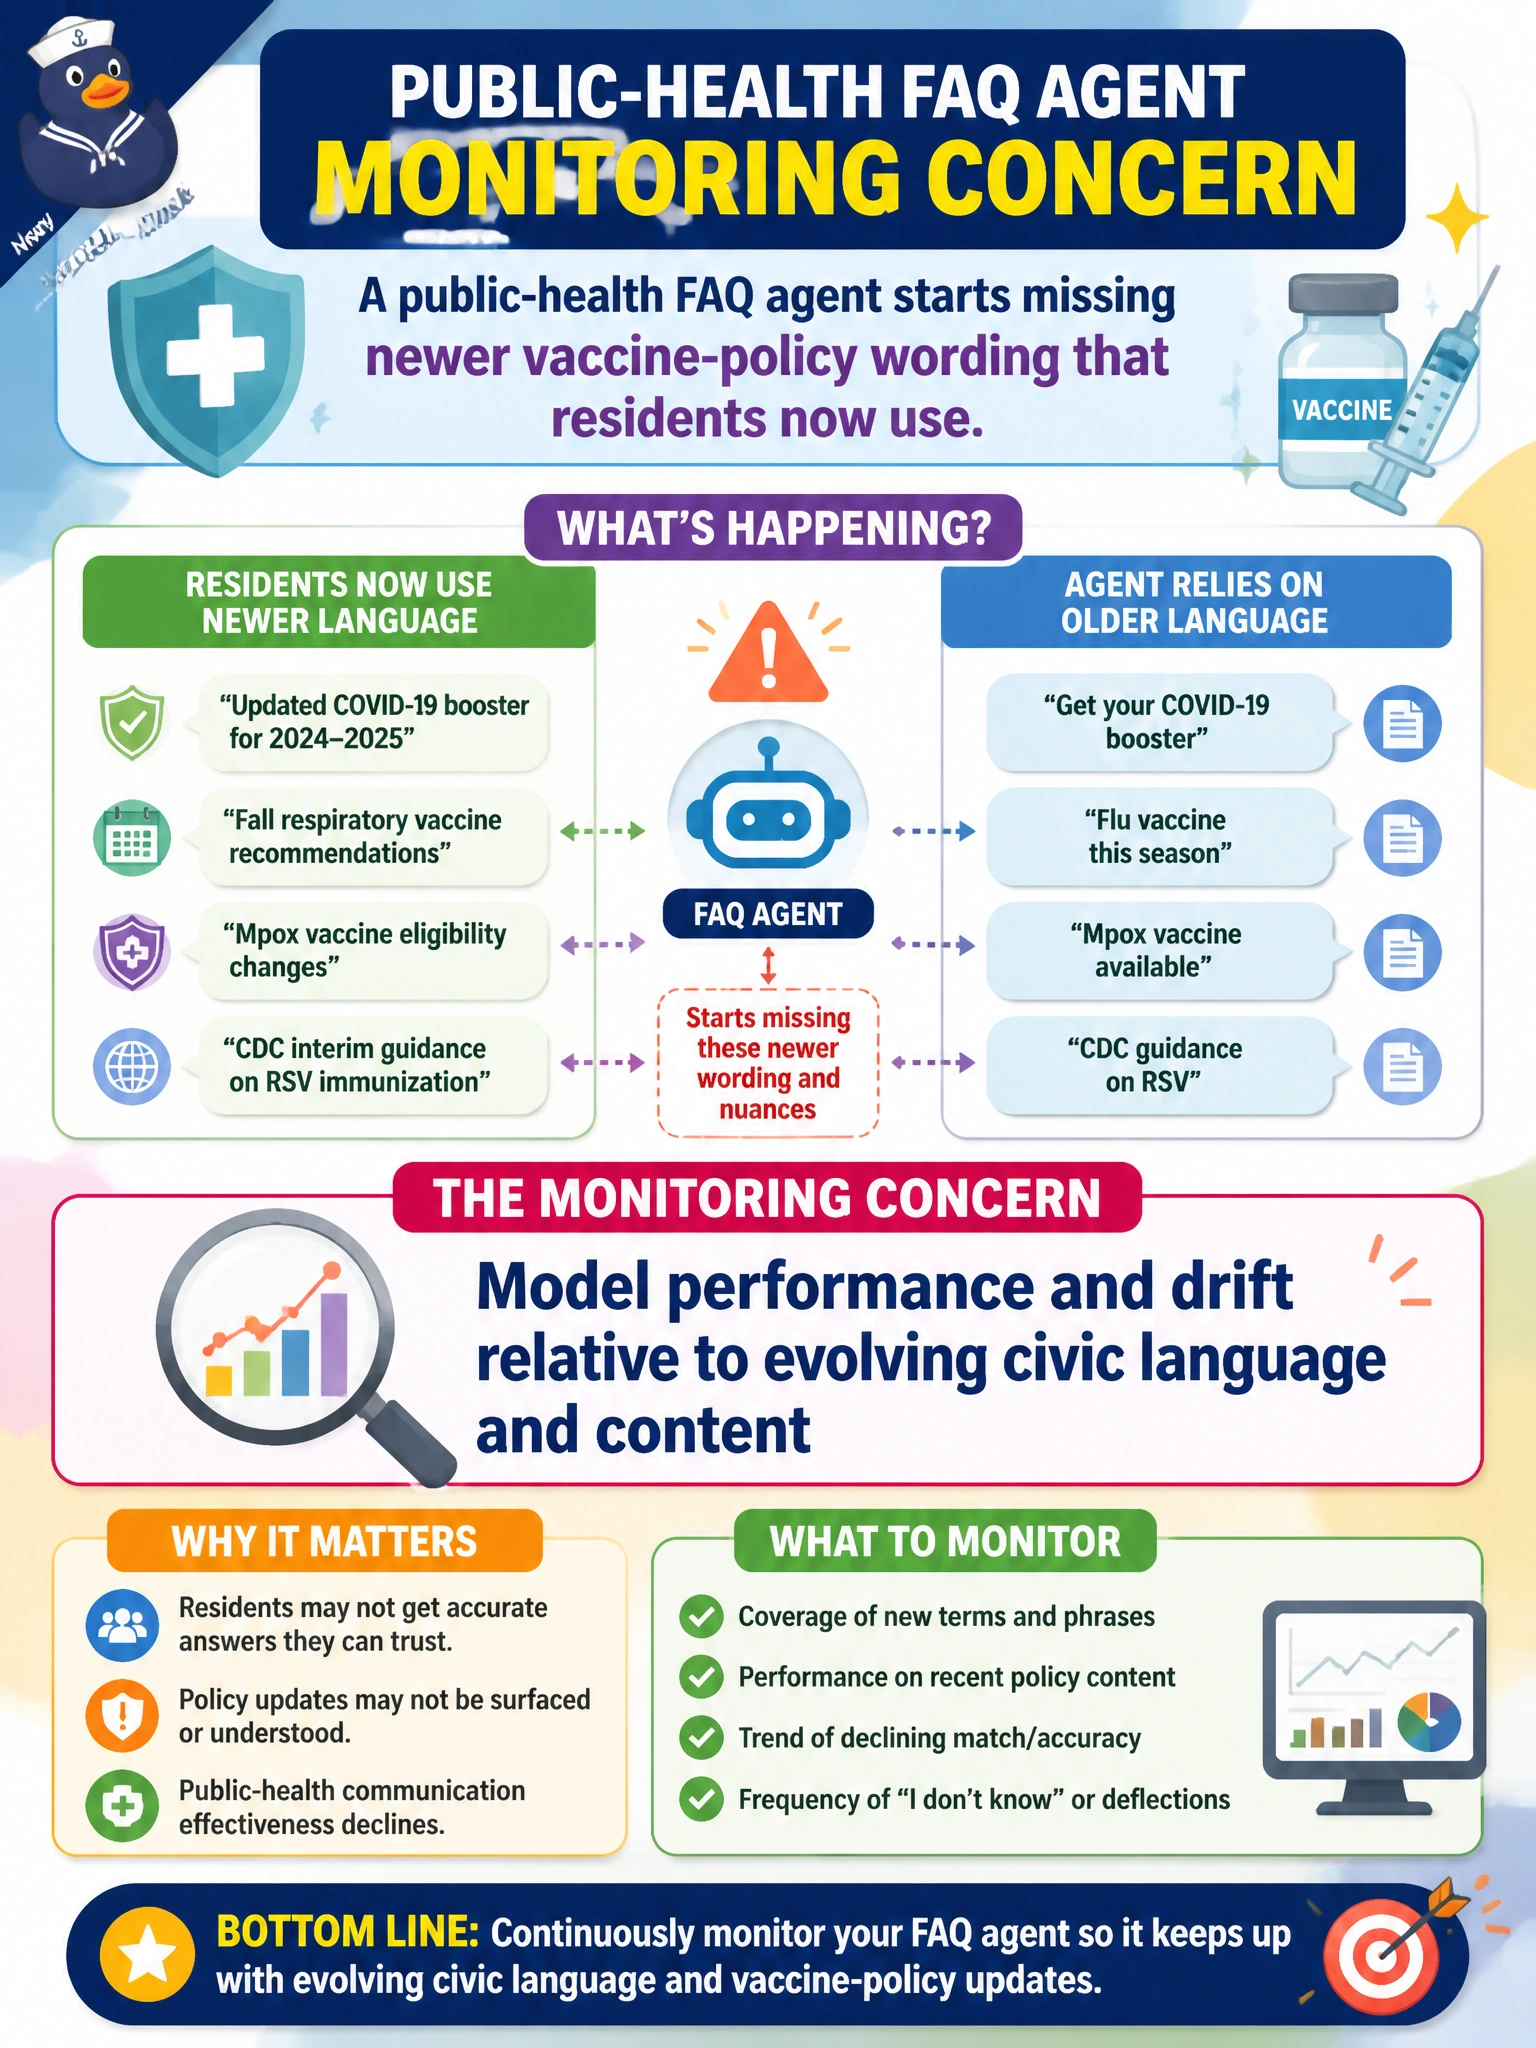
A public-health FAQ agent starts missing newer vaccine-policy wording that residents now use. What monitoring concern does this raise?
Select an answer to reveal the explanation.
Short Explanation
Resident questions morph when public-health guidance updates—like callers using new street names the old phone book never listed. Watching model performance and drift tells you the agent is slipping on the new vocabulary and facts. Refresh evaluation sets and grounded content so answers stay current.
Full Explanation
When a public-health FAQ agent misses newer vaccine-policy wording that residents now use, the monitoring concern is model and solution performance drift relative to evolving civic language and content. The concern is valid because municipal FAQ quality depends on both the underlying model behavior and the grounded content/retrieval stack staying aligned with current policy vocabulary; as guidance pages and resident phrasing change, intent recognition, retrieval queries, and answer phrasing can degrade even if infrastructure metrics stay green. Drift monitoring is how public-health AI ops detect that the agent’s effective competence has moved away from today’s civic reality.
Monitoring data drift in prompt token counts for FAQ answers with newer civic terms fails because changing token counts only show that inputs got longer or tokenized differently, not whether the agent still understands current vaccine-policy wording—count shift is a surface input statistic, not a measure of whether answer quality has degraded.
Validating groundedness using frozen policy snapshots for newer resident queries fails because the agent can stay aligned with old snapshots while its answers silently fall out of step with newer vaccine-policy language—groundedness against frozen snapshots measures consistency with the past, not whether what it says is current.
Monitoring concept shift in thumbs-up feedback rates for answers using newer terms fails because residents who do not know the newer vaccine-policy wording themselves often cannot tell the agent’s answer is stale, so feedback patterns can stay level even as the agent drifts behind current guidance—the shift captures changing satisfaction behavior, not the agent’s performance on evolving civic language.
Exam caveat: “drift” here may be content drift, embedding/index staleness, or model behavior change after a deployment—treat the symptom as a quality regression and isolate the layer with eval sets, not with a single vague alarm. Operational check: maintain a living golden-question set that includes new policy phrases after each health update, track answer accuracy and retrieval hits over time, and alert when scores fall so content refresh or prompt/model changes can be scheduled before clinic phone lines absorb the confusion.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.