
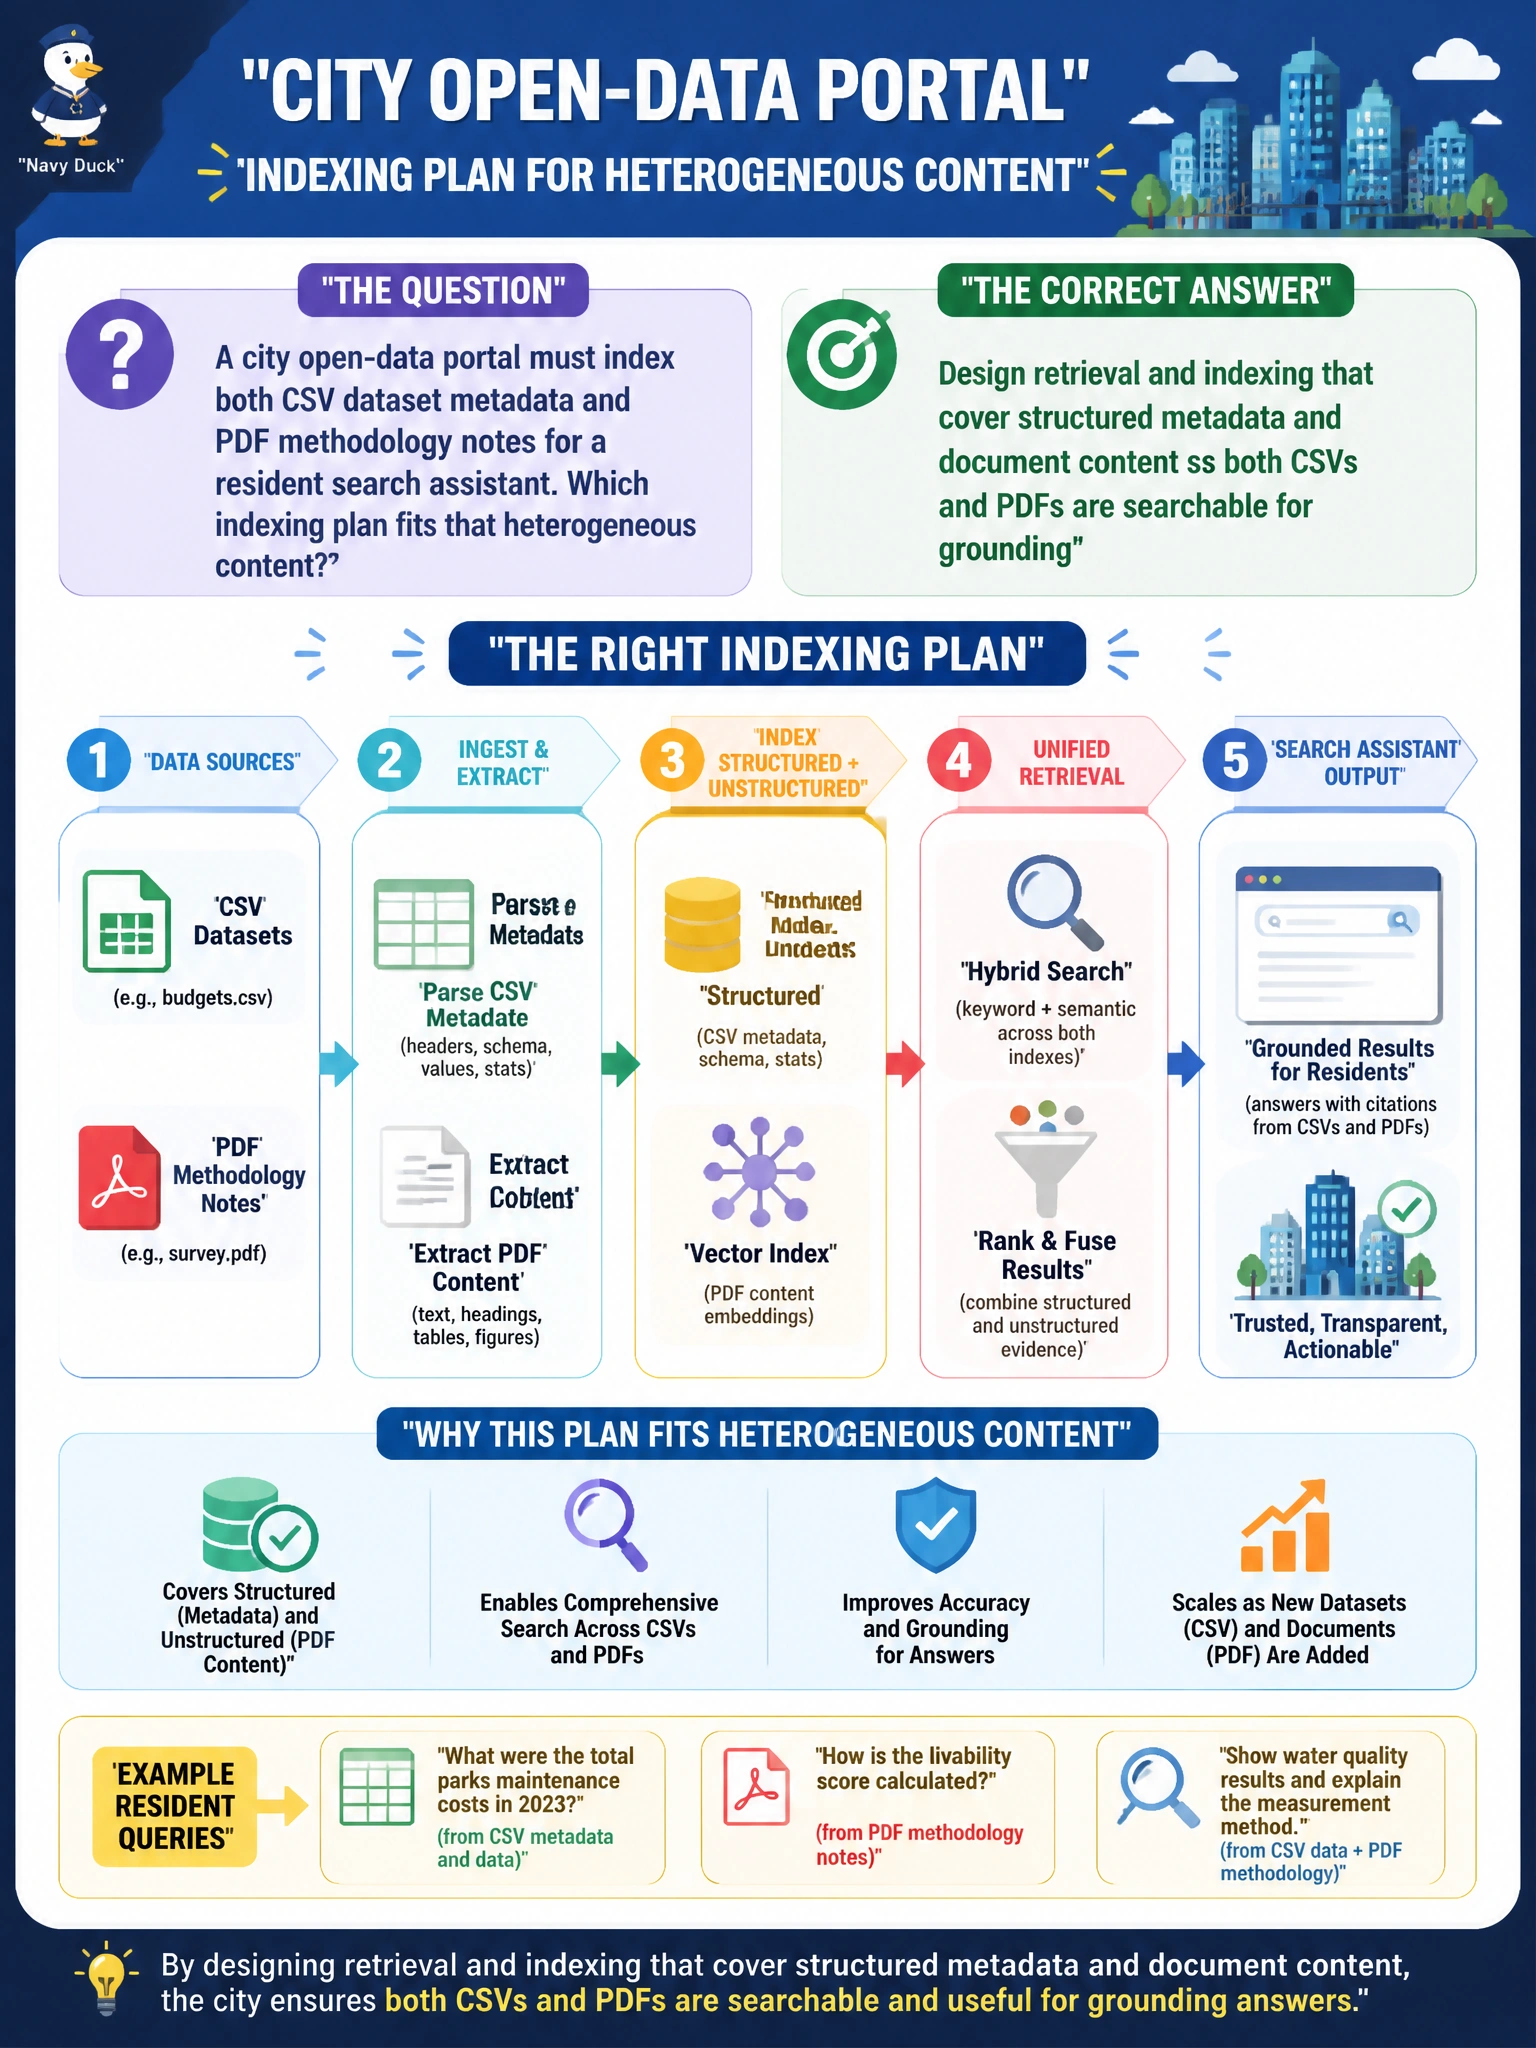
A city open-data portal must index both CSV dataset metadata and PDF methodology notes for a resident search assistant. Which indexing plan fits that heterogeneous content?
Select an answer to reveal the explanation.
Short Explanation
Open data is a mixed shelf—spreadsheet labels next to PDF how-to notes. Index both the structured metadata and the document text so the assistant can find either kind of clue.
Full Explanation
A city open-data portal assistant that must use both CSV dataset metadata and PDF methodology notes needs retrieval and indexing that cover structured metadata and document content. Heterogeneous civic corpora are common: spreadsheets carry field-level metadata while PDFs carry narrative methodology. An indexing plan that includes both makes grounding possible across the portal's real mix of artifacts so residents can find either dataset descriptors or methodology explanations.
Designing retrieval and indexing over CSV cell text and PDF content with embeddings so both CSVs and PDFs are searchable for grounding fails because it treats CSVs as flat cell text rather than structured metadata and relies on embeddings alone, so field-level descriptors lose filterability and cannot be distinguished from narrative methodology for grounding. Designing retrieval and indexing with filters for CSV metadata and search for PDFs so both CSVs and PDFs are searchable for grounding fails because it limits CSV descriptors to filter-only use rather than retrievable content and does not provide joint coverage of structured metadata and document content, so a resident query cannot retrieve and cite both dataset descriptors and methodology explanations together for grounding. Designing retrieval and indexing over combined CSV and PDF text with vectors so both CSVs and PDFs are searchable for grounding fails because flattening heterogeneous artifacts into one vector space treats catalog fields as plain text without metadata filters, so a dataset descriptor cannot be reliably distinguished from a methodology passage for grounding.
Exam caveat: structured fields may use different index types than PDF chunks; plan metadata filters alongside embeddings so catalog fields and narrative notes remain distinguishable. Operational check: query for a dataset by column meaning and by methodology phrase, confirm both CSV metadata and PDF passages can be retrieved and cited, and monitor index refresh when portal datasets or methodology PDFs update.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.