
A host already uses progressive discovery, and midway through a conversation the model finds three more tools it needs. The LLM provider caches the prompt prefix, including the tools array. How should the host add those definitions without throwing away that cache?
Select an answer to reveal the explanation.
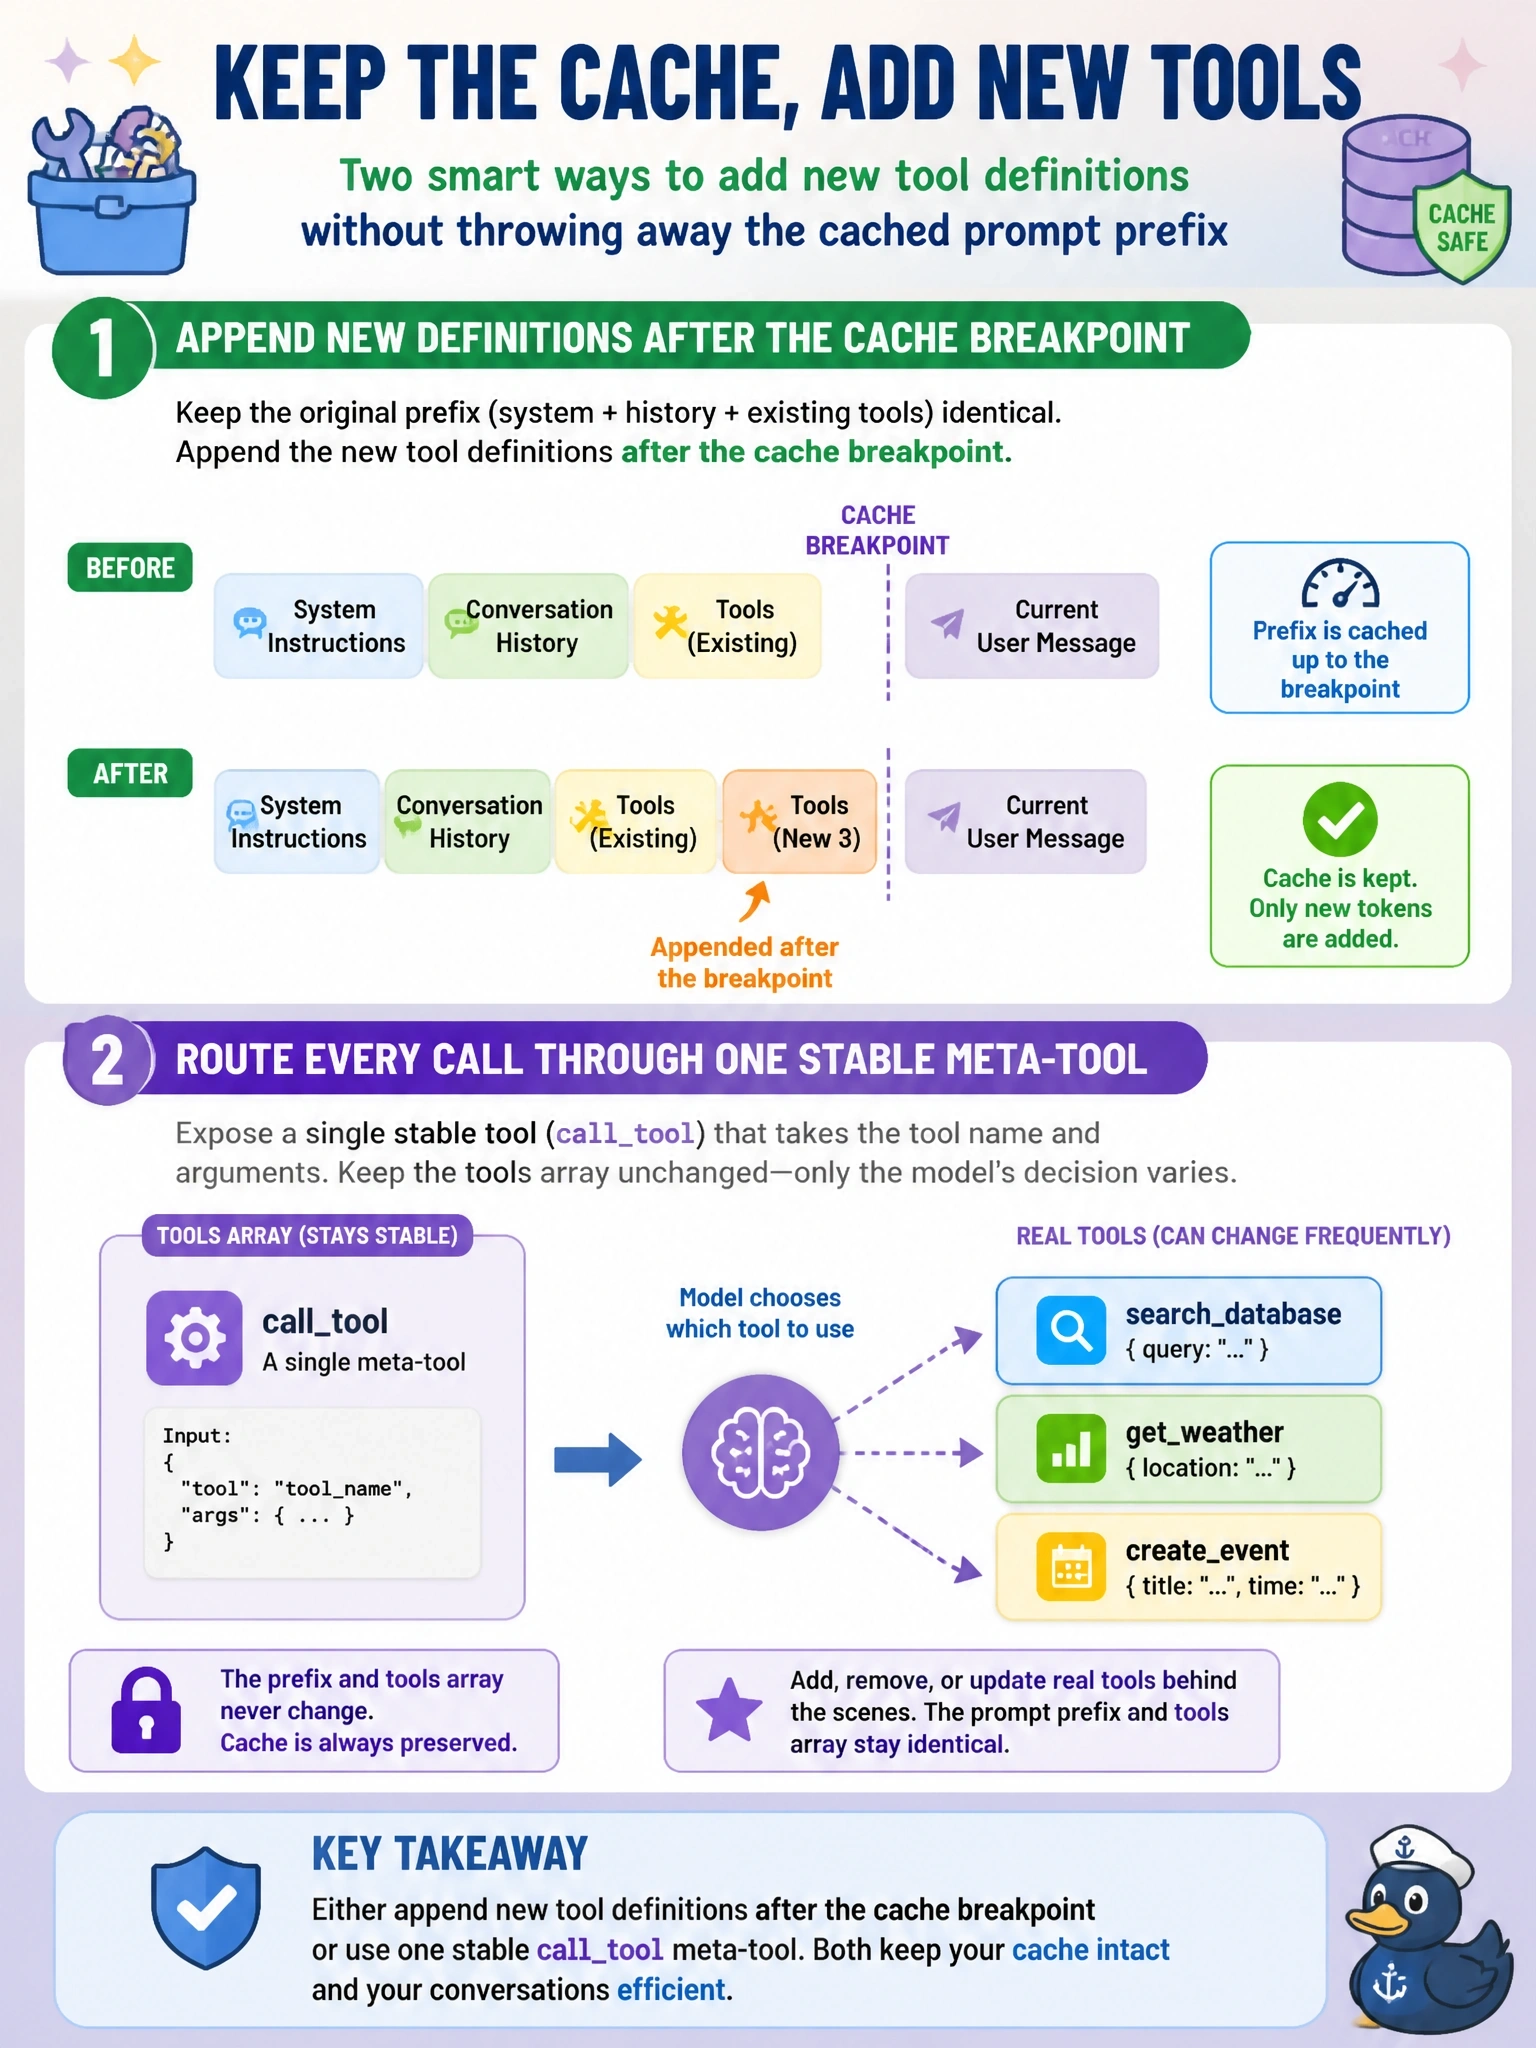
Short Explanation
Think of the prompt cache as a bookmark: shuffle the pages in front of it and you lose your place. You add the new tools at the end, or never change the list at all. The trap is alphabetical re-sorting, which sounds tidy but invalidates the cached prefix every time.
Full Explanation
Most LLM providers cache the prompt prefix, and that prefix includes the tools array. The client best-practices guidance warns that adding or removing tool definitions mid-conversation invalidates the cache, and the miss can cost more tokens than progressive discovery saved. To preserve it, the host appends newly discovered definitions after the cache breakpoint rather than re-sorting the array, or exposes a single stable call_tool meta-tool taking a name and arguments so the array never changes. Rebuilding the array in alphabetical order moves existing entries, so the cached prefix no longer matches even though the order is deterministic. Re-fetching tools/list from every server and replacing the array adds round trips the guidance avoids by memoizing definitions host-side, and swapping the array again breaks the prefix. Dropping unused tools to hold the size constant is still a removal, which changes the prefix; the guidance treats disconnection and removal as a conversation-boundary operation, not a per-turn one. Exam caveat: deterministic server ordering helps the first turn, but host-side edits mid-conversation are what break caching here. Operational check: log provider cache-hit metrics across turns where discovery adds tools and confirm the hit rate holds.