
A team building a brand-new MCP server wants LLM completions to support the server's own internal reasoning. What does the 2026-07-28 specification recommend?
Select an answer to reveal the explanation.
Short Explanation
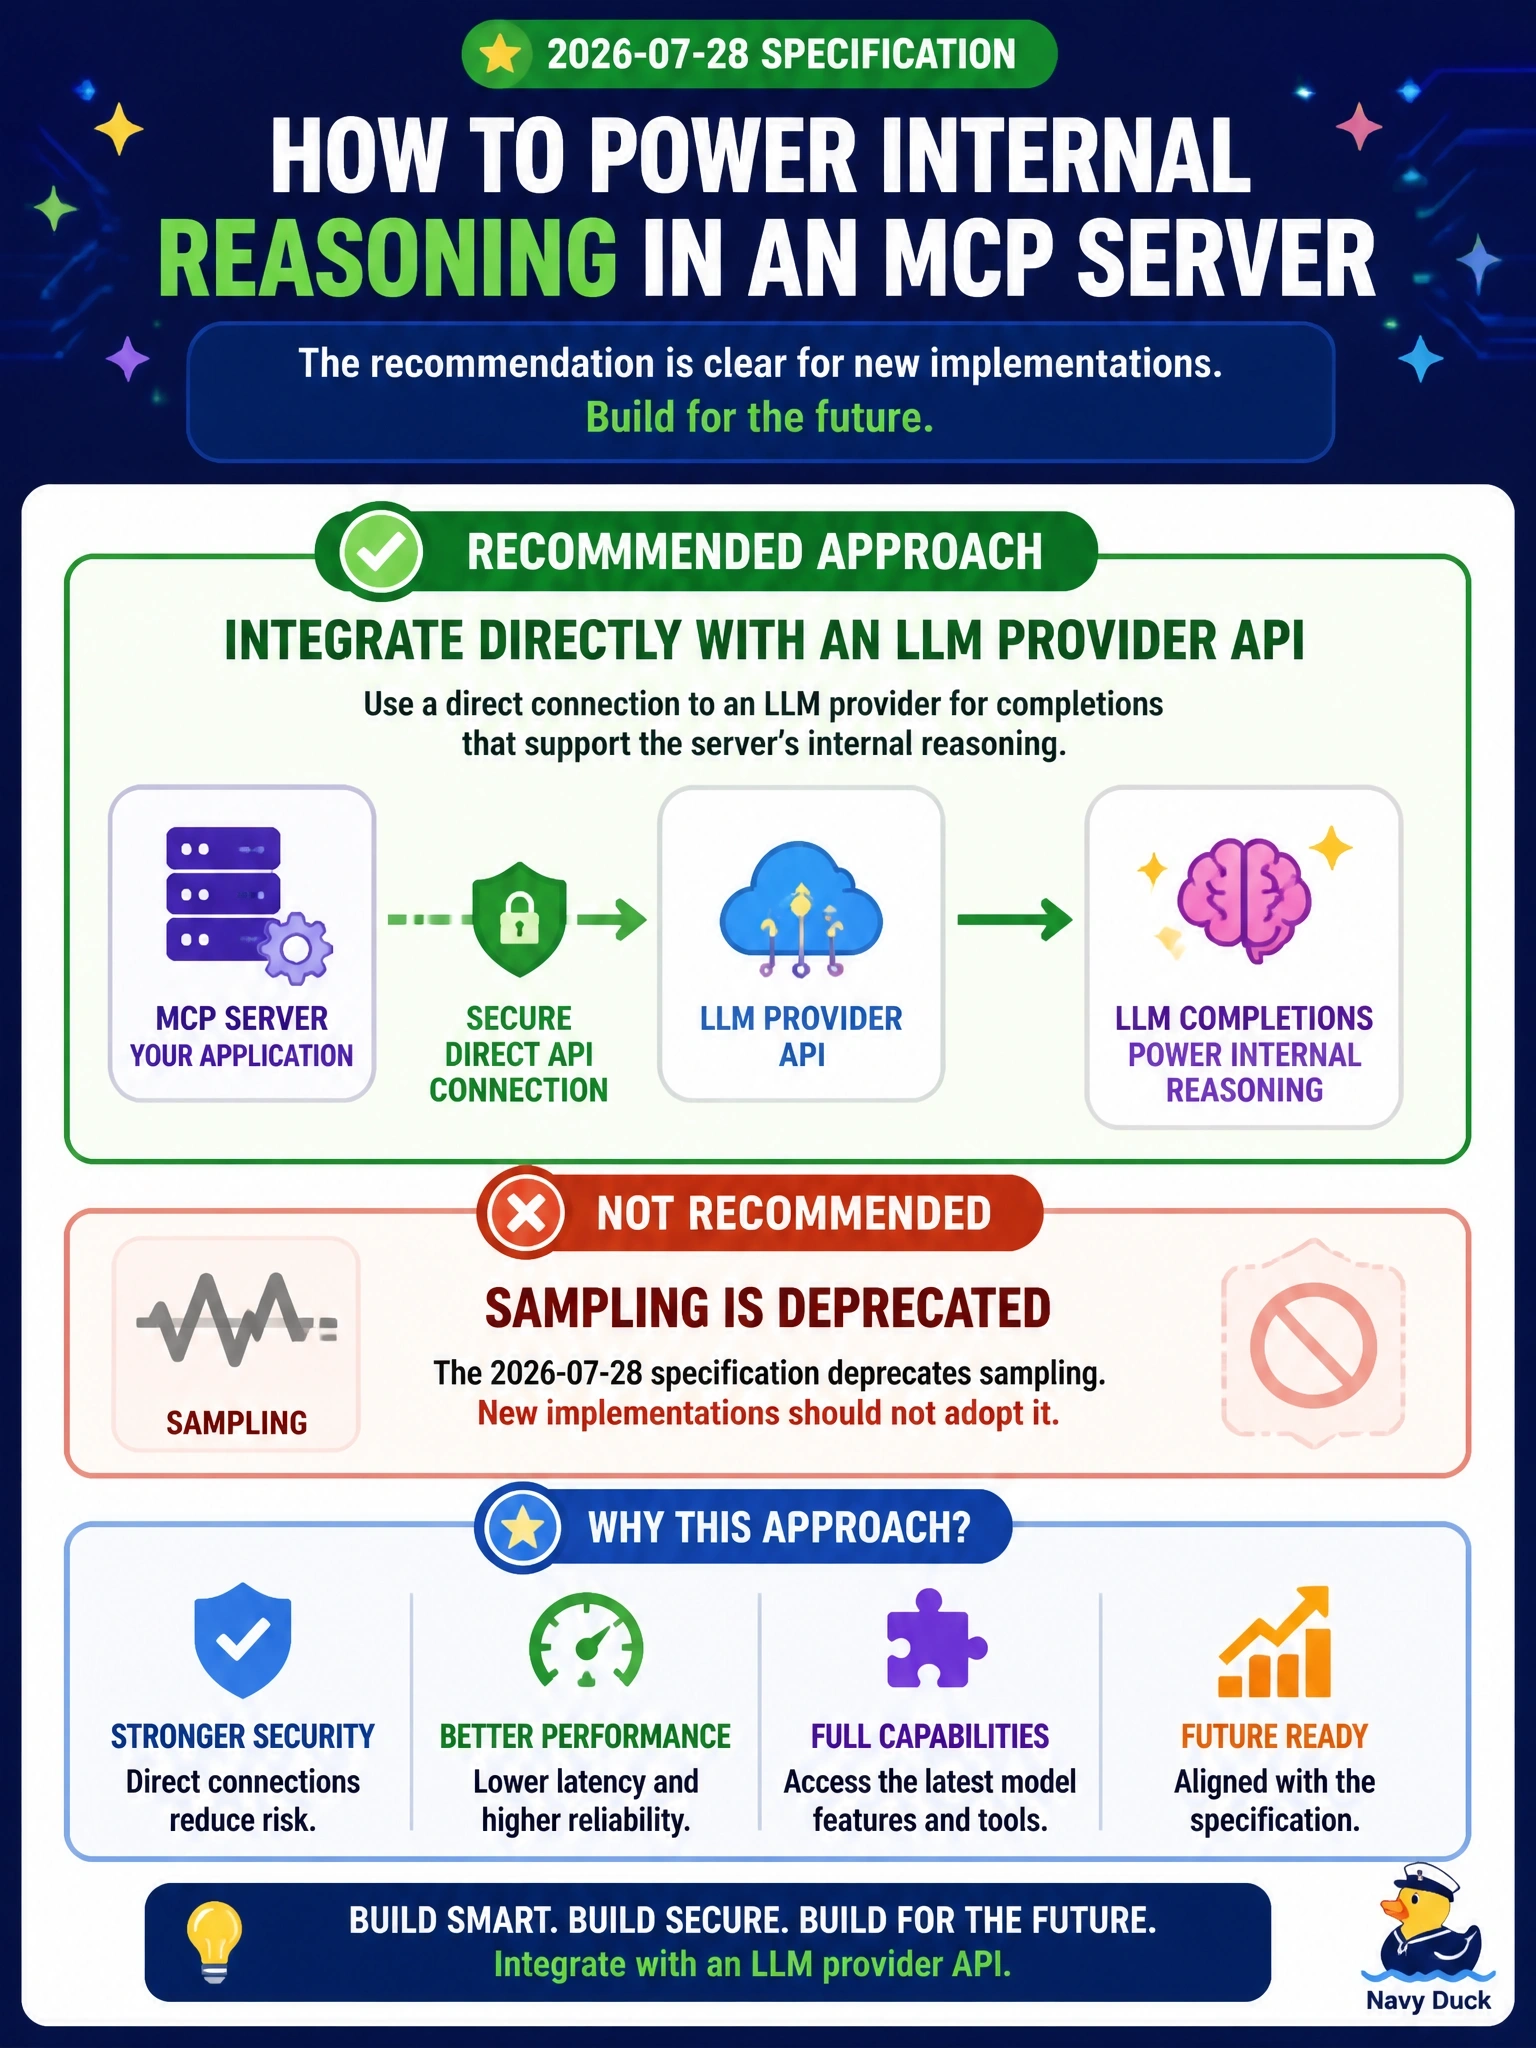
Sampling used to let a server borrow your client's model. It's now deprecated, so you'd wire your server straight to a model provider instead. Picking sampling because it still works is the trap.
Full Explanation
Sampling allowed servers to request language model completions from the client's AI application. As of protocol version 2026-07-28 it is deprecated: under the feature lifecycle policy it remains in the specification for at least twelve months, but new implementations SHOULD NOT adopt it, and existing implementations SHOULD migrate to integrating directly with LLM provider APIs. A new server that needs completions for its own reasoning should therefore call a provider API itself. Using sampling through an InputRequiredResult describes how deprecated sampling still works in this revision, delivered inside a result rather than as a separate request, but being functional is not the same as being recommended, and the deprecation guidance says new implementations should not adopt it. Sending sampling/createMessage as a server-initiated request is doubly wrong, because servers no longer send JSON-RPC requests of their own on any stream. Roots are also deprecated, and they exposed directory boundaries, not conversation history; the full conversation stays with the host by design. Exam caveat: the includeContext values thisServer and allServers are deprecated as well and will be removed no later than sampling itself. Operational check: review the server design and confirm it calls a provider API directly, with no sampling/createMessage input requests in its results.