
A host places each server's tool list in the model's context on every turn and wants better prompt-cache hit rates with its LLM provider. Which server behavior supports this goal?
Select an answer to reveal the explanation.
Short Explanation
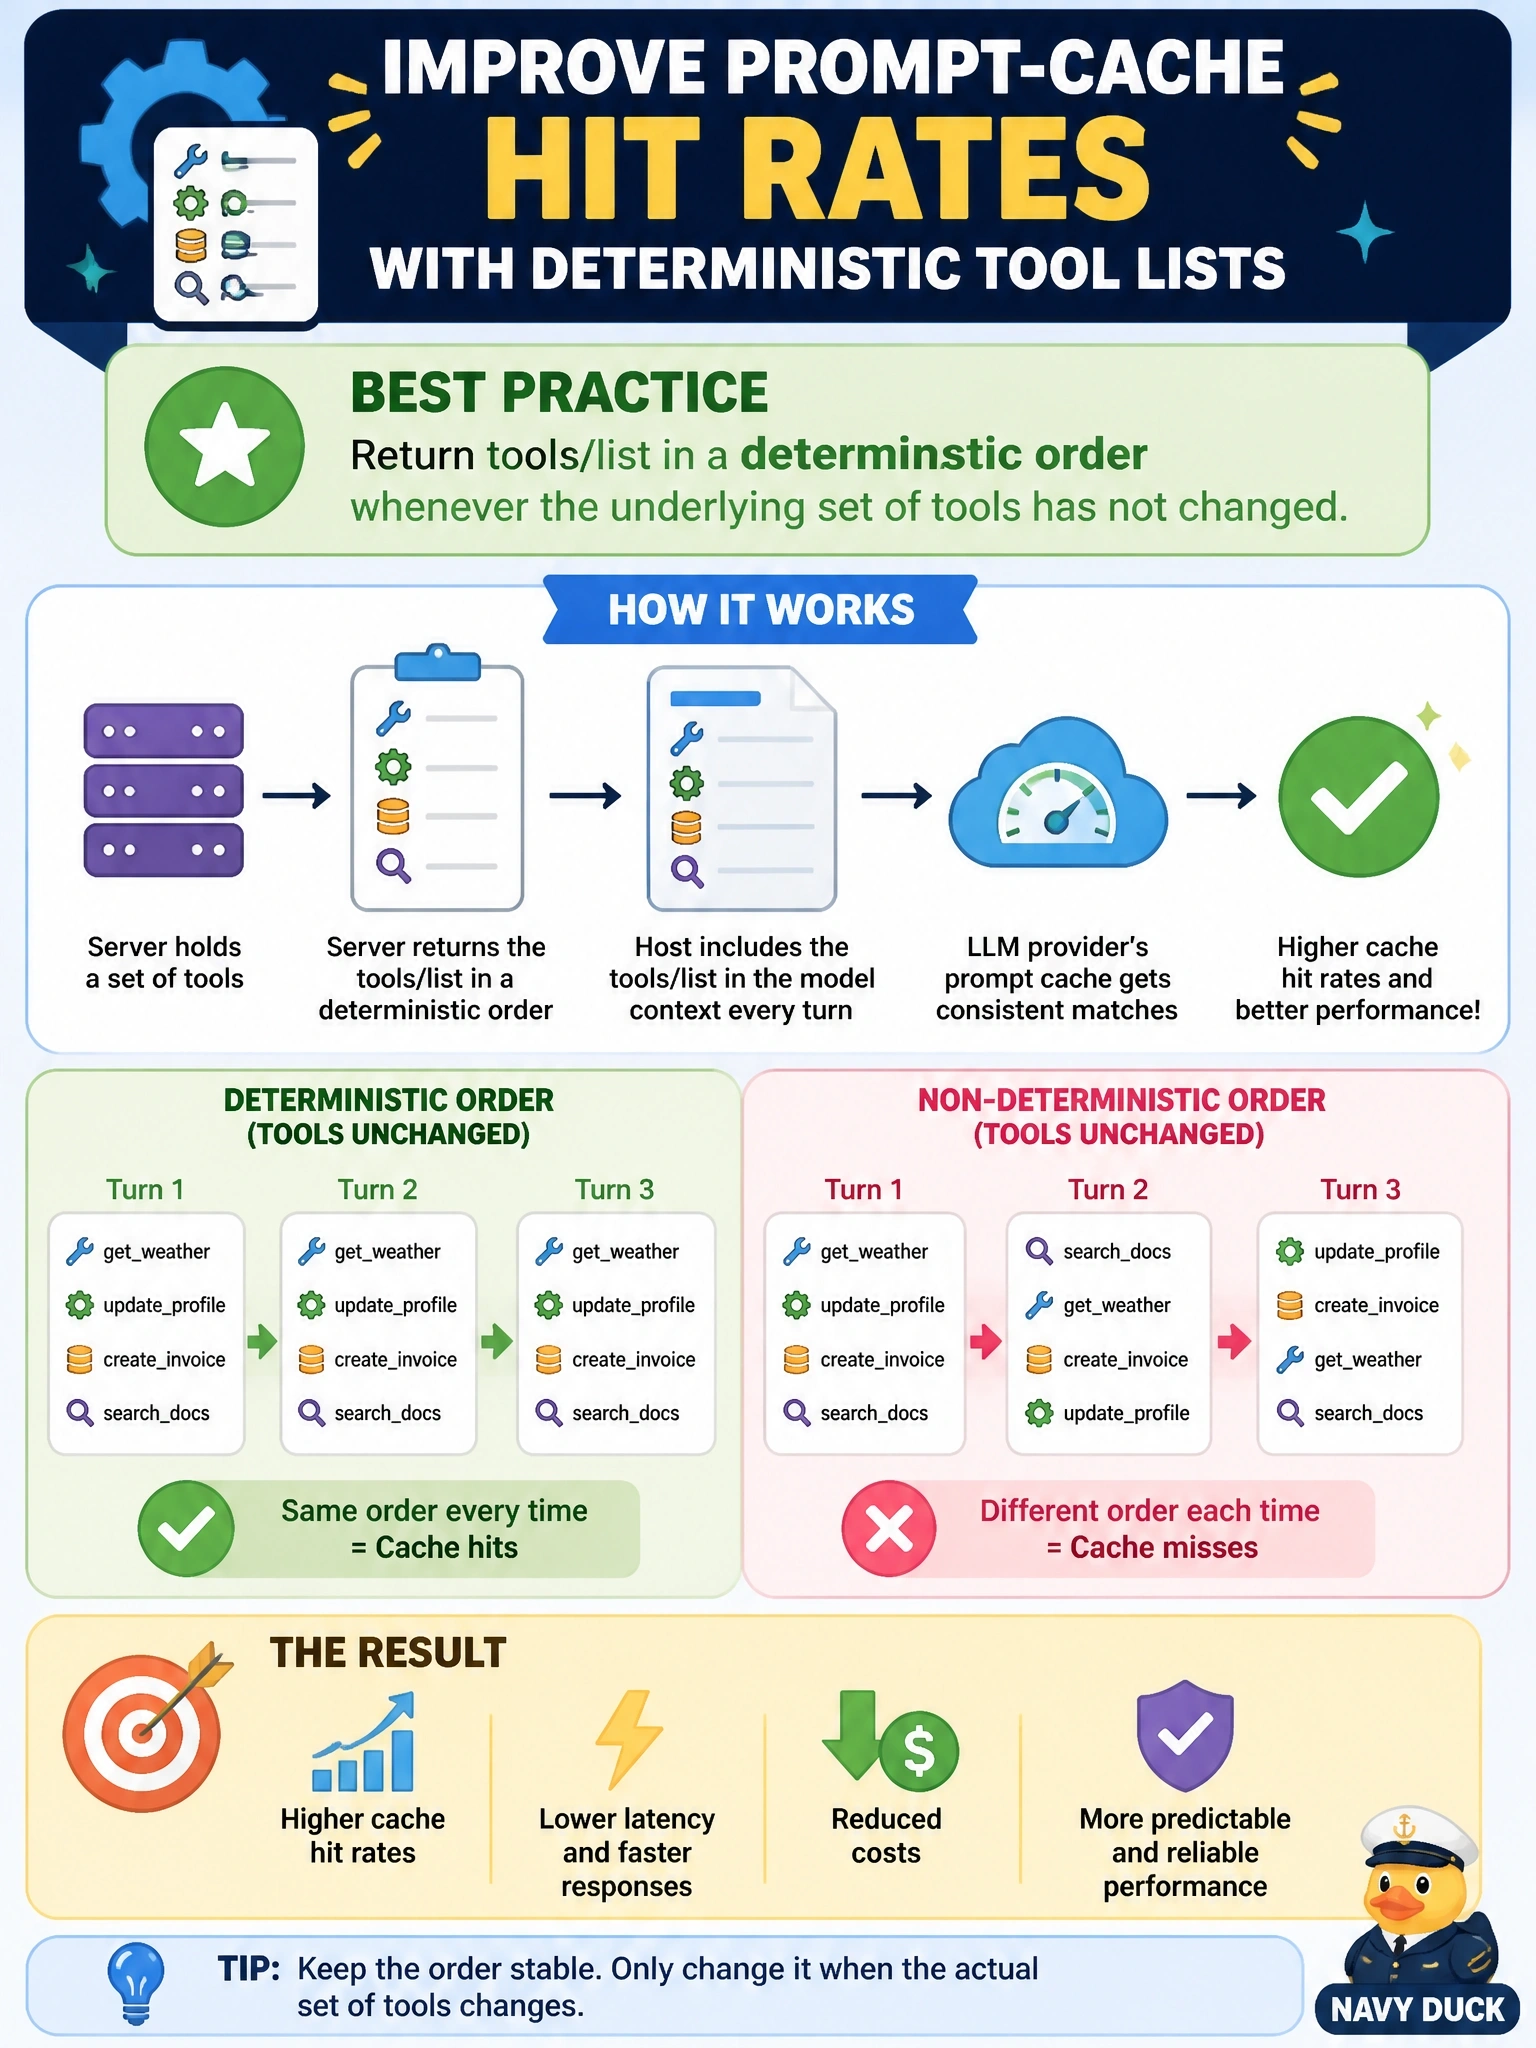
Prompt caches love things that don't move. If your tool list comes back in the same order every time, the cached prefix stays valid. Shuffle it, and you pay for the whole prompt again.
Full Explanation
The tools specification says servers SHOULD return tools in a deterministic order, meaning the same ordering across requests when the underlying set of tools has not changed. It explains the reason directly: deterministic ordering lets clients reliably cache the tool list and improves LLM prompt-cache hit rates when tools are included in model context. Provider prompt caches typically match on an unchanged prefix, so a stable tools block keeps cached tokens reusable from turn to turn. Sorting by most recent use changes the order whenever usage changes, which would repeatedly invalidate the cached prefix even though the set of tools is identical. Returning different subsets per connection violates a MUST NOT: the tool set must not vary per connection or as a side effect of other requests, though it may vary by the authorization presented on a request. A ttlMs of 0 only tells the client the cached result is immediately stale; it does not stabilize ordering, and forcing a refetch before every turn adds traffic without improving the cache. Exam caveat: client guidance adds that newly discovered definitions should be appended after the cache breakpoint rather than re-sorting the tools array. Operational check: call tools/list several times without changing the server and confirm the tools appear in identical order each time.