
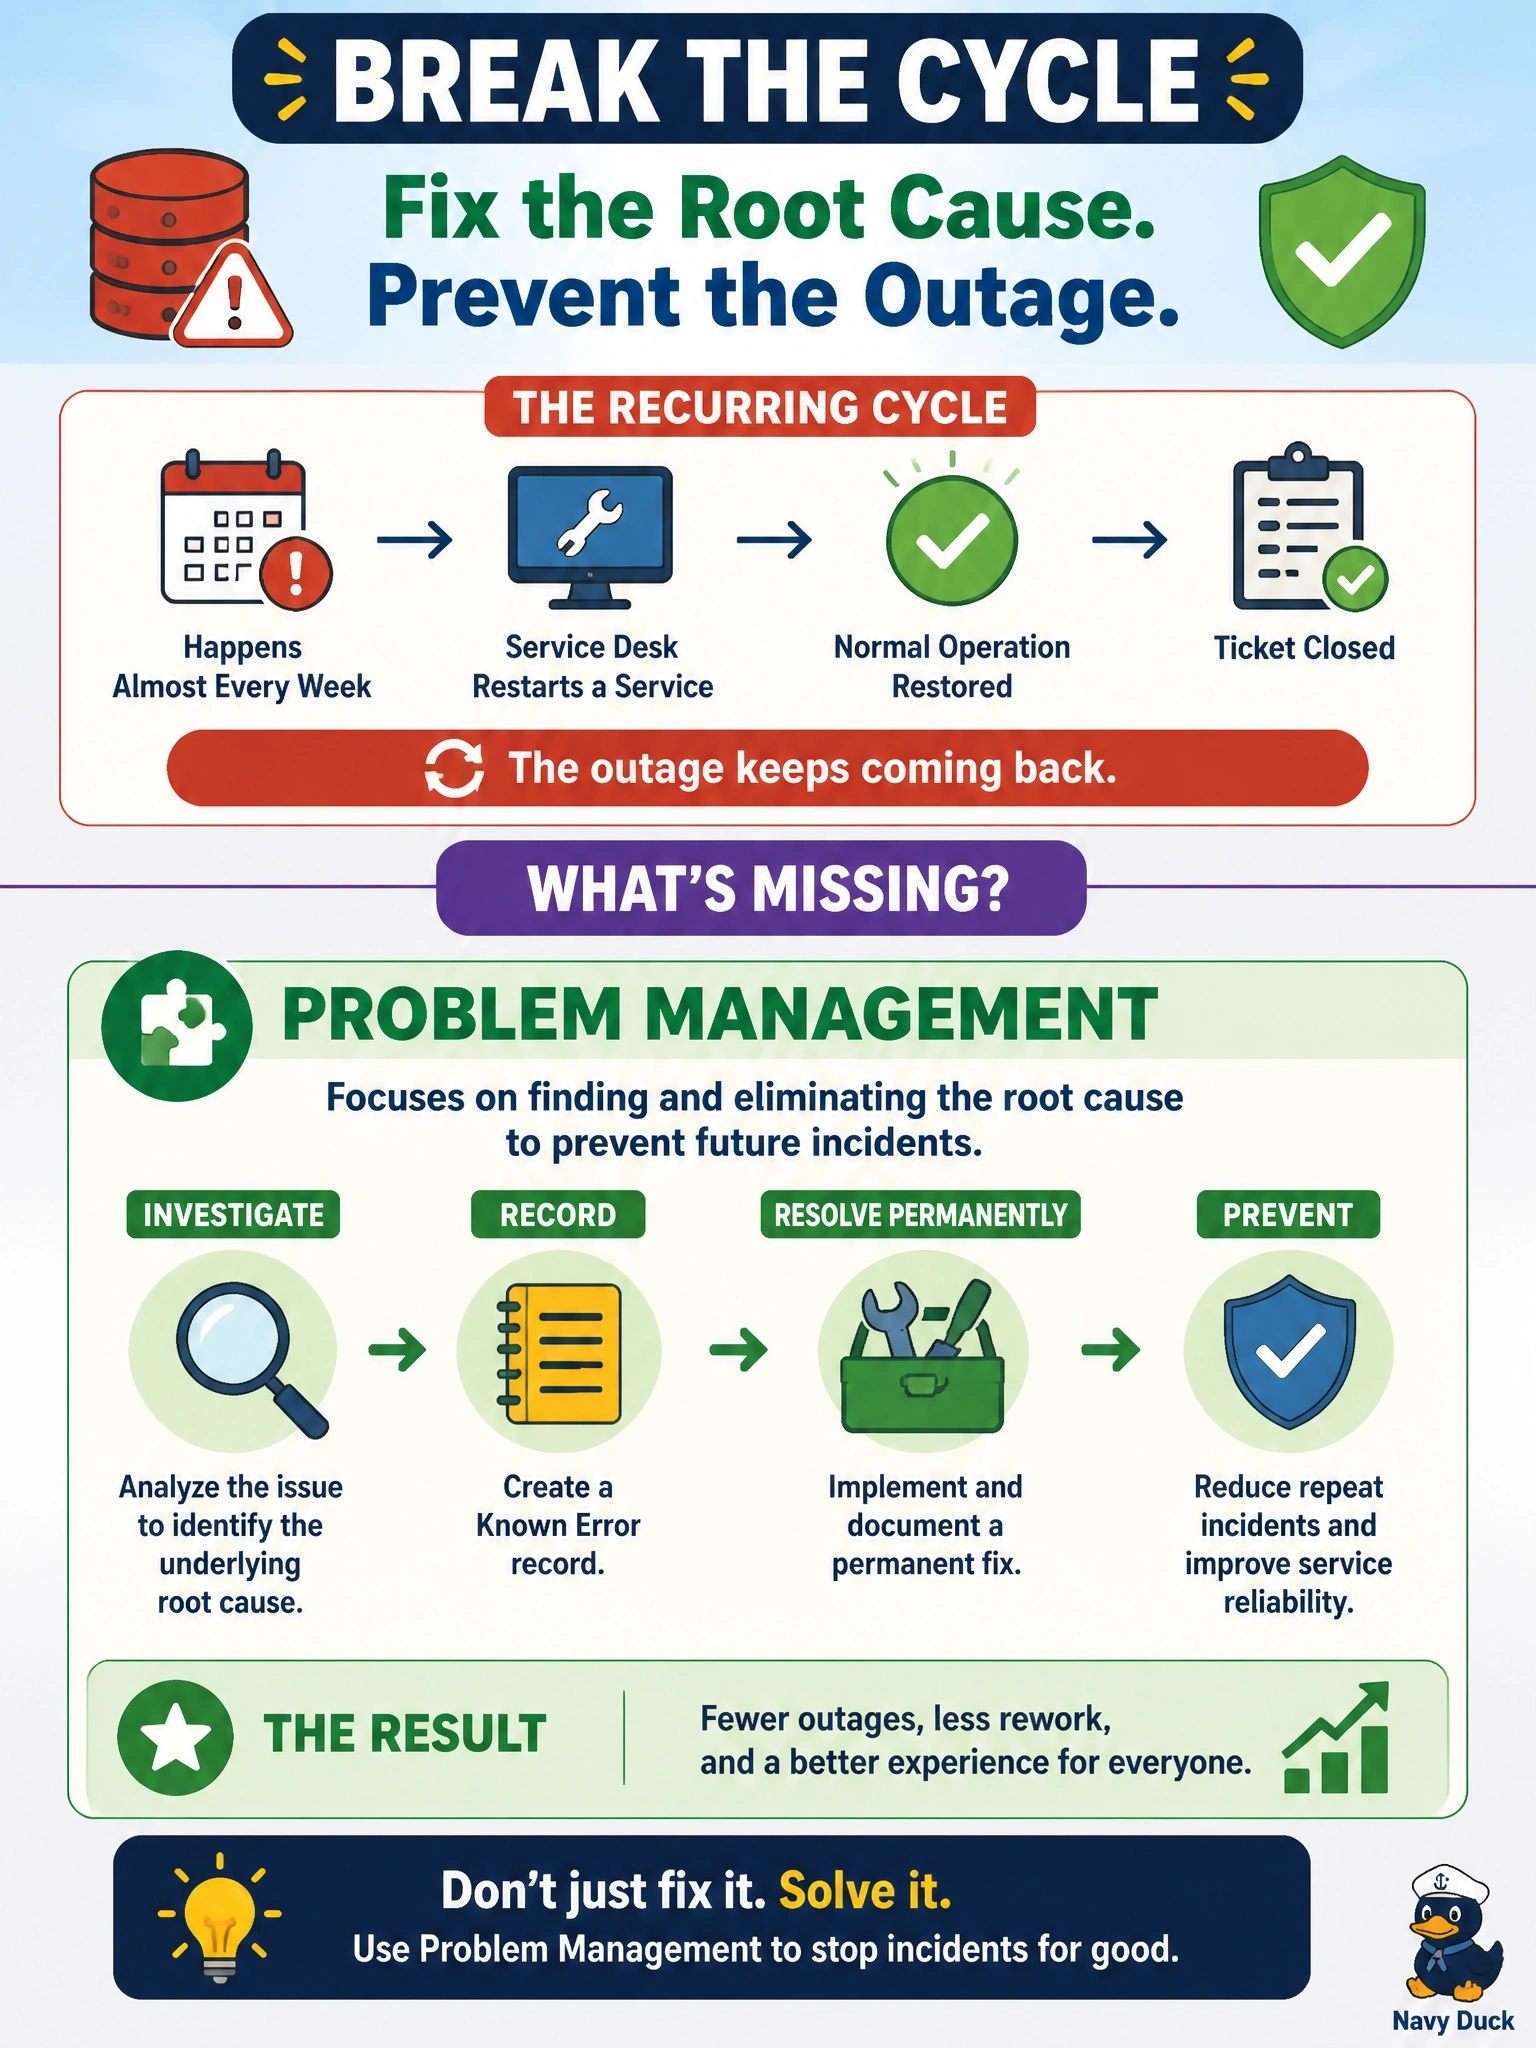
The same storage latency outage happens almost every week. Each time, the service desk restarts a service, restores normal operation and closes the ticket, and nothing else is done. Which practice is missing?
Select an answer to reveal the explanation.
Short Explanation
Incident management is the fire brigade putting out the fire every week; problem management is the investigator who finds the faulty wiring. You've got plenty of firefighting here and zero investigation. The trap is getting faster at closing tickets instead of stopping the repeat.
Full Explanation
Incident management aims to restore normal service as quickly as possible and minimize impact, which the service desk is already doing effectively. Problem management is the separate practice that identifies and manages the causes of incidents: it detects recurring patterns, performs root cause analysis, documents known errors with workarounds, and drives a permanent fix through change management. A storage latency outage that recurs weekly is a textbook trigger for opening a problem record. Speeding up incident handling improves restoration time, but every week the same outage still occurs and the cause remains. Release management decides when new or changed features become available; packaging a restart as a release would formalize the workaround rather than eliminate the need for it. Availability management monitors, measures and plans to meet availability targets, and it would highlight the recurring outage minutes, but reporting the shortfall is not the same as investigating and removing the cause. Exam caveat: incidents and problems are deliberately distinct; an incident can be closed once service is restored while its related problem remains open until the root cause is fixed. Operational check: confirm that incident records are linked to a problem record, that the problem has an assigned owner and documented root cause analysis, and that a change implementing the permanent fix is scheduled and tracked to closure.