
A model validation team challenges a model based on finding that its training error is significantly lower than validation error. What model risk does this finding indicate?
Select an answer to reveal the explanation.
Short Explanation
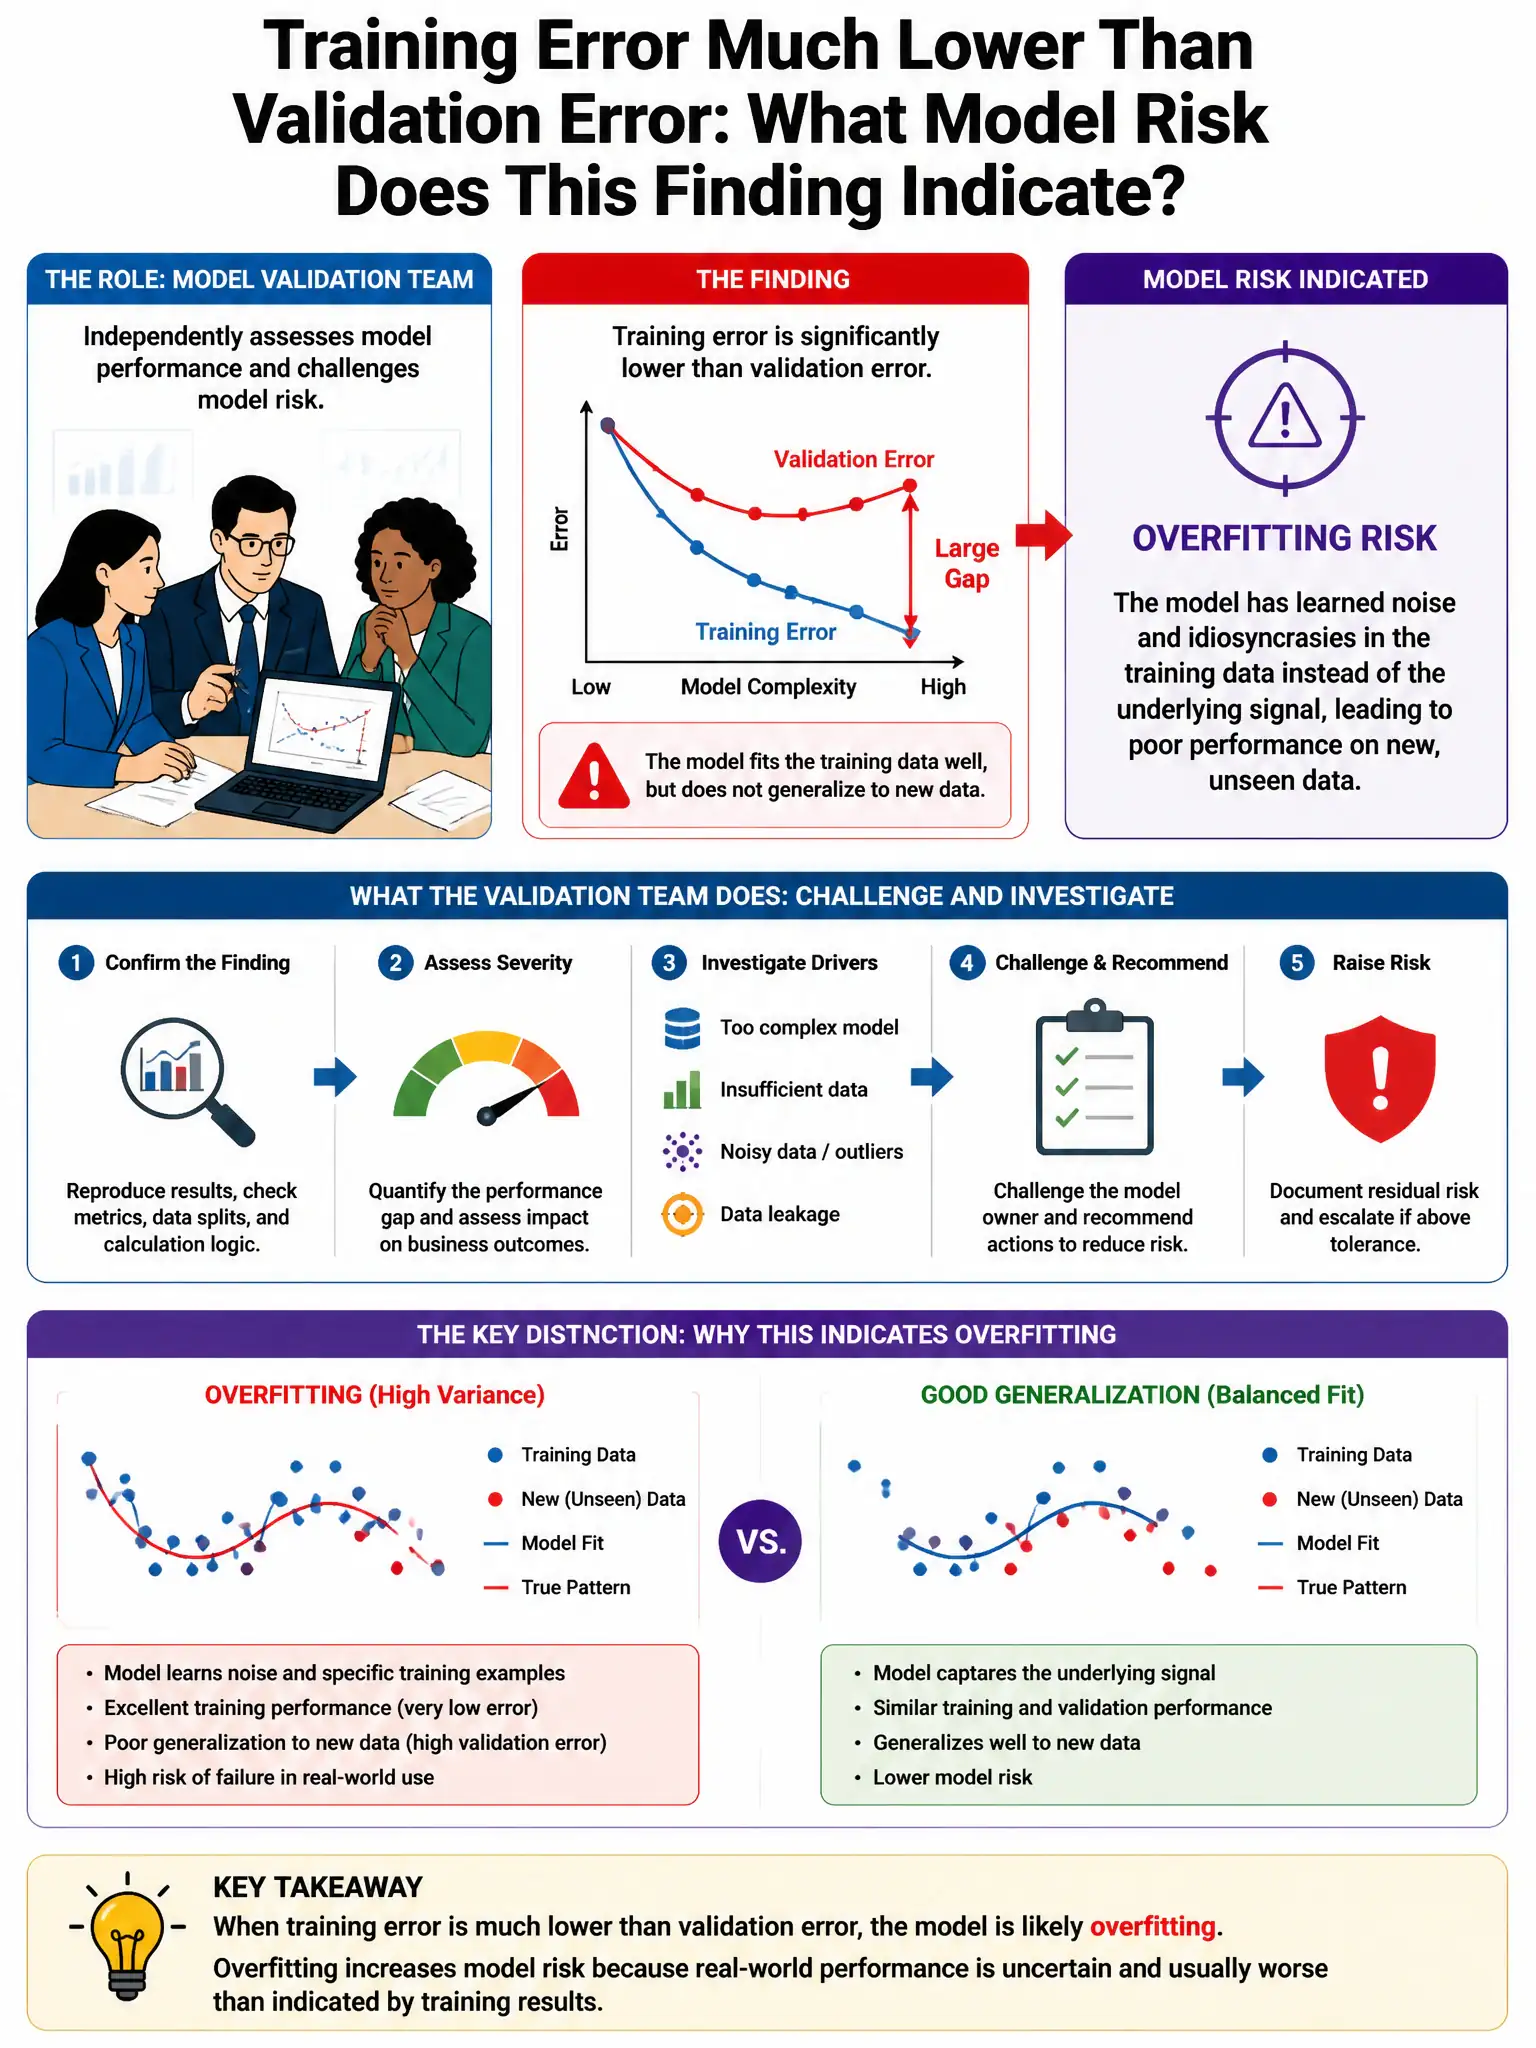
Here's the deal — when training error is much lower than validation error, you're looking at overfitting. The model memorized the training data, including its noise, and can't generalize to new observations. An underfit model would show high error on both training and validation.
Full Explanation
The correct finding is overfitting — the model has memorized training data and will not generalize to new observations — because a large gap between low training error and high validation error is the classic signature of overfitting. The model memorized training noise and idiosyncrasies but cannot generalize. Underfitting — the model being too simple to capture underlying patterns — would produce both high training and high validation error. Data leakage — training and validation data accidentally mixed — would typically make validation error unrealistically low. Label noise — incorrect validation labels — affects validation metrics but does not explain the training-validation gap by itself.