
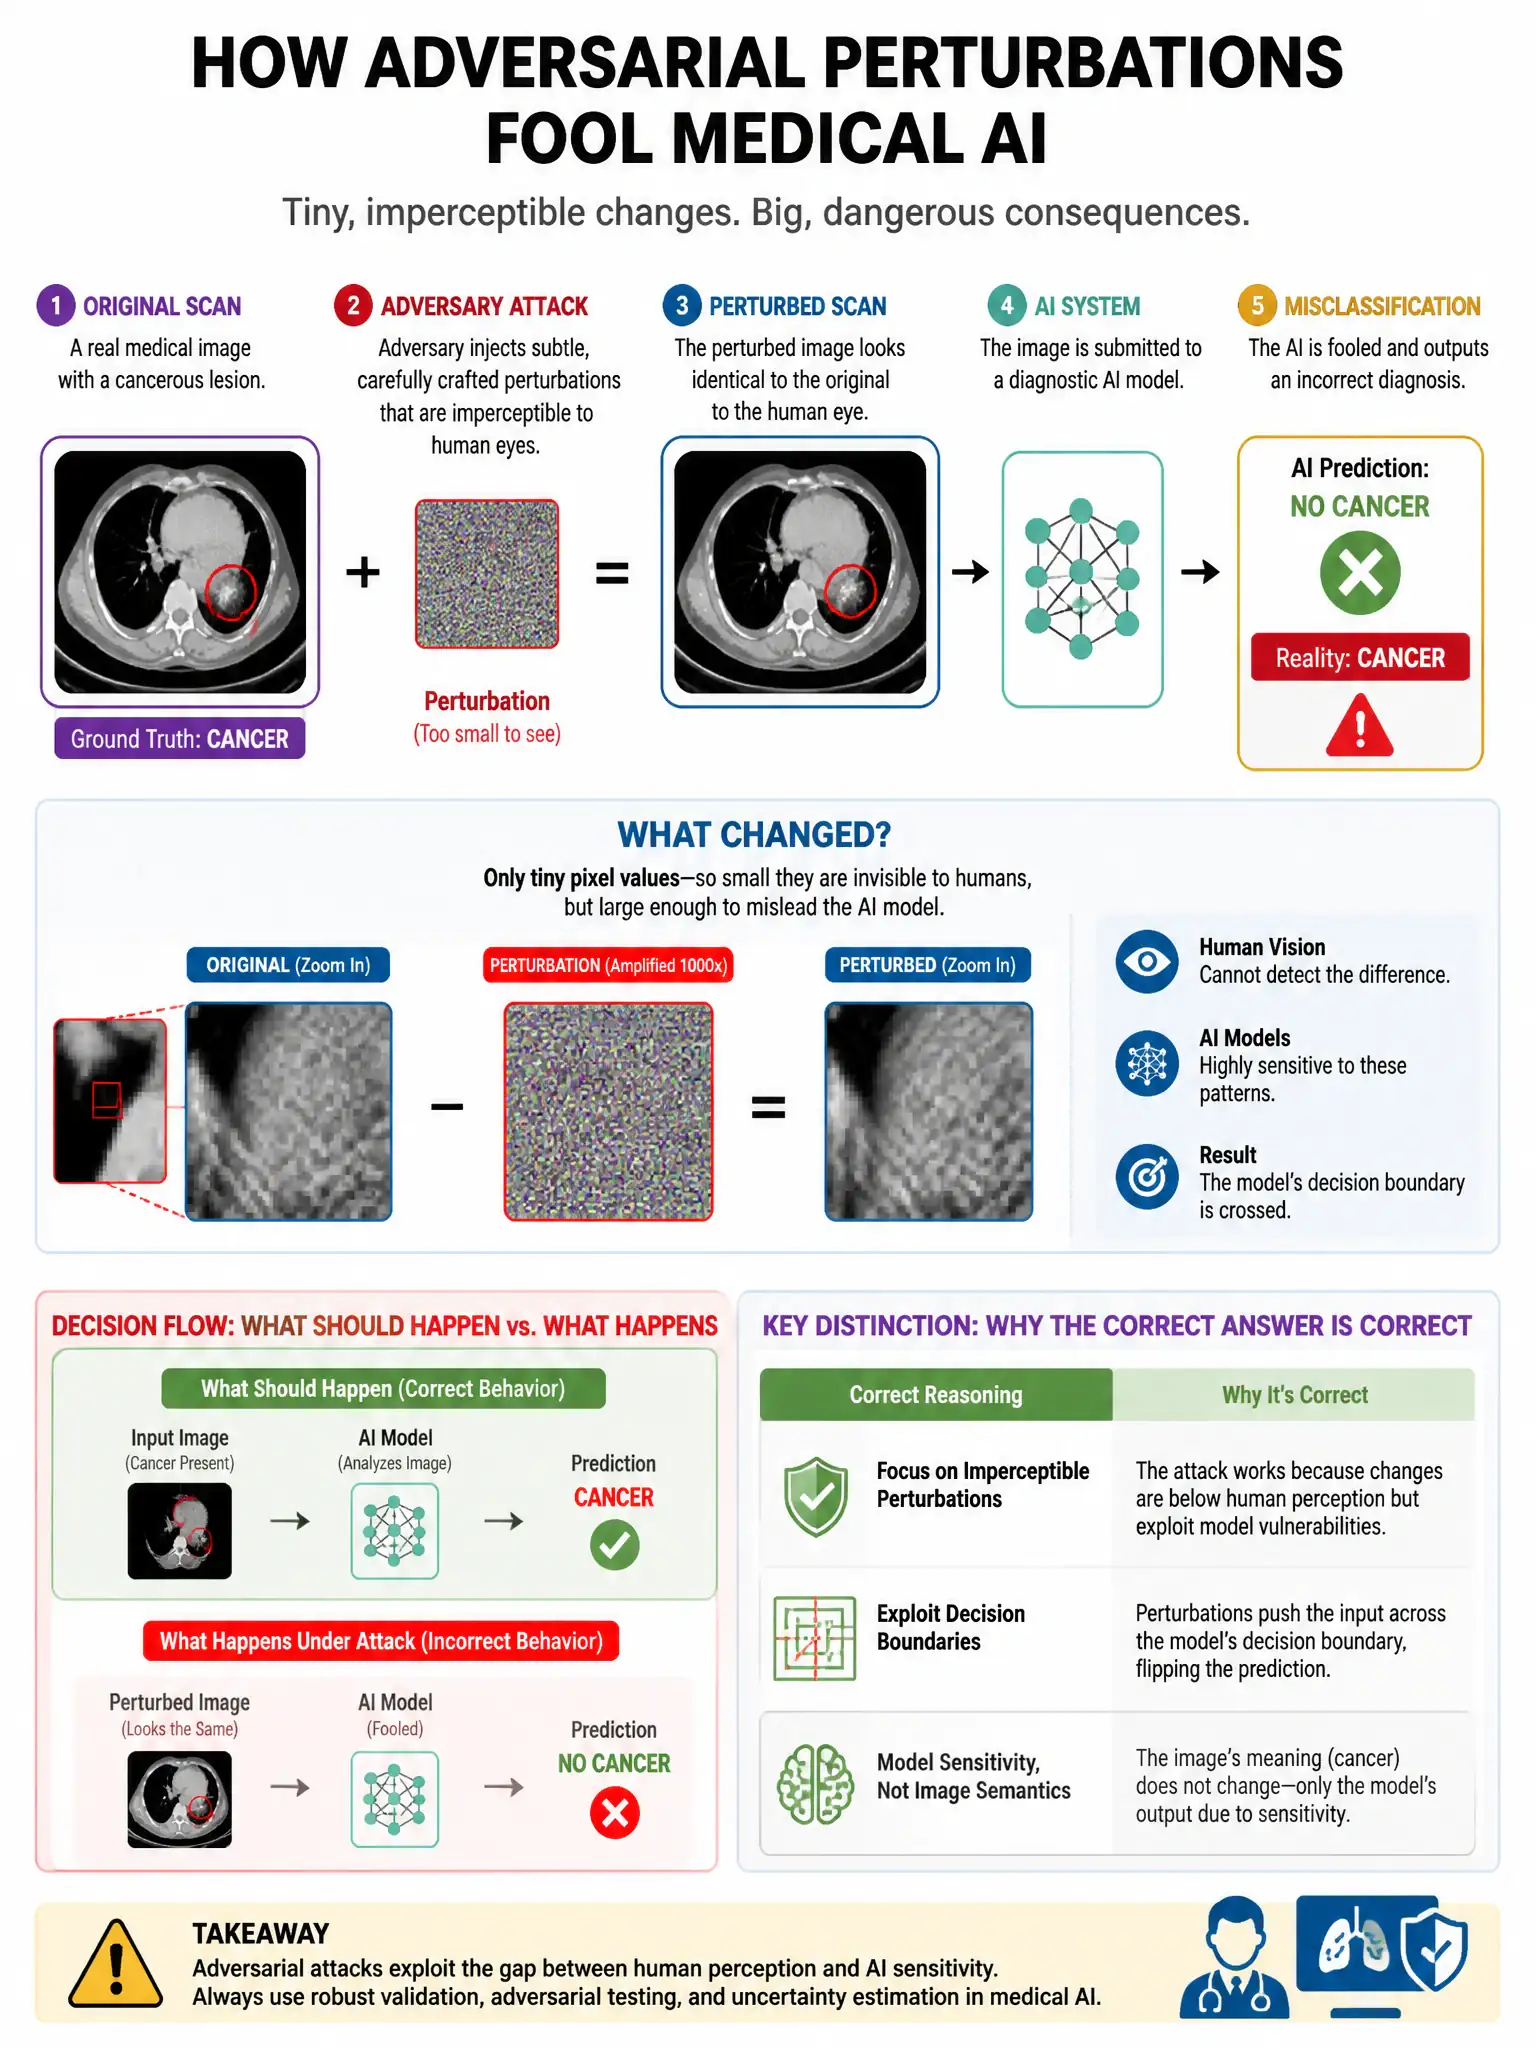
An adversary injects subtle, imperceptible perturbations into medical scan images before submitting them to a diagnostic AI system, causing the system to misclassify cancerous findings as benign. Which attack type does this represent?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — when you see tiny, imperceptible changes added to medical scans at inference time to force misclassification, that's an adversarial example attack. White-box means the attacker knows the model well enough to craft those changes.
Full Explanation
The white-box adversarial example attack at inference time is correct because adding imperceptible perturbations to inputs at inference time to cause misclassification is the defining characteristic of adversarial example attacks; white-box assumes the attacker has knowledge of the model architecture to craft optimal perturbations. The trojan attack via backdoored model weights involves deliberately implanted backdoors in model weights. The model inversion attack to reconstruct training images attempts to reconstruct training data from model outputs. The data poisoning during the training pipeline involves corrupting the training dataset.