
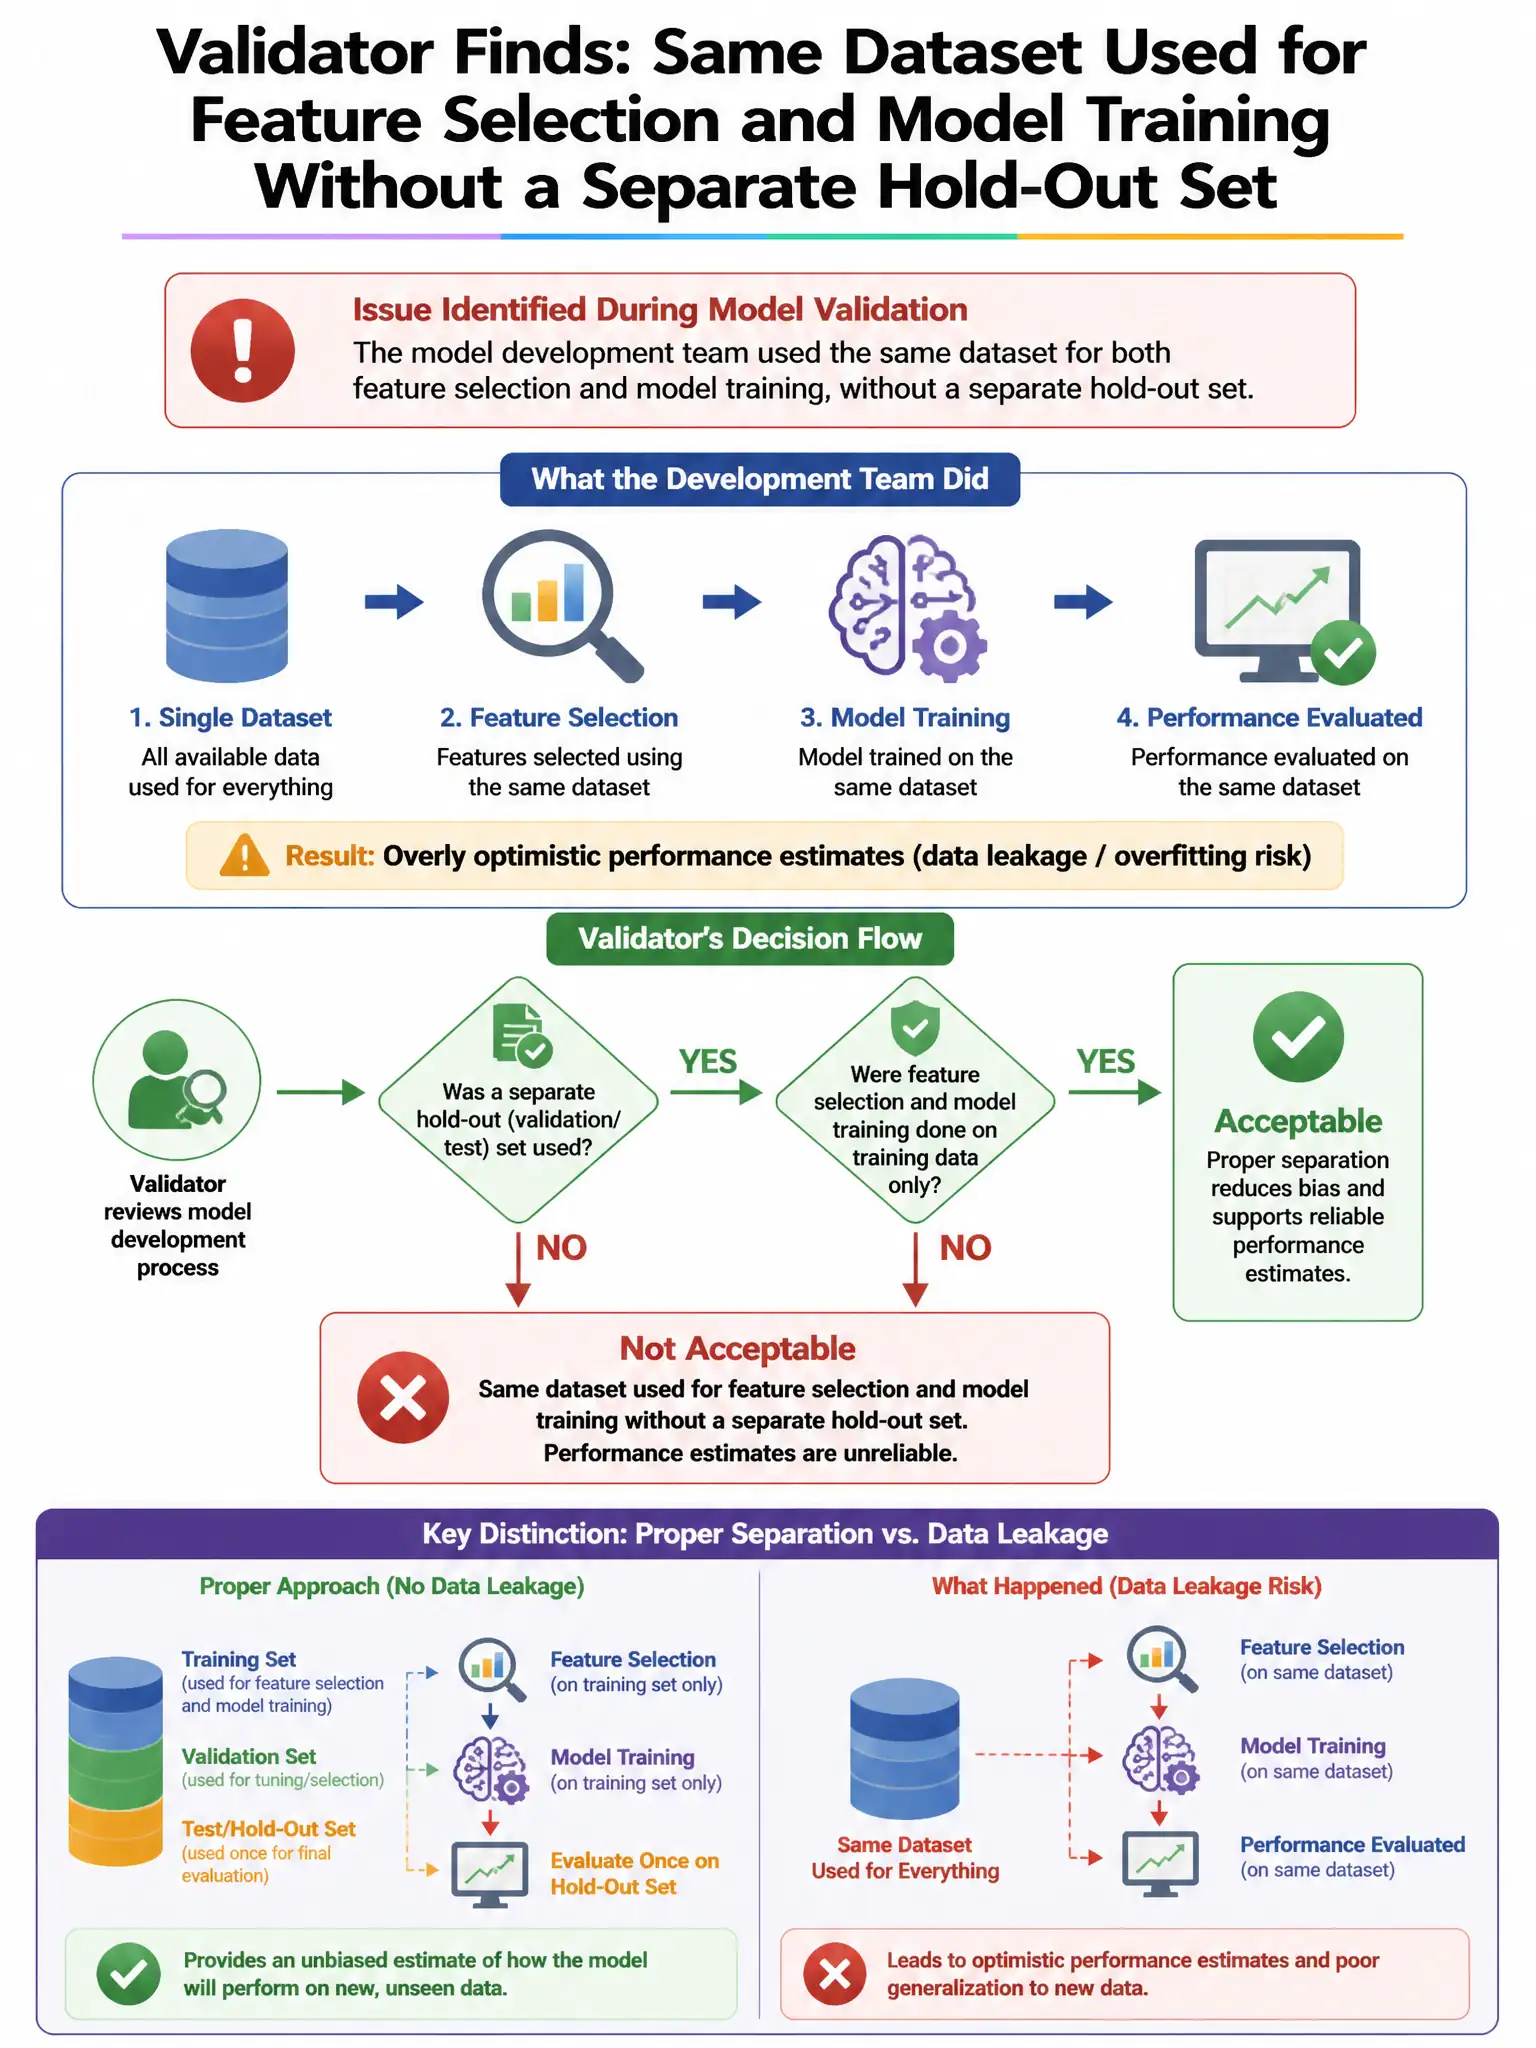
During model validation, the validator discovers that the model development team used the same dataset for both feature selection and model training, without a separate hold-out set. What risk does this introduce?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — if you use the same data to pick features and train the model, you leak information into the evaluation. That gives you overly optimistic performance estimates that won't hold up on new data.
Full Explanation
Using the same data for feature selection and training introduces data leakage and look-ahead bias, because the model has implicitly seen evaluation information and yields optimistic performance estimates that will not generalize. The underfitting choice is the opposite problem, since more data exposure typically reduces underfitting. The redundant-features complexity choice is not a direct consequence. The regulatory data-minimization choice concerns data protection, not statistical methodology.