
An AI tool used in a criminal justice risk assessment is found to assign substantially different recidivism risk scores to defendants with identical criminal histories when race is inferred from names. Which technical root cause MOST likely explains this finding?
Select an answer to reveal the explanation.
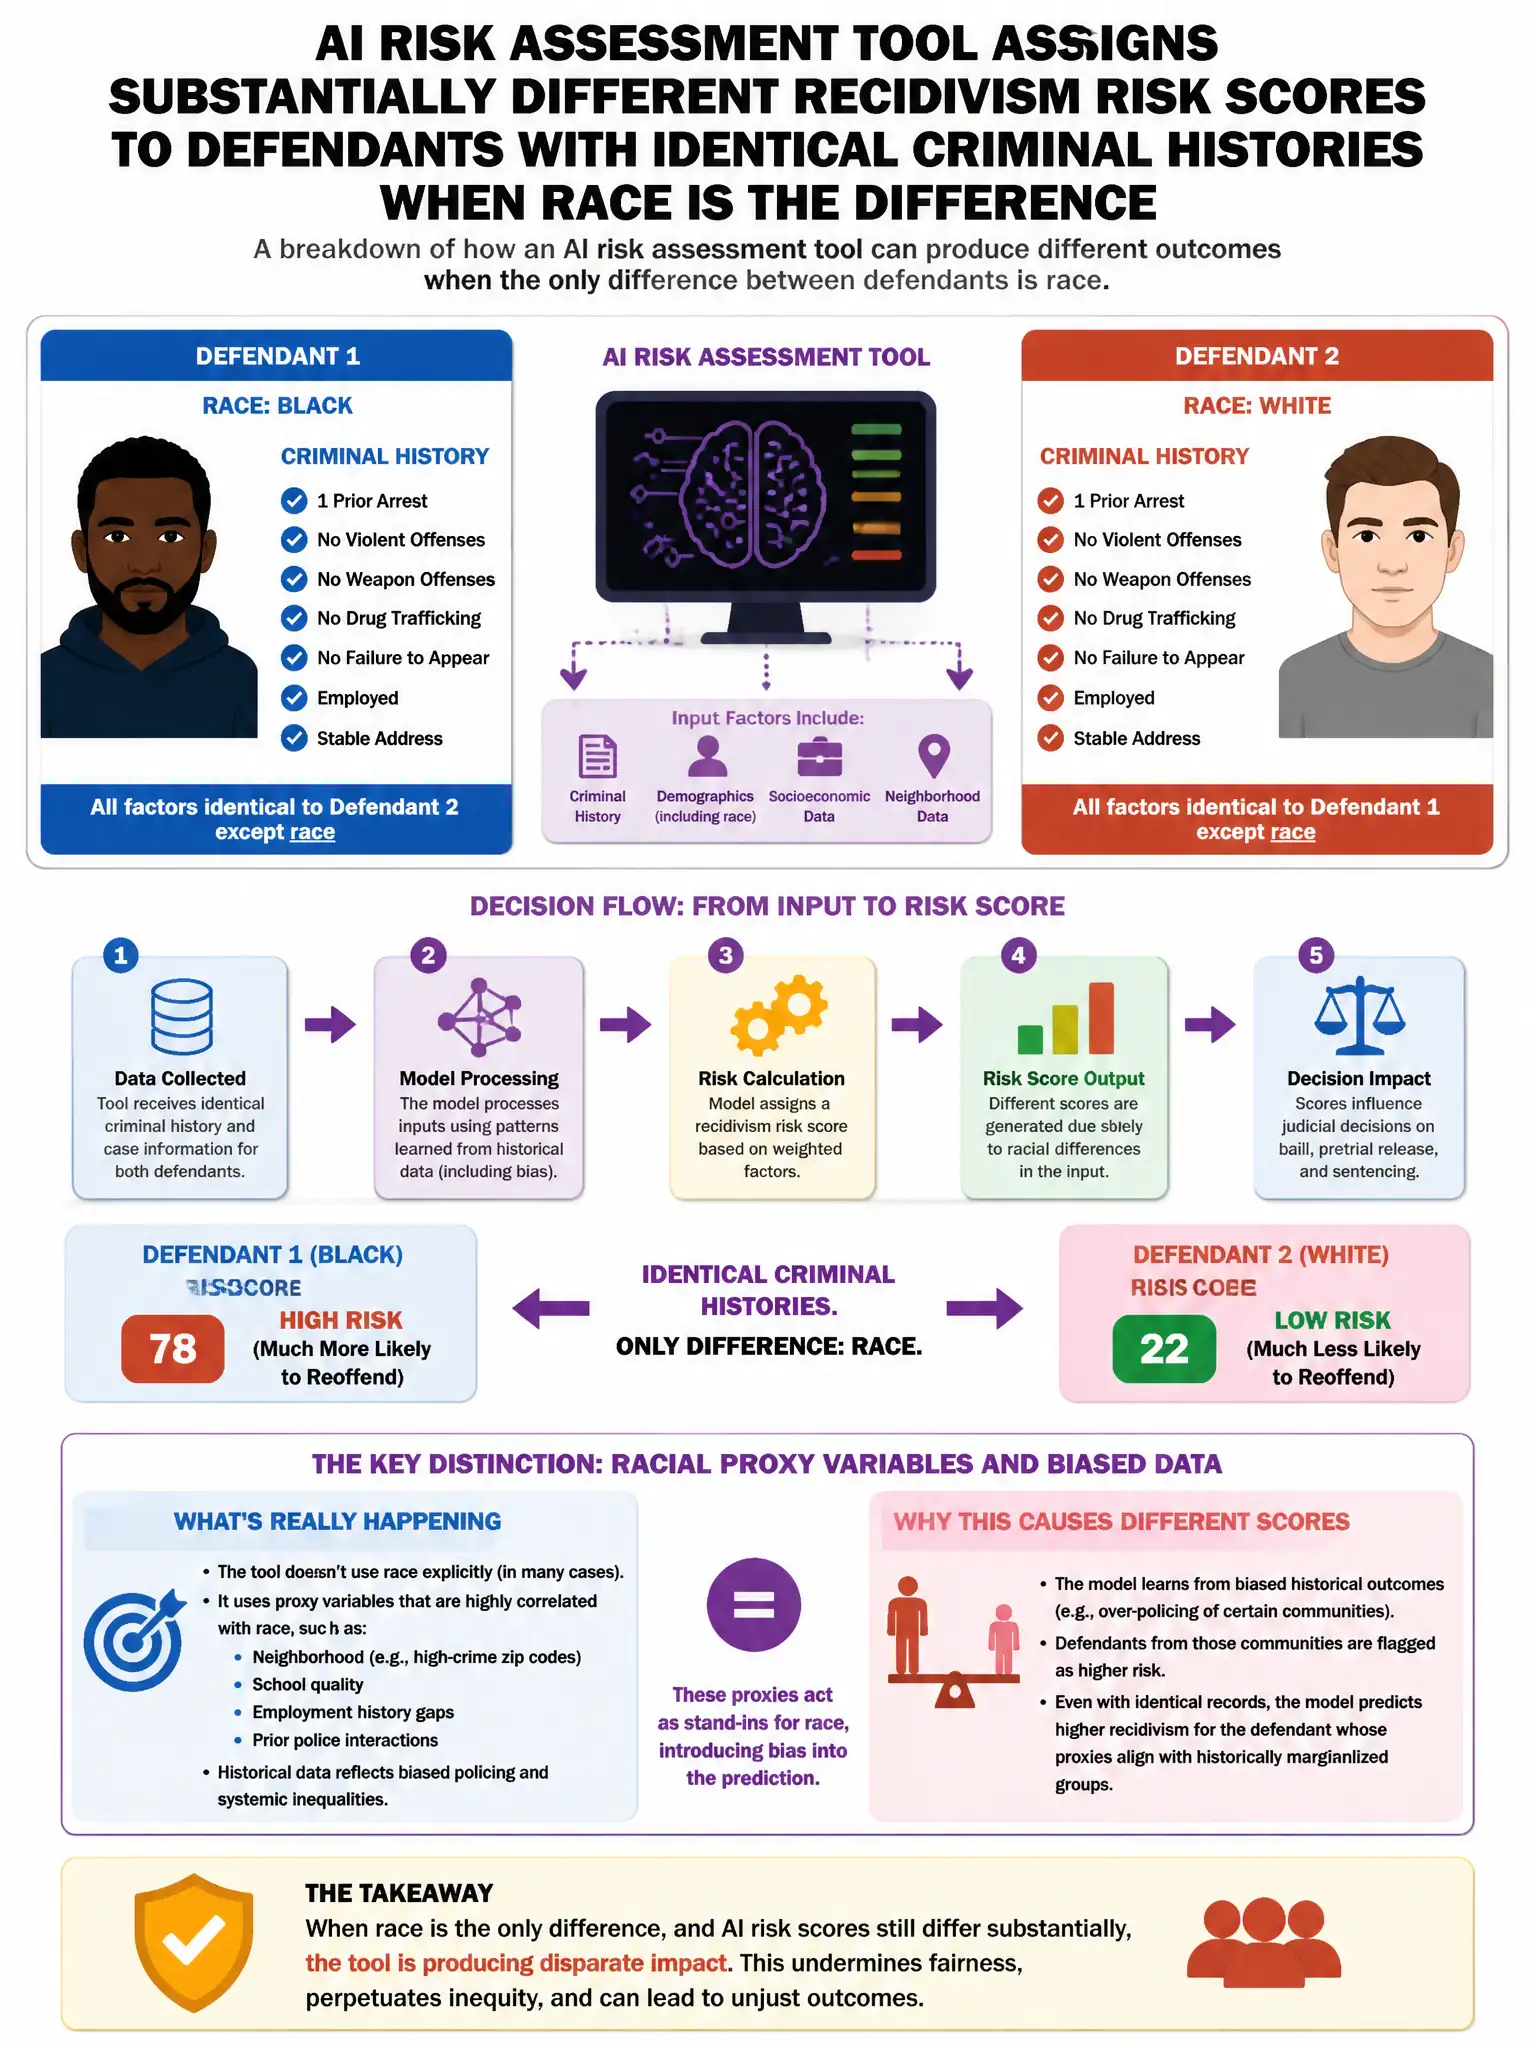
Short Explanation
Here's the deal — names can act as proxies for race, so if the training data carries historical bias, the model learns that association and scores differently even without race as an input.
Full Explanation
The correct explanation is that name, as a feature, can act as a proxy for race, and the model has learned racial correlations with the training outcomes due to historical disparities in criminal justice data. Names are strongly correlated with race and ethnicity in U.S. criminal justice datasets. If the training data reflects historical racial disparities in arrests, convictions, or recidivism classifications, the model learns the correlation between racially-associated names and the historically biased outcome variable. This produces racially discriminatory scores through proxy discrimination without explicitly using race. The option saying the model is using name as a direct feature for recidivism prediction is possible but less likely here, because the scenario describes different scores when race is inferred from names, suggesting name is not necessarily a direct feature. The option saying the developer intentionally encoded racial weighting factors is unlikely and difficult to substantiate. The option saying the evaluation dataset was not representative is a measurement concern, not the root cause of the differential scoring.