
A model validation team is reviewing an AI scoring model and finds that the model developer used the full dataset to select features before splitting into training and test sets. What is the primary problem with this approach?
Select an answer to reveal the explanation.
Short Explanation
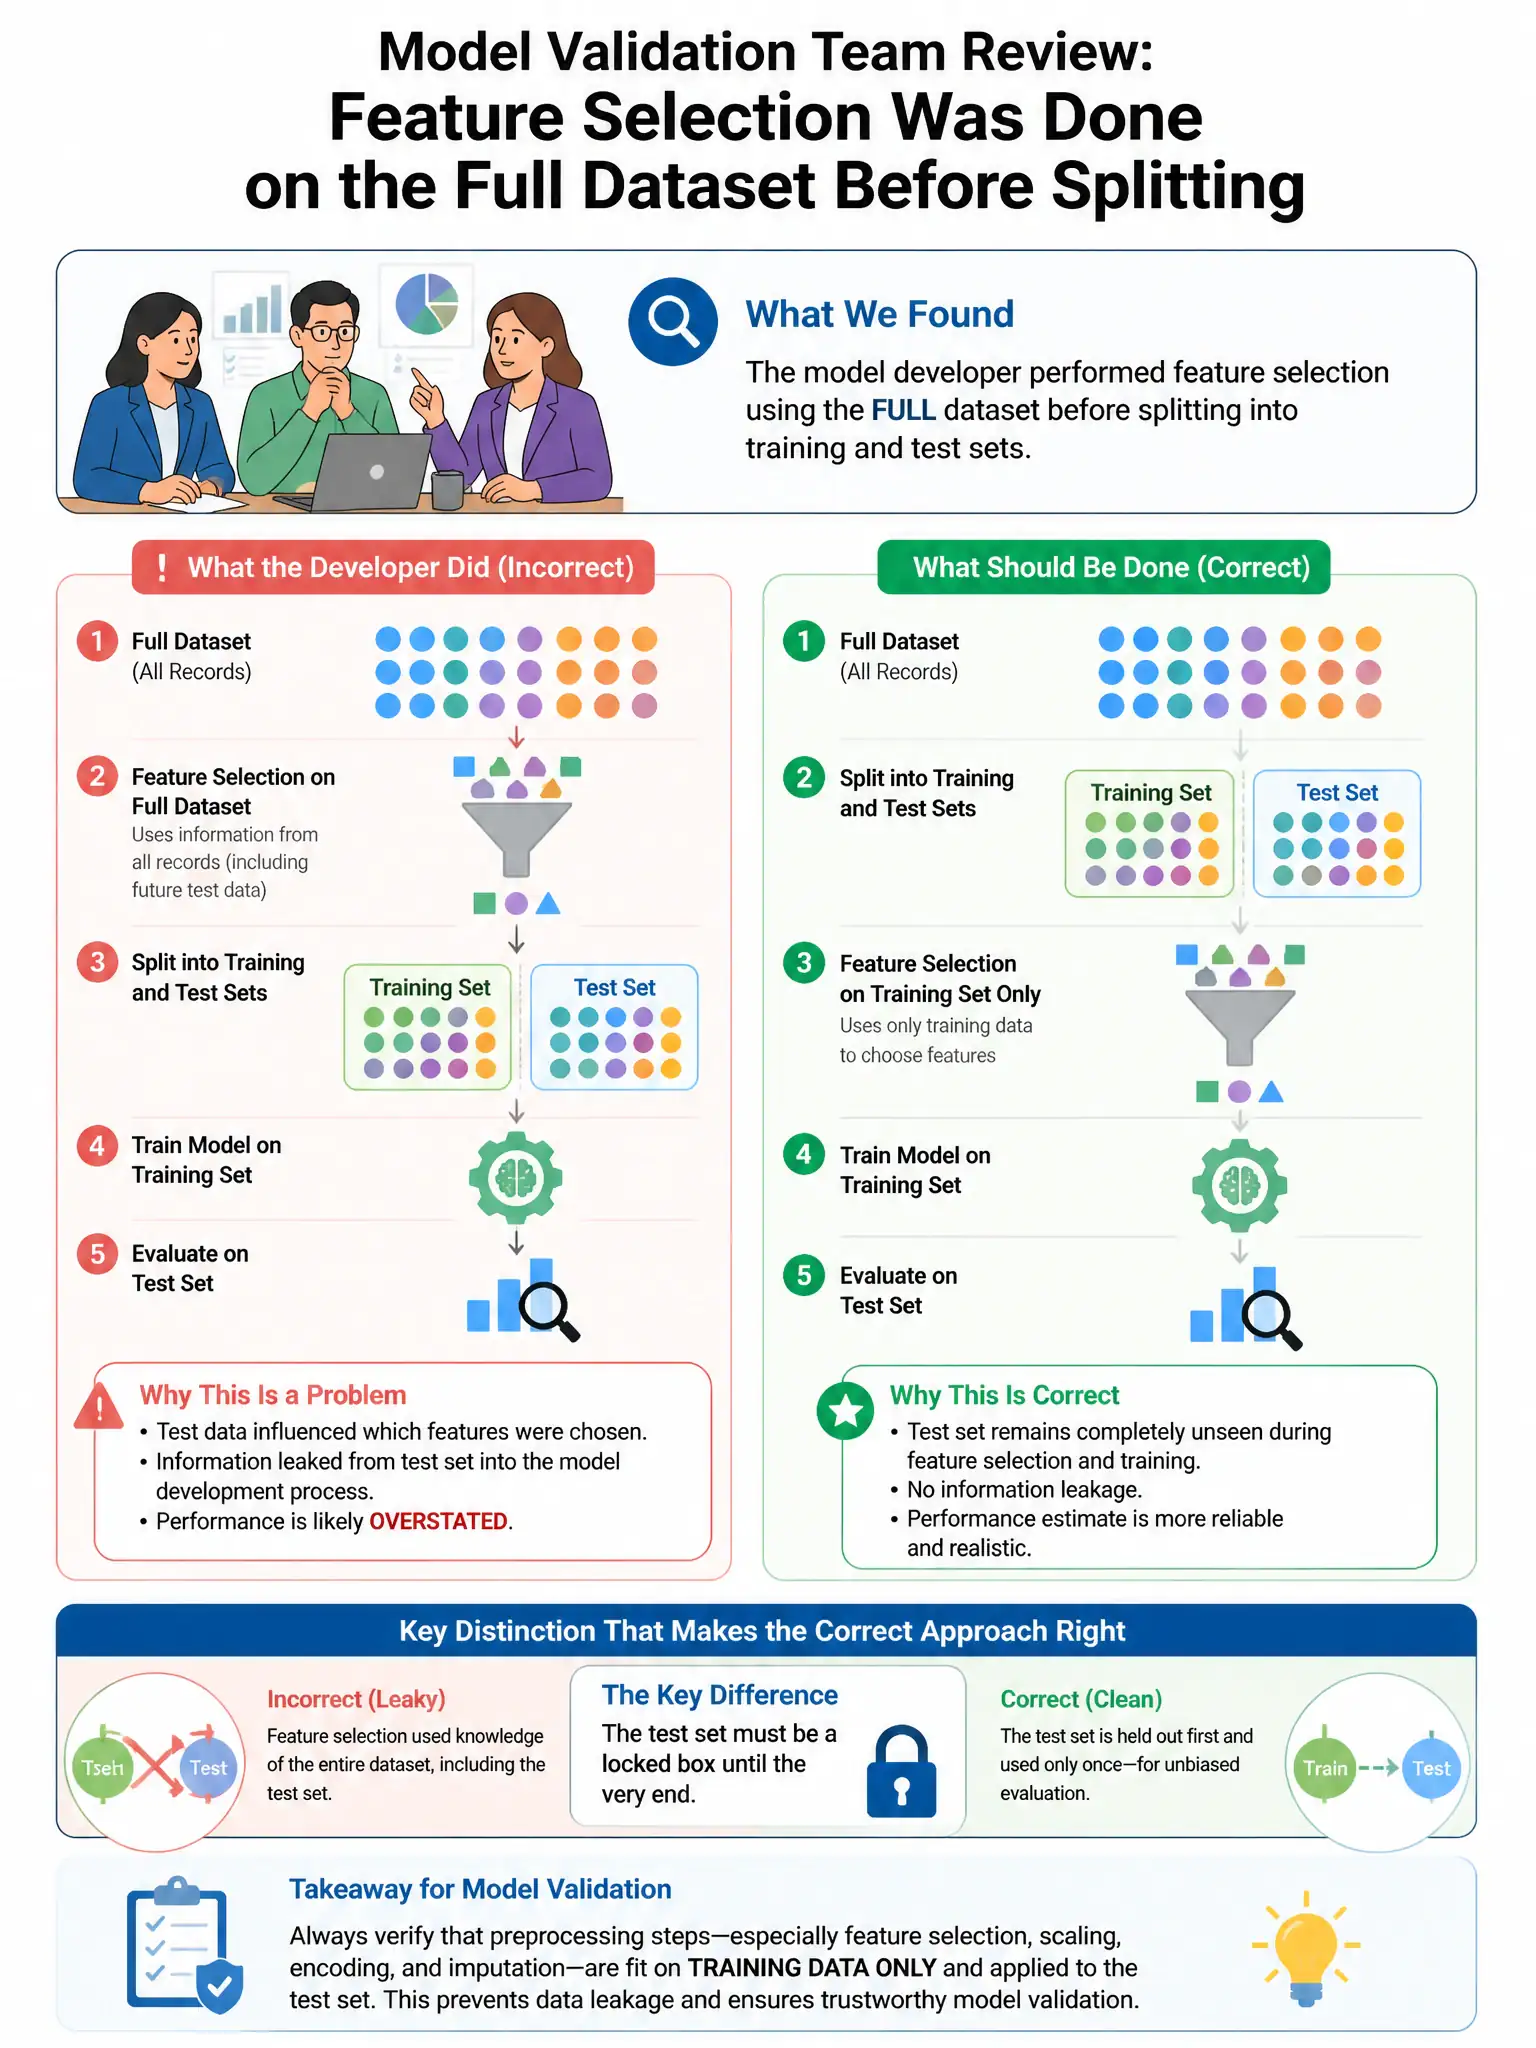
Here's the deal — selecting features on the full dataset before splitting leaks test-set information into model design. You end up with data leakage and inflated test metrics that don't reflect true out-of-sample performance.
Full Explanation
The correct answer is the option saying this creates data leakage, producing artificially inflated test set performance metrics that do not reflect true out-of-sample performance, because using the full dataset, including the test set, to select features means the test set has indirectly influenced model design. This is data leakage: the test set is no longer truly held-out, and the resulting performance metrics are optimistically biased. The model will likely underperform in production compared to the inflated validation metrics. The option about too many features increasing computational costs is an unrelated concern. The option about violating intended use documentation specifying fewer than 20 features is not what is described. The option about preventing retraining on new data without repeating the entire feature selection process is a process concern, not the validation integrity issue.