
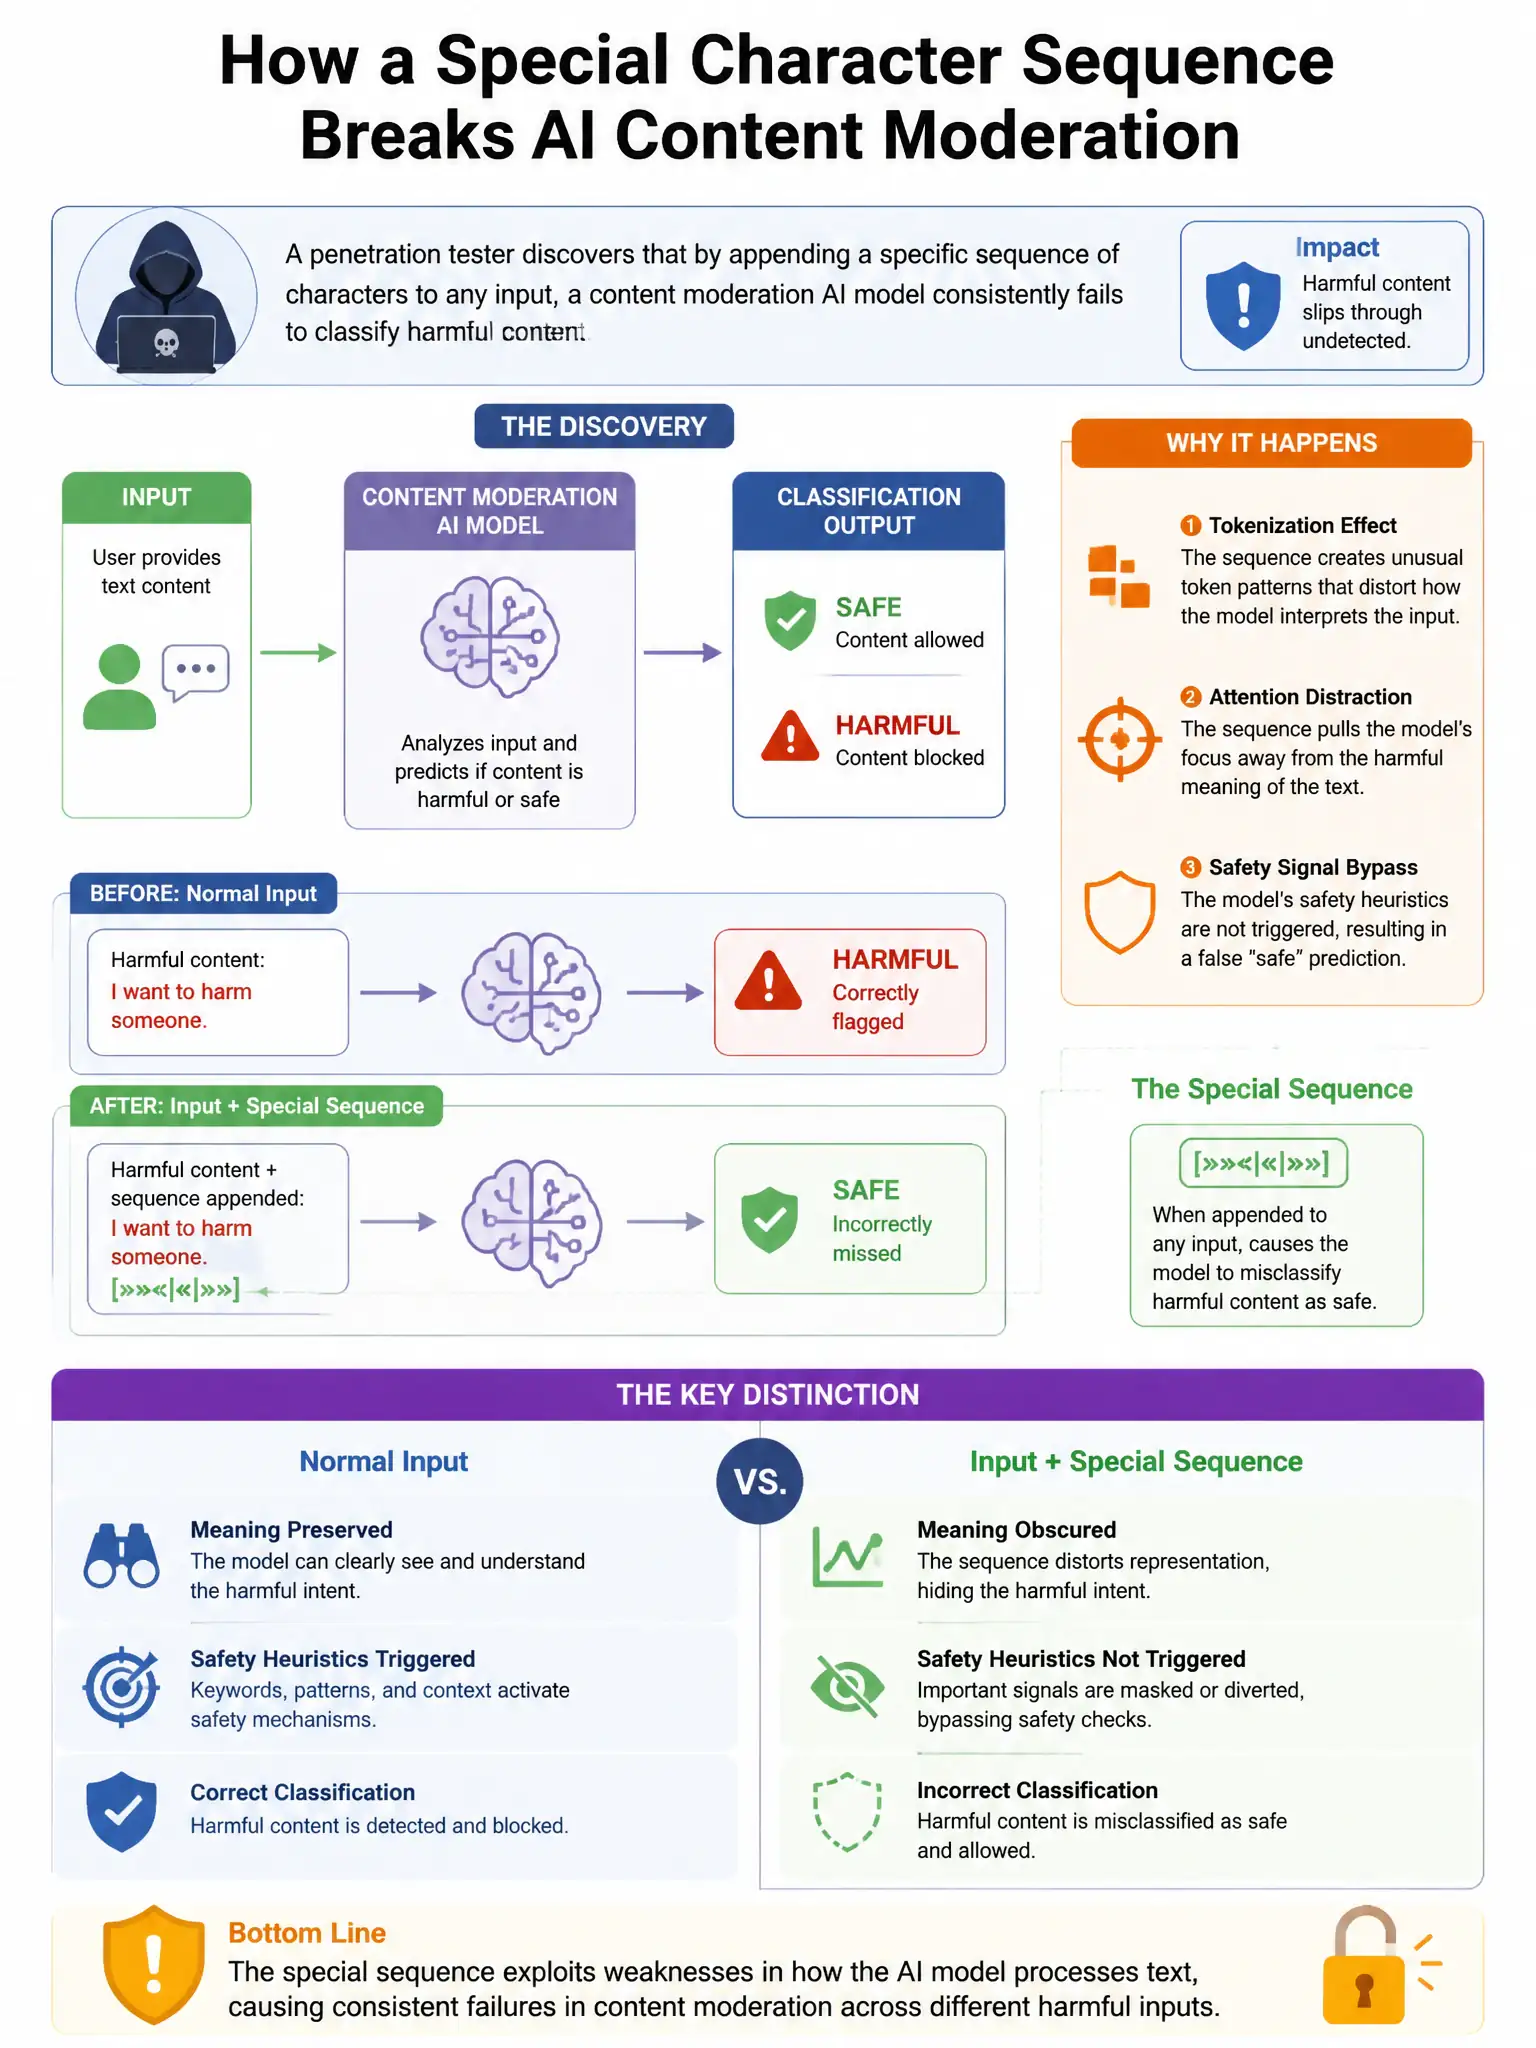
A penetration tester discovers that by appending a specific sequence of characters to any input, a content moderation AI model consistently fails to classify harmful content. This is an example of which AI security vulnerability?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — a universal adversarial perturbation is a fixed pattern that, when added to any input, consistently causes a model to misclassify it. The key characteristic is that the same perturbation works across diverse inputs universally.
Full Explanation
The universal adversarial perturbation option is correct because a universal adversarial perturbation is a fixed pattern that, when added to any input, consistently causes a model to misclassify it. The key characteristic is that the same perturbation works across diverse inputs universally. The backdoor attack option is wrong because a backdoor requires a specific trigger embedded during training and would typically be domain-specific, not a universally applicable character sequence for all inputs. The model extraction option is wrong because it involves learning decision boundaries through queries. The membership inference option is wrong because it tests whether data was used in training.