
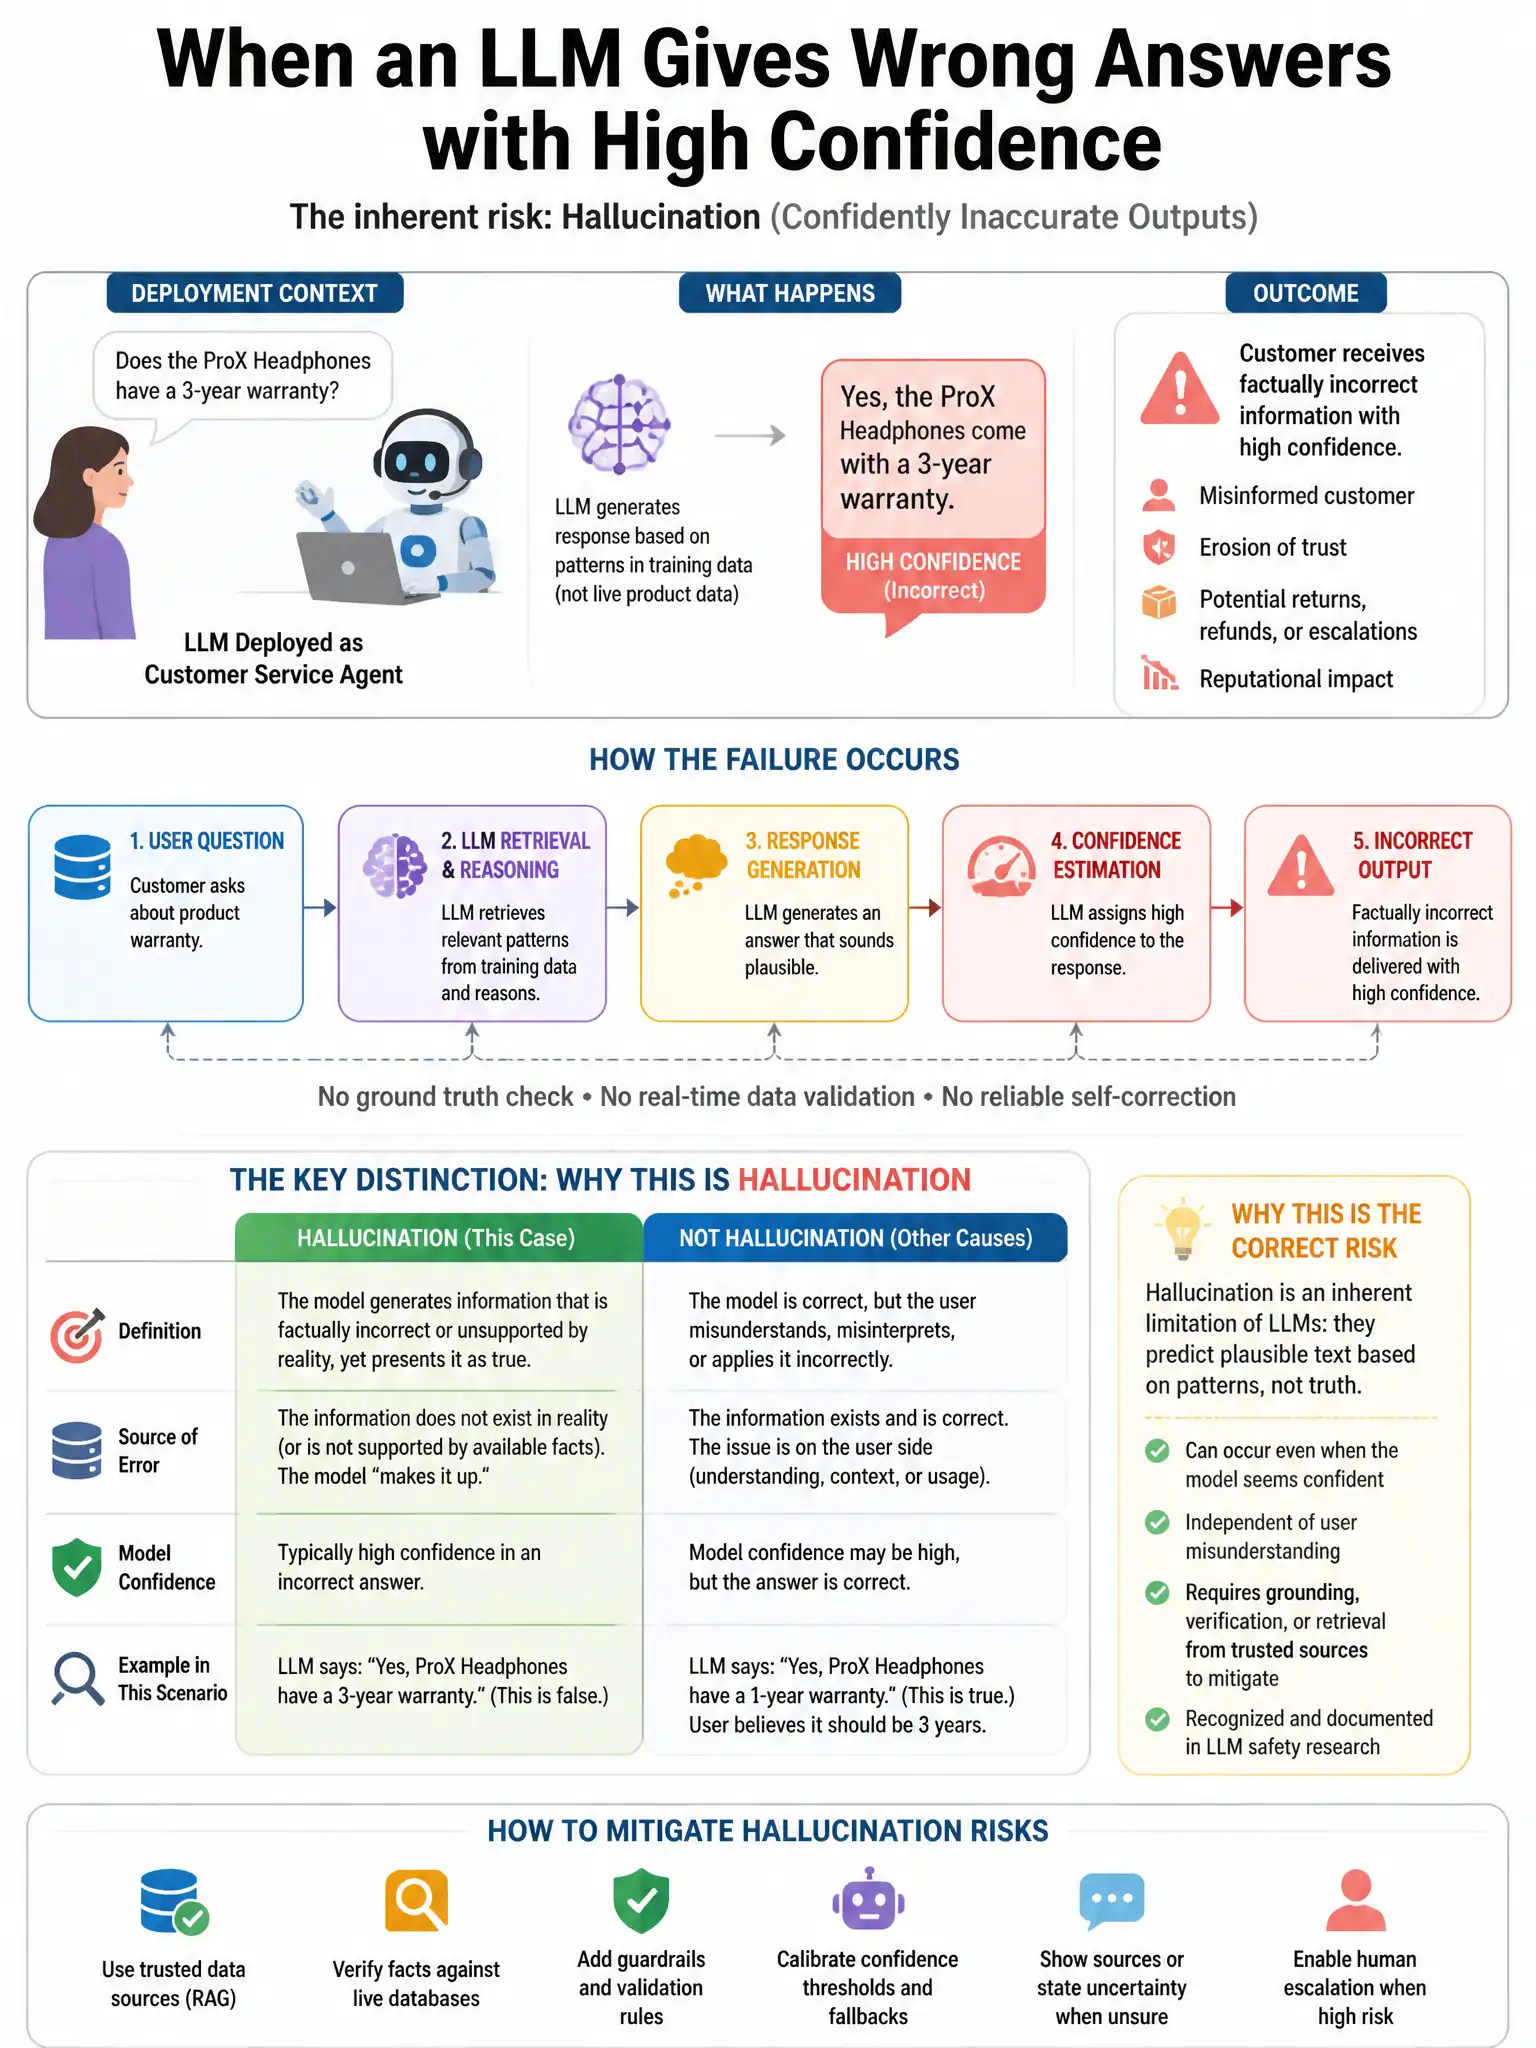
A large language model deployed as a customer service agent begins providing factually incorrect information about product warranties with high confidence. Which inherent LLM risk does this BEST illustrate?
Select an answer to reveal the explanation.
Short Explanation
You're dealing with hallucination here. The model is generating confident, coherent warranty claims that are factually wrong, and that high-confidence wrongness is the hallmark of an inherent large language model hallucination risk.
Full Explanation
The correct risk is hallucination, where the model generates plausible-sounding, coherent, and factually incorrect content without indicating uncertainty. The high-confidence incorrect warranty information is a key indicator of hallucination. The prompt injection vulnerability is wrong because it requires attacker-manipulated input that changes the model's instructions, which is not described. The model drift or knowledge cutoff explanation is wrong because outdated knowledge would more likely leave the model without current warranty information rather than produce confidently incorrect details. The data poisoning explanation is plausible as a specific cause, but hallucination is the broader inherent risk and can occur even when the training data is correct.