
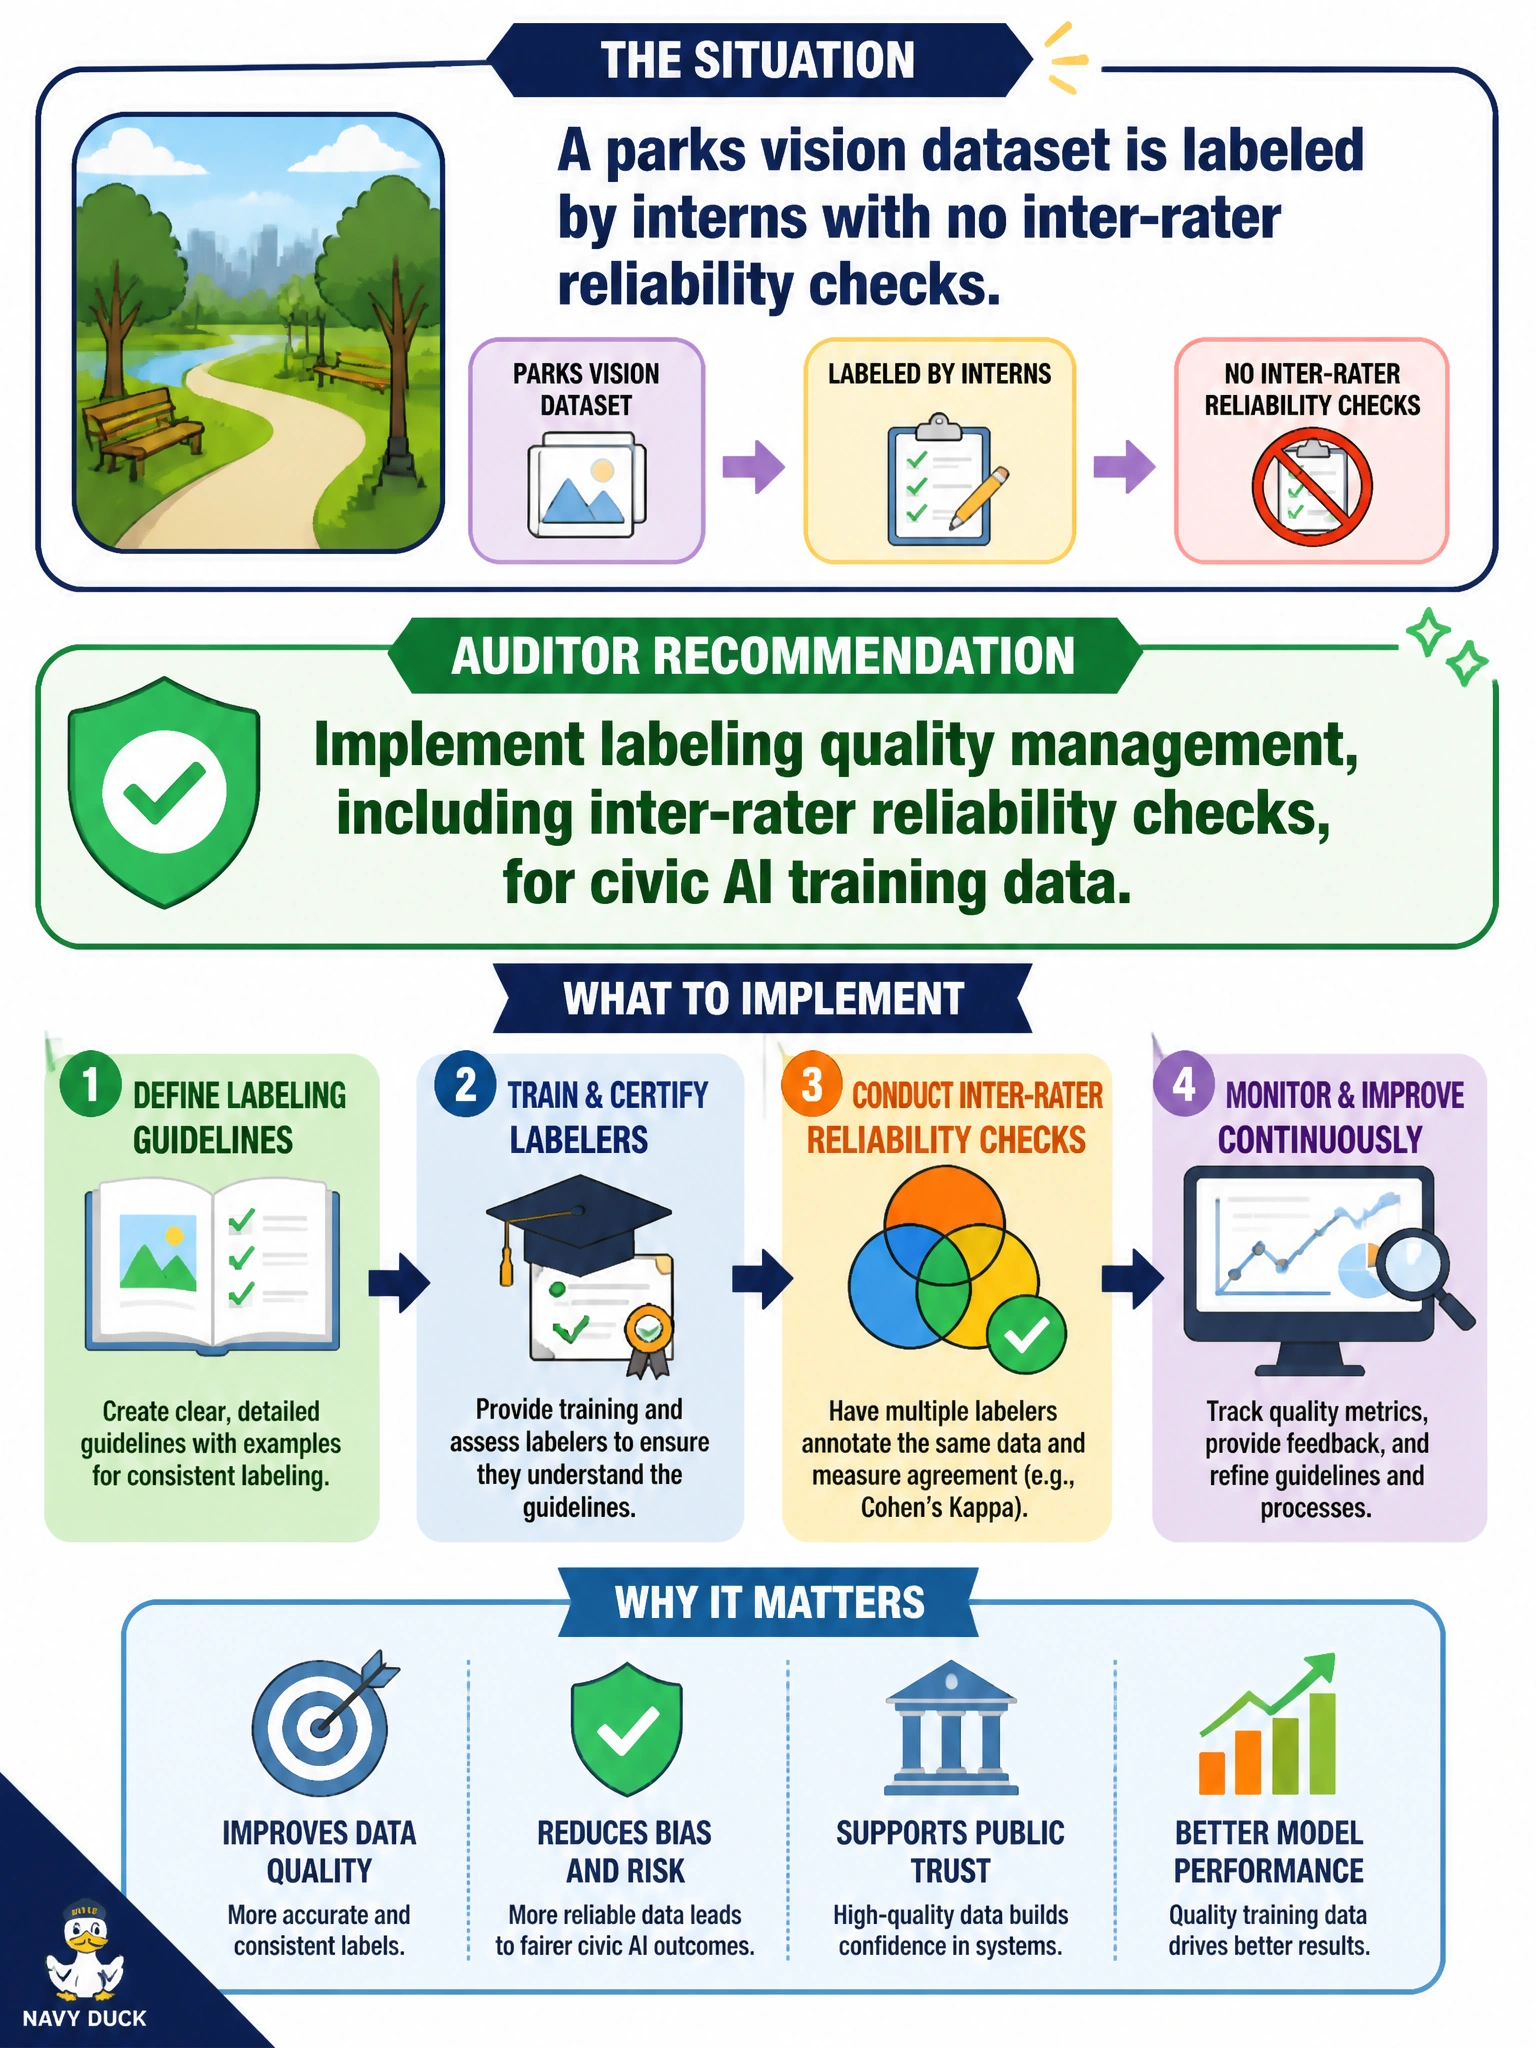
A parks vision dataset is labeled by interns with no inter-rater reliability checks. What should the auditor recommend?
Select an answer to reveal the explanation.
Short Explanation
Interns can be great labelers — or three different stories about the same trail photo. Check agreement across the whole labeling pool, not just your two best people. A narrow baseline doesn't fix messy labels for everyone else.
Full Explanation
A parks vision dataset labeled by interns with no inter-rater reliability checks can embed inconsistent ground truth that degrades computer-vision performance for trail or asset recognition. The auditor should recommend implementing labeling quality management, including inter-rater reliability checks, for civic AI training data so multiple labelers are compared on overlapping samples, disagreements are adjudicated, and guidelines are refined before the model trains on noisy labels. Using post-training model accuracy on held-out data to confirm intern labeling quality for the parks dataset fails by concept: held-out accuracy measures model performance, not labeler agreement, and a model can perform acceptably even when training labels are inconsistent or noisy. Measuring agreement only between the two most-experienced annotators to set a baseline fails by concept: a baseline drawn from just two labelers does not surface the inconsistency among the full intern pool actually producing the training labels. Recording annotator training completion and supervision hours as evidence of labeling process control for the civic vision program fails by concept: training hours and completion records are process proxies, not proof that labels agree across annotators or reflect consistent ground truth; they do not replace inter-rater reliability checks. Exam caveat: AAIA AI data-management items on labeling QA include agreement/reliability measures for training sets—not post-training held-out accuracy as a label-quality substitute, or annotator training hours and completion records as evidence of label reliability. Operational check: define labeling guidelines, require overlapping double-labels with inter-rater metrics, adjudicate disagreements, retrain guidelines when agreement is low, and retain QA metrics with each parks vision dataset version.