
A CIO at a multi-strategy hedge fund is selecting between three foundation models to power an earnings call summarization and sentiment classification system. The vendor benchmarks show strong scores on MMLU, HellaSwag, and HumanEval. Before deploying to production, the risk team requires rigorous domain-specific evaluation. Which evaluation methodology most accurately predicts real-world performance for this specific financial NLP use case?
Select an answer to reveal the explanation.
Short Explanation
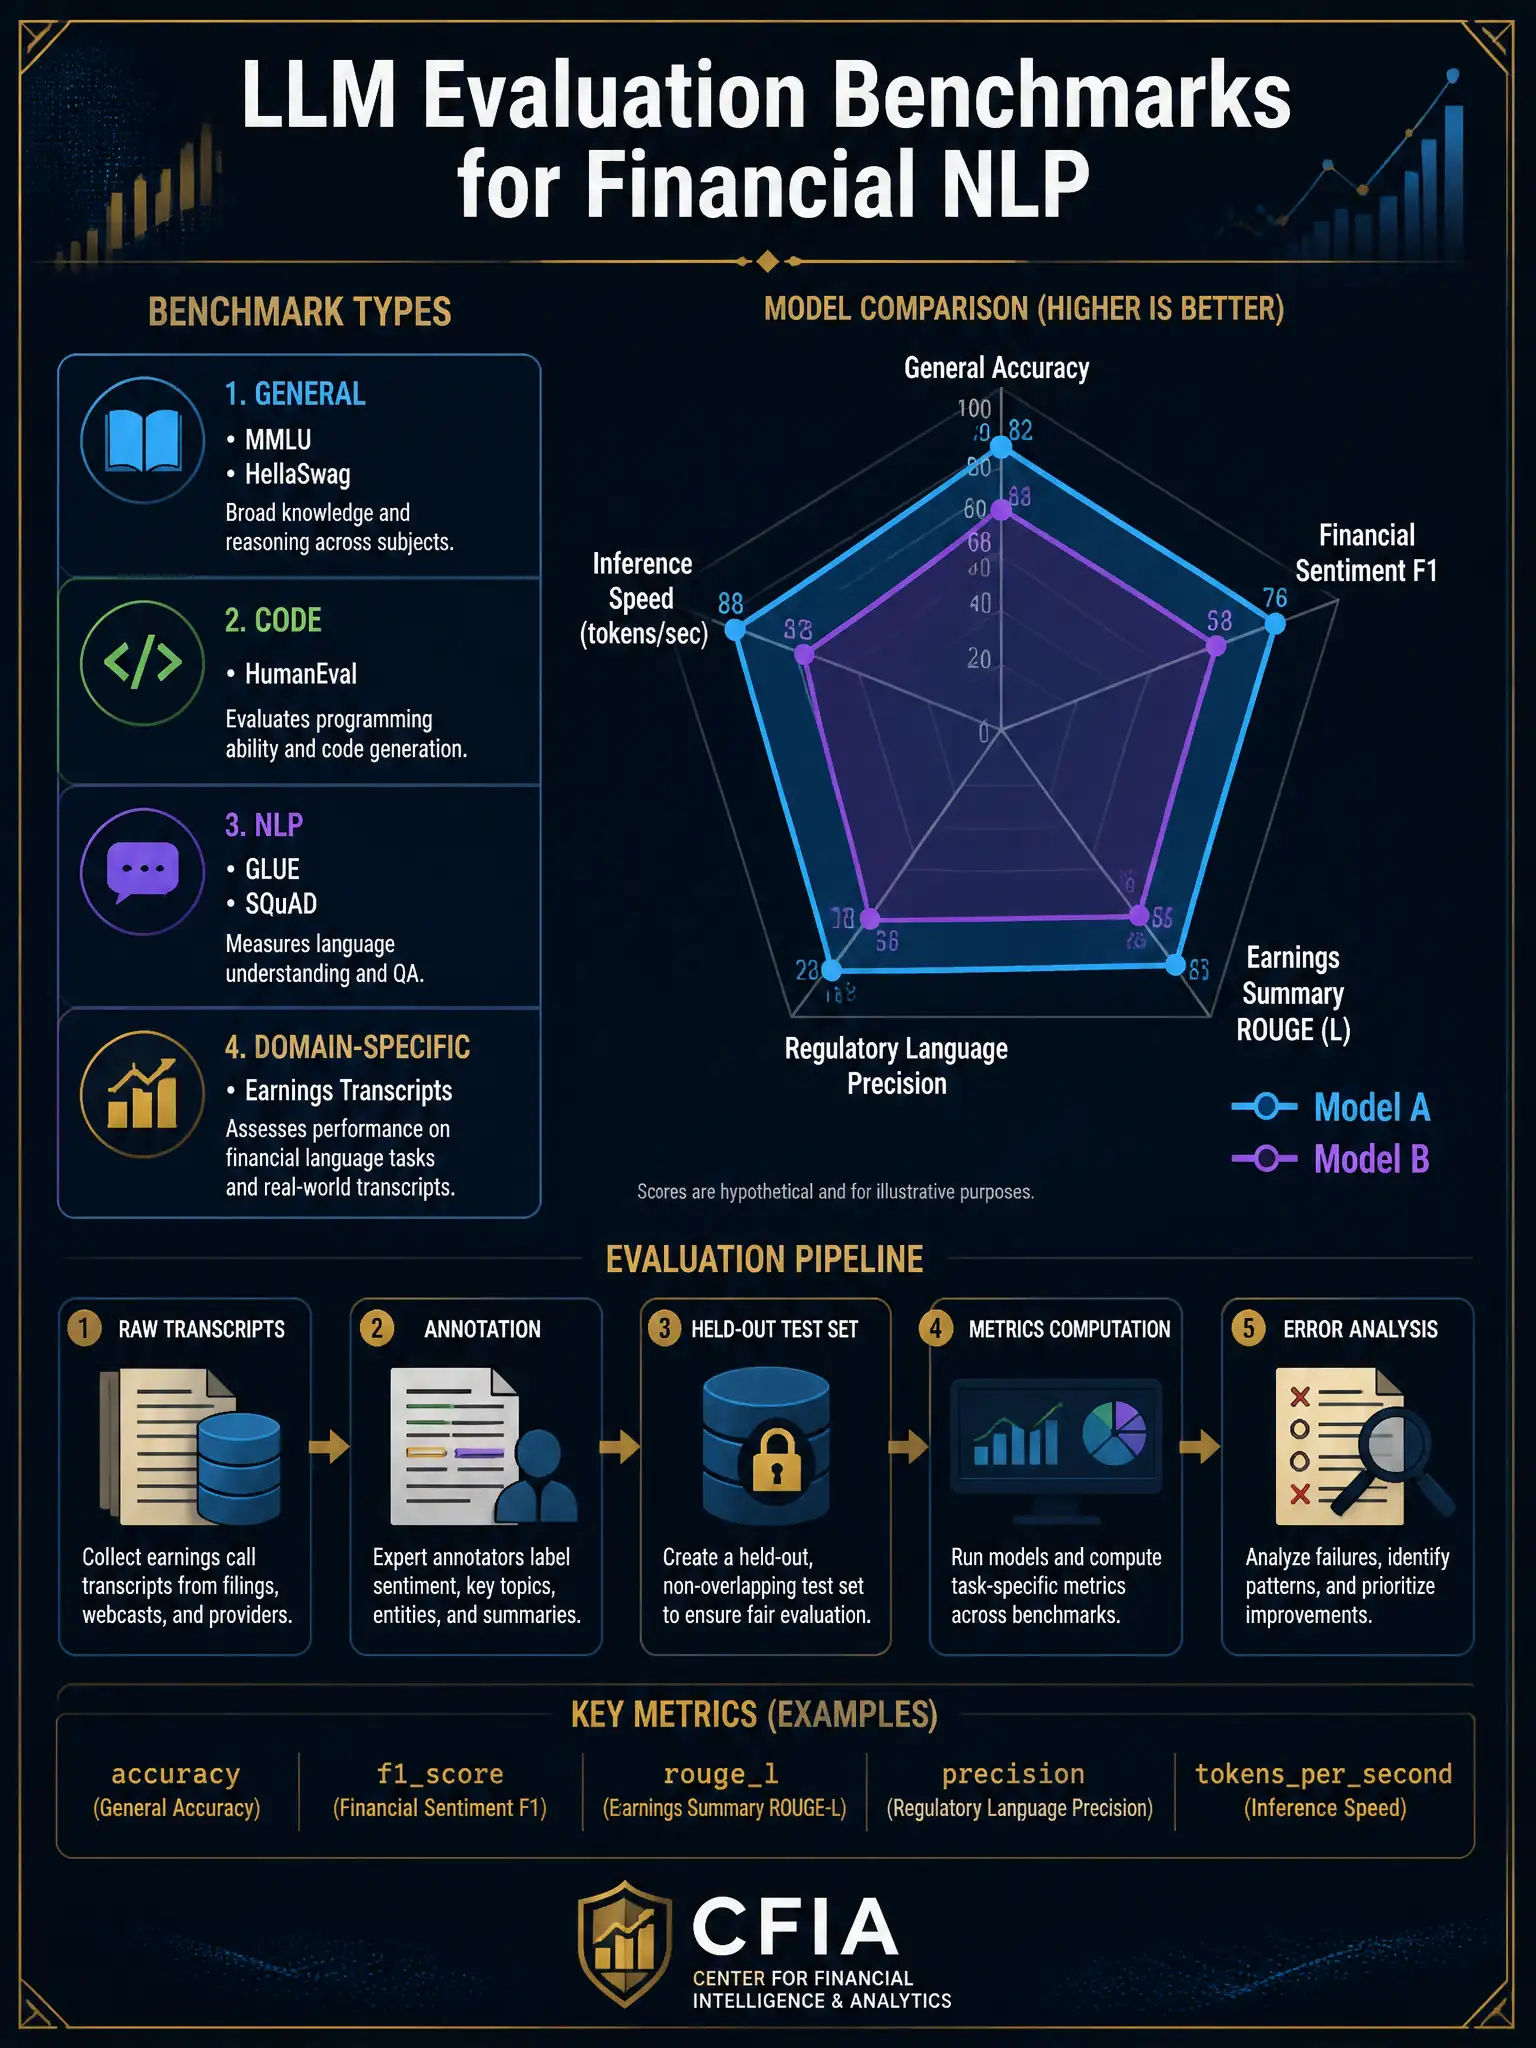
Buying a sports car because it won a drag race doesn't mean it'll handle a mountain rally — and picking an LLM based on MMLU scores for an earnings call system is the same mistake. Your model needs to be tested on the exact track it'll race on: real earnings transcripts, real sentiment labels, real financial jargon. The correct approach builds a domain-specific evaluation harness with the right inputs, the right outputs, and metrics that actually map to business value.
Full Explanation
General-purpose LLM benchmarks such as MMLU, HellaSwag, and HumanEval measure broad reasoning, commonsense understanding, and code generation respectively. While useful for gross capability screening, they exhibit poor predictive validity for narrow, high-stakes financial NLP tasks. Domain shift — the divergence between benchmark distribution and production distribution — is the central challenge in enterprise AI deployment, and it is particularly acute in finance where terminology, context, and interpretive norms differ substantially from general text corpora. The approach that accepts vendor-published MMLU scores as sufficient is flawed because MMLU finance questions test factual recall rather than the nuanced summarization and sentiment inference required on live earnings calls. A model that aces multiple-choice economics questions may still misclassify management guidance tone as bullish when analysts would read it as hedged. The approach that runs each model on a standard academic NLP benchmark suite such as SQuAD, GLUE, or SuperGLUE and selects the highest scorer shares the same domain-shift problem. SQuAD tests extractive question answering on Wikipedia; GLUE evaluates sentence relationship tasks; SuperGLUE is part of the same general academic benchmark family. None of these approximates the challenge of summarizing a 90-minute CEO presentation with domain-specific forward-looking statement caveats. The approach that evaluates models using a red-teaming adversarial prompt library to assess robustness to injection attacks and then selects the most robust model regardless of task-specific accuracy metrics addresses a real concern but is orthogonal to task performance. Adversarial robustness evaluation should be a separate, parallel workstream — not a substitute for accuracy benchmarking. A model that resists prompt injection but generates inaccurate earnings summaries creates a different category of risk. The correct methodology follows the gold-standard practice established in the ML evaluation literature and codified in frameworks like the CFIA AI Deployment Readiness standard: construct a held-out, domain-representative evaluation set of labeled earnings call transcripts with human-annotated sentiment scores and extractive summaries; apply task-appropriate metrics such as ROUGE, including ROUGE-L, and BERTScore for summarization quality and precision/recall/F1 for sentiment classification; and perform structured error analysis on failure cases specific to financial language, including systematic failure modes such as mishandling of non-GAAP adjustments or management guidance hedges. This methodology provides the statistical signal needed for a defensible model selection decision in a regulated investment management context.