
A quantitative research team discovers that their backtesting results have been consistently inflated by look-ahead bias. Investigation reveals that their data warehouse stores only the most current version of fundamental data — when companies restate earnings, the restated figures overwrite the original reported values, making historical data appear as though the restated figures were known at the time of the original announcement. Which database design pattern specifically and completely solves this problem?
Select an answer to reveal the explanation.
Short Explanation
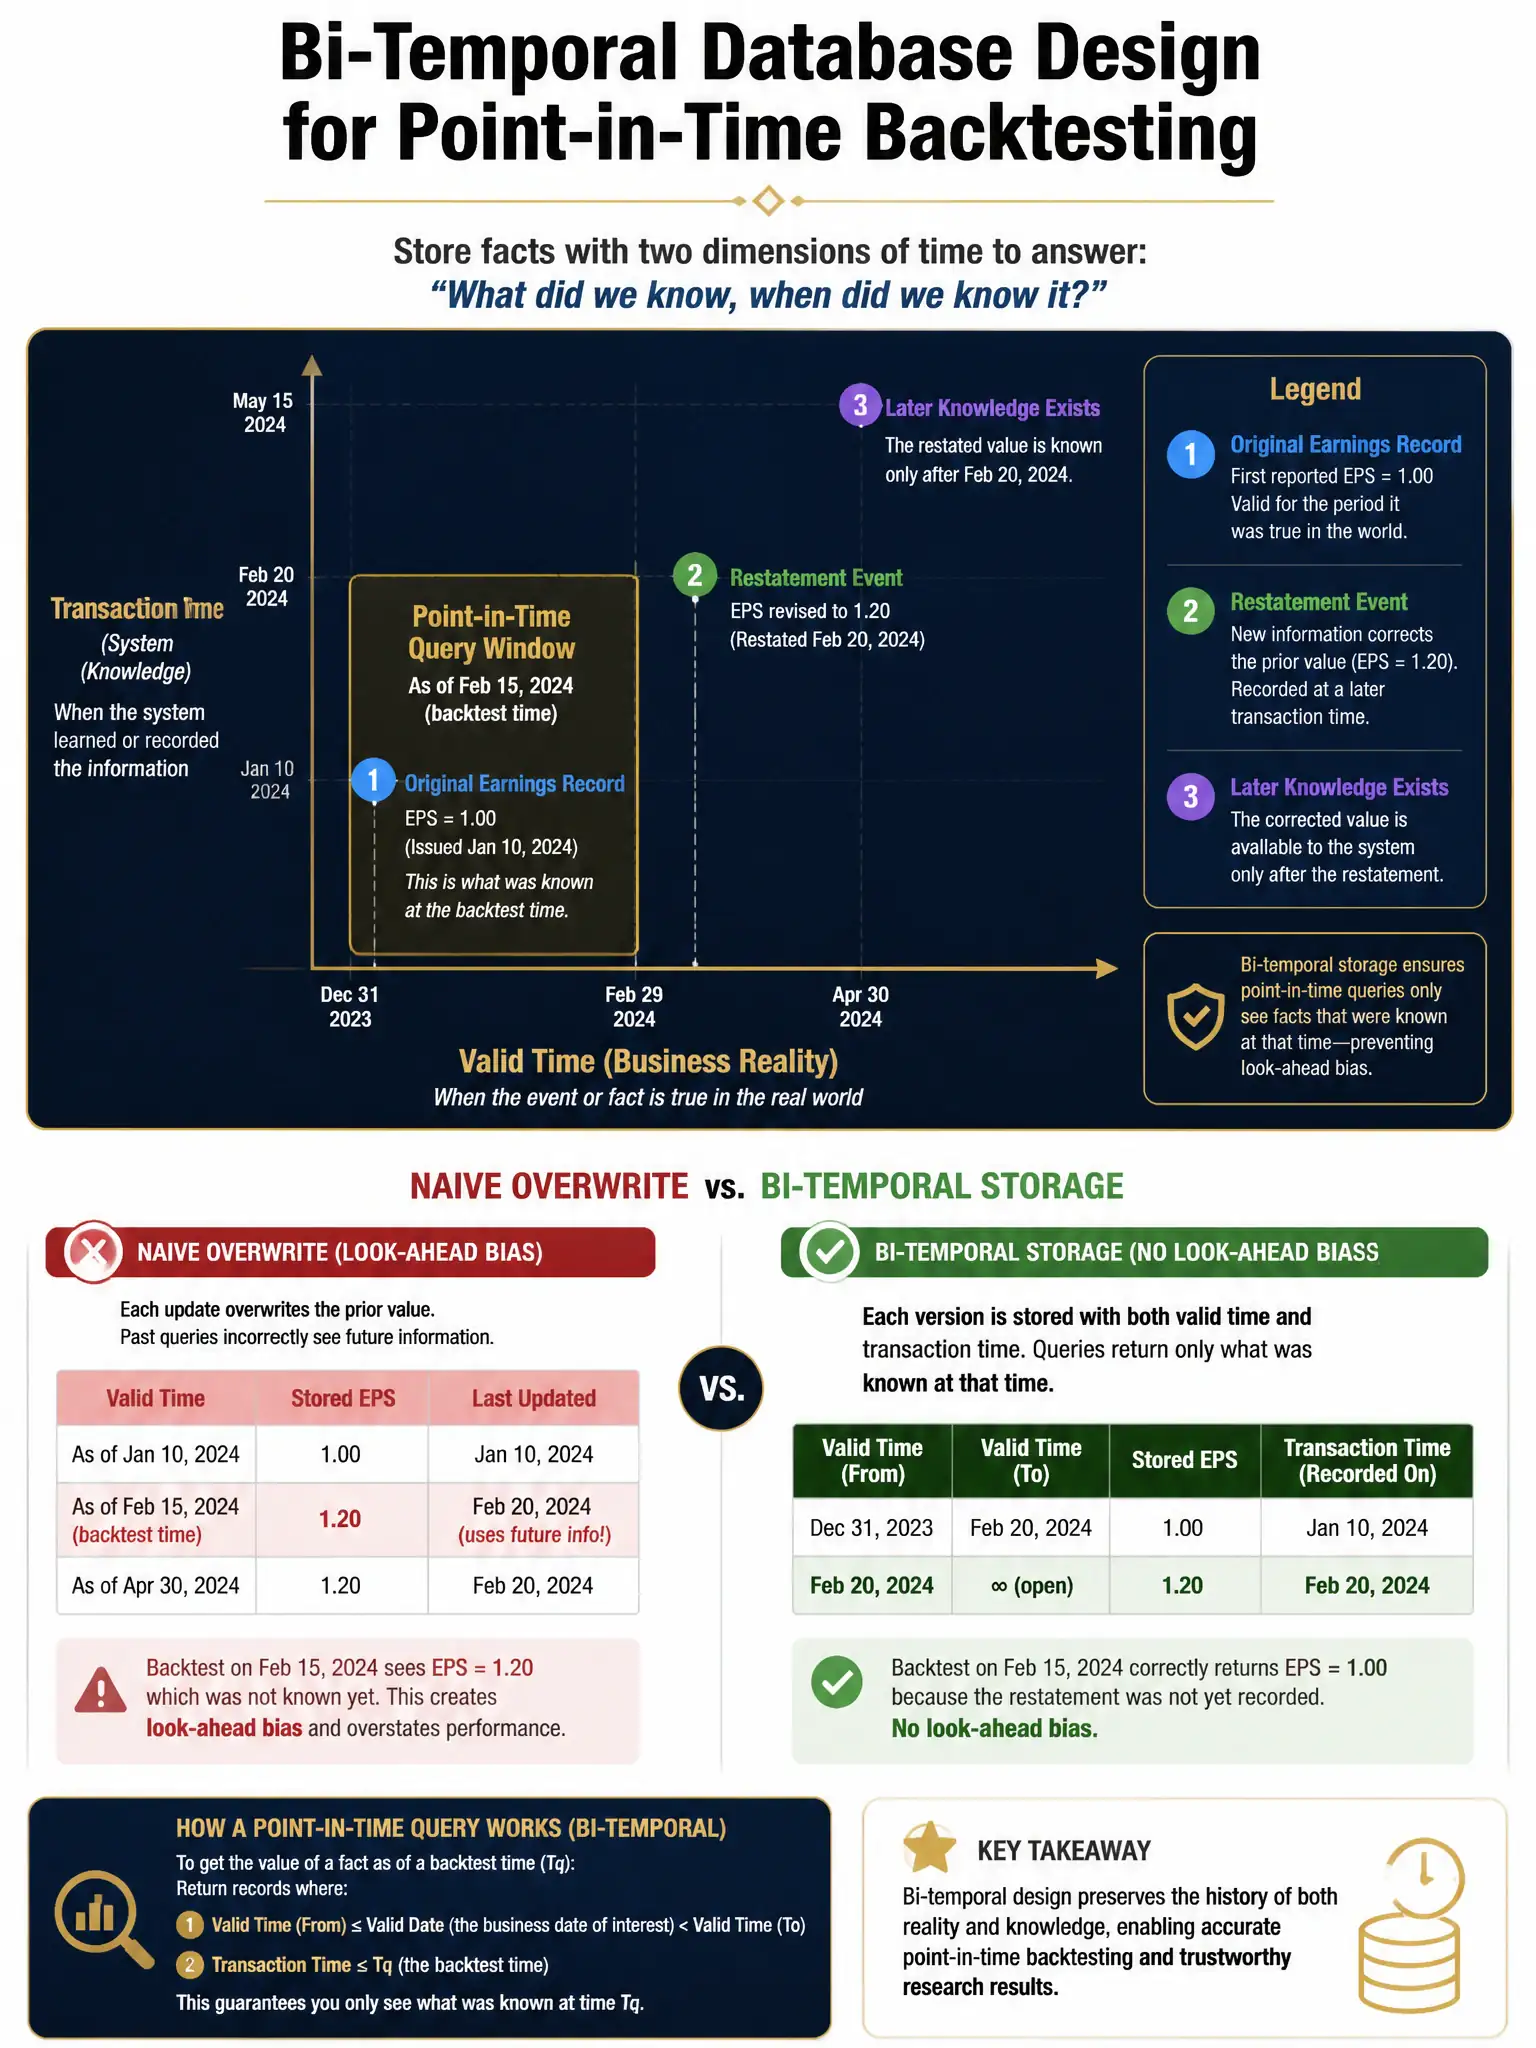
You need both the real-world date a fact was true and the date your database learned it. Bi-temporal database design stores valid time and transaction time, so your backtest sees only what was known then. That's how you stop restated earnings from inflating results.
Full Explanation
Look-ahead bias is one of the most insidious sources of alpha inflation in quantitative research. When a company restates Q2 earnings in November, a naive database overwrites the original Q2 figure with the restated one. A backtest run against this data in January 'knows' the restated figure when constructing signals for Q2 — information that was impossible to have at that time. The result is a strategy that looks profitable in backtesting but fails in live trading.
Bi-temporal modeling, formalized in SQL:2011 through the PERIOD syntax, solves this by maintaining two independent time dimensions for every row. The valid time axis captures the business reality: Q2 earnings of $1.23/share were reported on August 15. The transaction time axis captures the system reality: this value was recorded in our database on August 15, then superseded by a restated value of $1.31/share recorded on November 3. A point-in-time query asking 'what did our database know about Q2 earnings as of September 1?' returns the original $1.23/share — because the restatement had not yet been recorded in the system at that date.
Industry implementations include CRSP (Center for Research in Security Prices) and Compustat, which are the gold-standard academic and institutional data sources precisely because they maintain point-in-time histories. kdb+/q, the time-series database widely used in high-frequency trading, supports temporal queries natively. Snowflake's Time Travel feature and PostgreSQL's temporal table extensions provide accessible implementations for firms building proprietary data infrastructure.
The read-replica approach only separates query loads — it does not prevent overwrite of historical values and provides no point-in-time capability. The daily-snapshot approach approximates bi-temporality but is storage-inefficient (full database copies daily) and provides only day-level granularity, missing intraday corrections. The hash-based versioning approach has no standardized query interface for point-in-time retrieval and requires custom application logic that replicates what bi-temporal design provides natively. Bi-temporal design is the only pattern that solves both the valid-time and transaction-time dimensions of the problem simultaneously.