
An investment firm's technology team is designing an ingestion pipeline to process 10,000 earnings call transcripts, SEC filings, and analyst reports per month. They need to extract structured financial entities — revenue figures, guidance statements, and risk factors — and store them for downstream LLM querying and quantitative model consumption. Which pipeline architecture is most appropriate for this scale and use case?
Select an answer to reveal the explanation.
Short Explanation
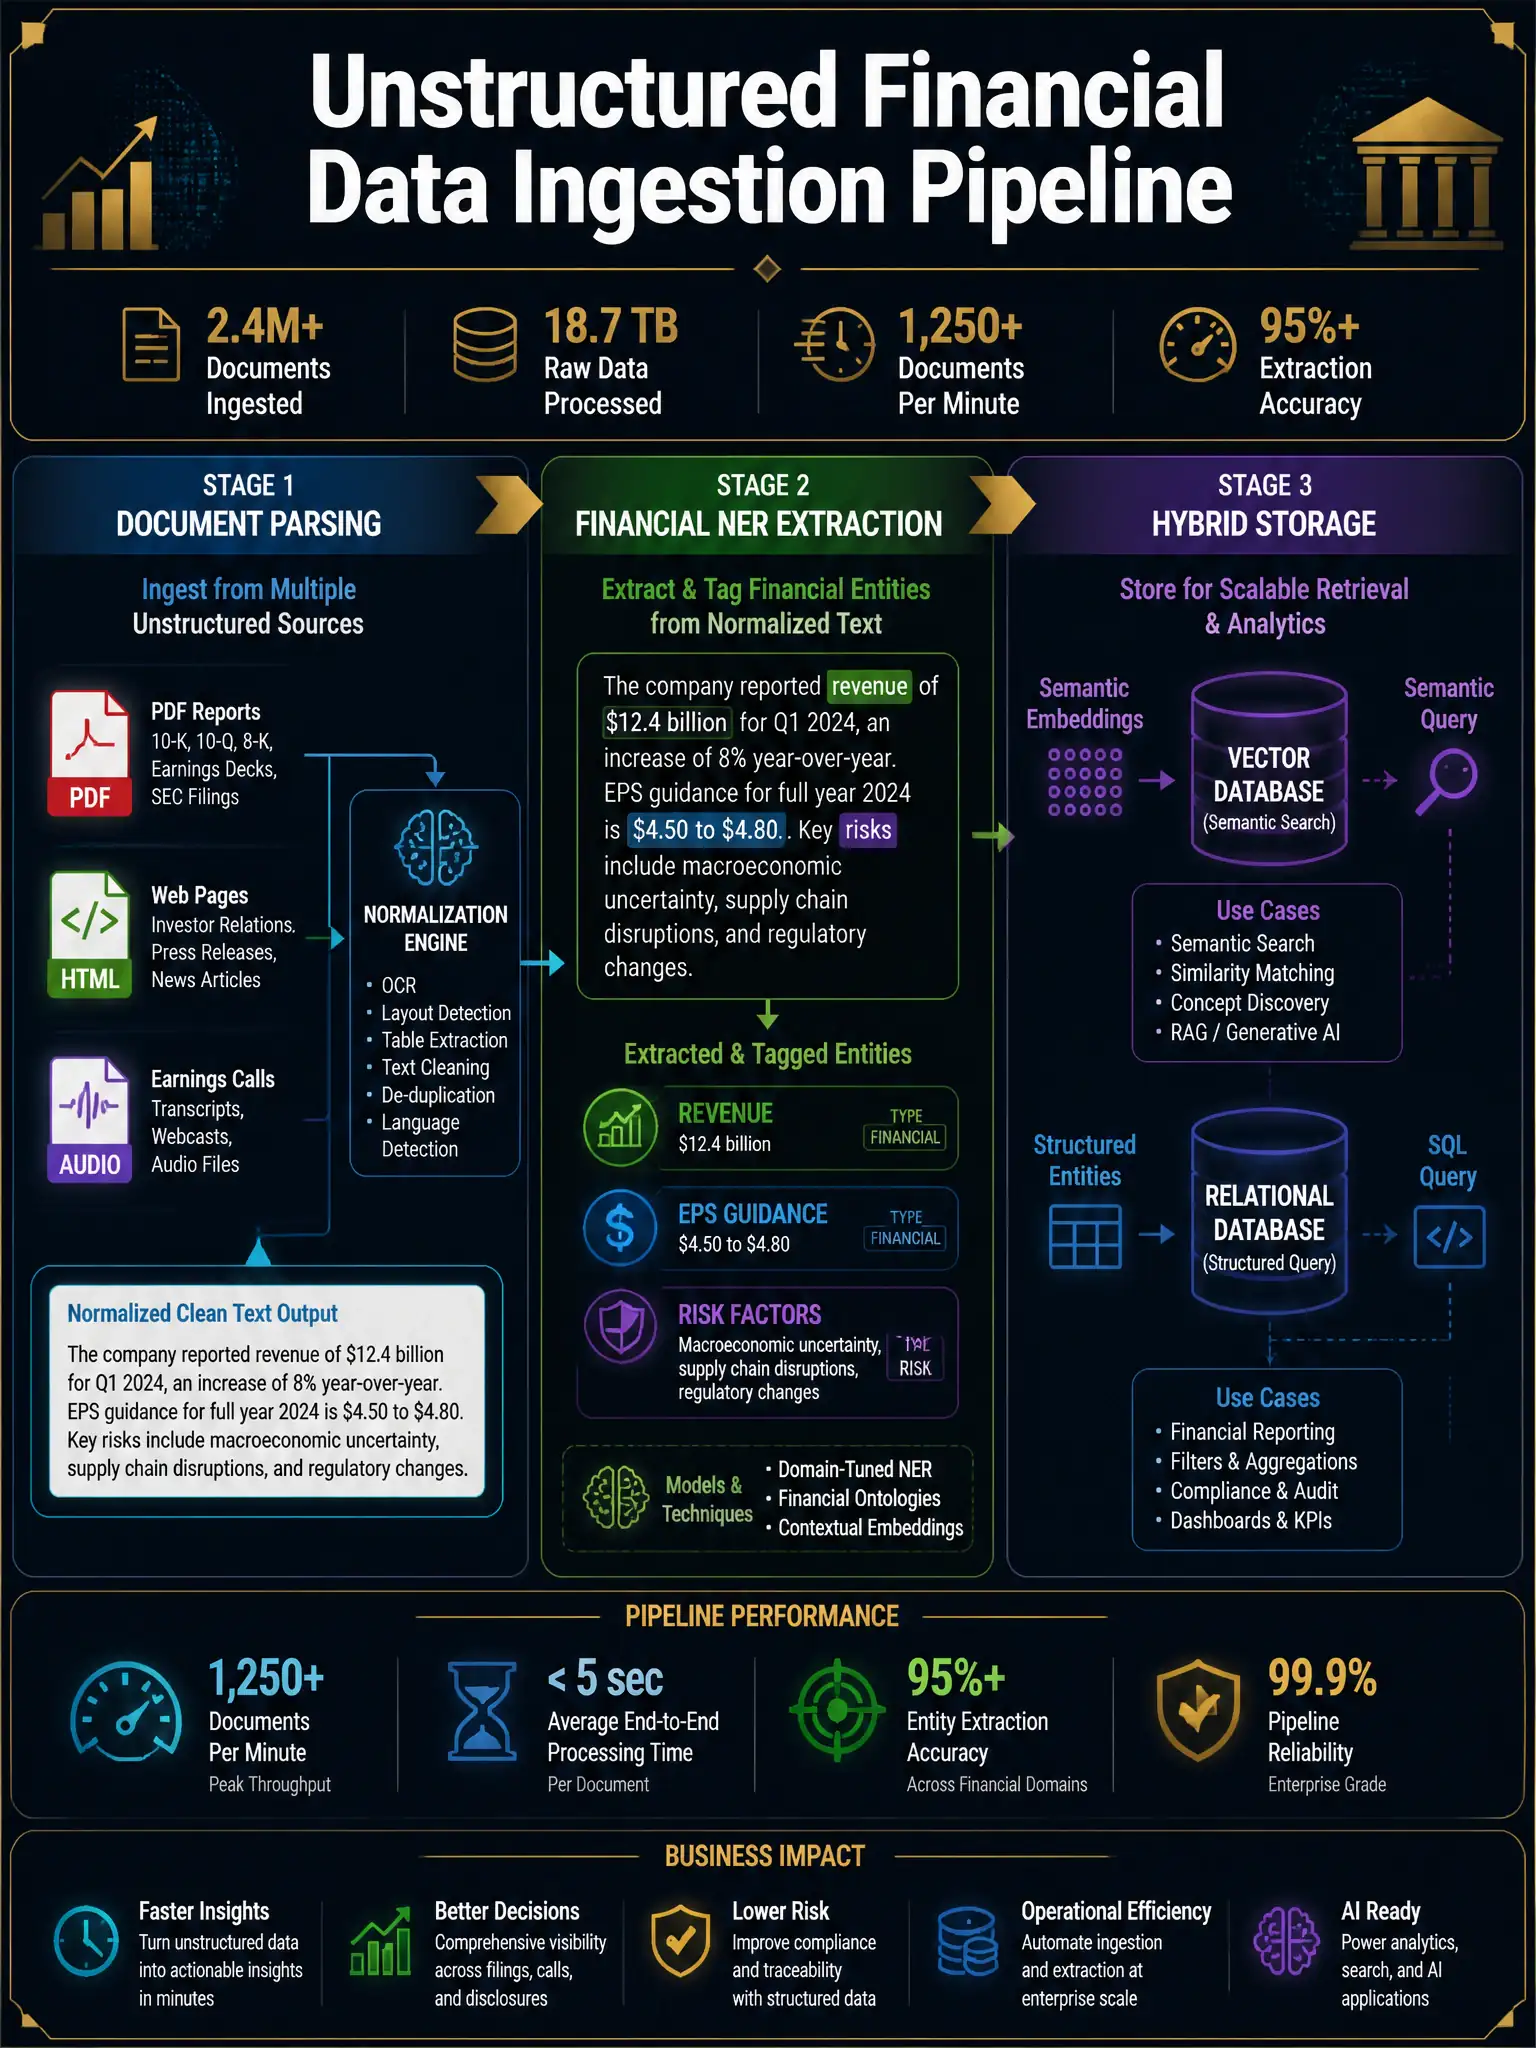
You don't dump raw ore into a furnace and expect clean metal. You refine it in stages. The three-stage pipeline normalizes documents, extracts financial entities, then stores them for semantic and structured queries, making downstream LLM work cheaper and more reliable.
Full Explanation
Unstructured financial documents arrive in heterogeneous formats — PDFs with complex tables, HTML filings, audio transcripts, and scanned images — each requiring different parsing logic. Sending raw document bytes directly to a general-purpose LLM API for extraction on each query, relying on the model's in-context parsing to handle all document formats dynamically, is prohibitively expensive at 10,000 documents per month, produces inconsistent entity extraction across formats, and wastes context window capacity on boilerplate content that should have been stripped in preprocessing. The three-stage architecture is the industry-validated approach. In the parsing stage, tools like Unstructured.io or LlamaIndex's document loaders normalize diverse formats into consistent text chunks with preserved metadata such as page numbers, section headers, and document type. PyMuPDF handles PDF table extraction while preserving numeric formatting critical for financial data. This normalization layer is what separates professional-grade pipelines from ad-hoc implementations. In the extraction stage, financial domain-specific NER models are applied rather than general NLP models. FinBERT and its derivatives are fine-tuned on financial corpora to recognize entities like revenue figures, EPS guidance, risk factor classifications, and management sentiment with far higher precision than general-purpose models. This structured extraction step is what enables downstream quantitative analysis by converting unstructured text into queryable financial signals. In the storage stage, hybrid storage is used because different query patterns require different storage paradigms. Vector databases such as Pinecone, Weaviate, and pgvector support semantic similarity search for analyst-style research queries. Relational databases such as PostgreSQL and Snowflake support structured aggregation, for example showing all Q3 guidance revisions above 10%. The OCR-and-keyword-search approach destroys semantic meaning by reducing documents to term-frequency retrieval. The manual analyst review queue cannot scale to 10,000 monthly documents and introduces human latency. The three-stage approach treats each concern separately and uses purpose-built tools at each layer.