
A European investment firm's data science team proposes training a client churn-prediction AI model using five years of historical transaction records, behavioral data, and financial advisory notes containing personal client information. The firm's DPO flags potential GDPR compliance issues. Which action best aligns the project with GDPR requirements for AI training data?
Select an answer to reveal the explanation.
Short Explanation
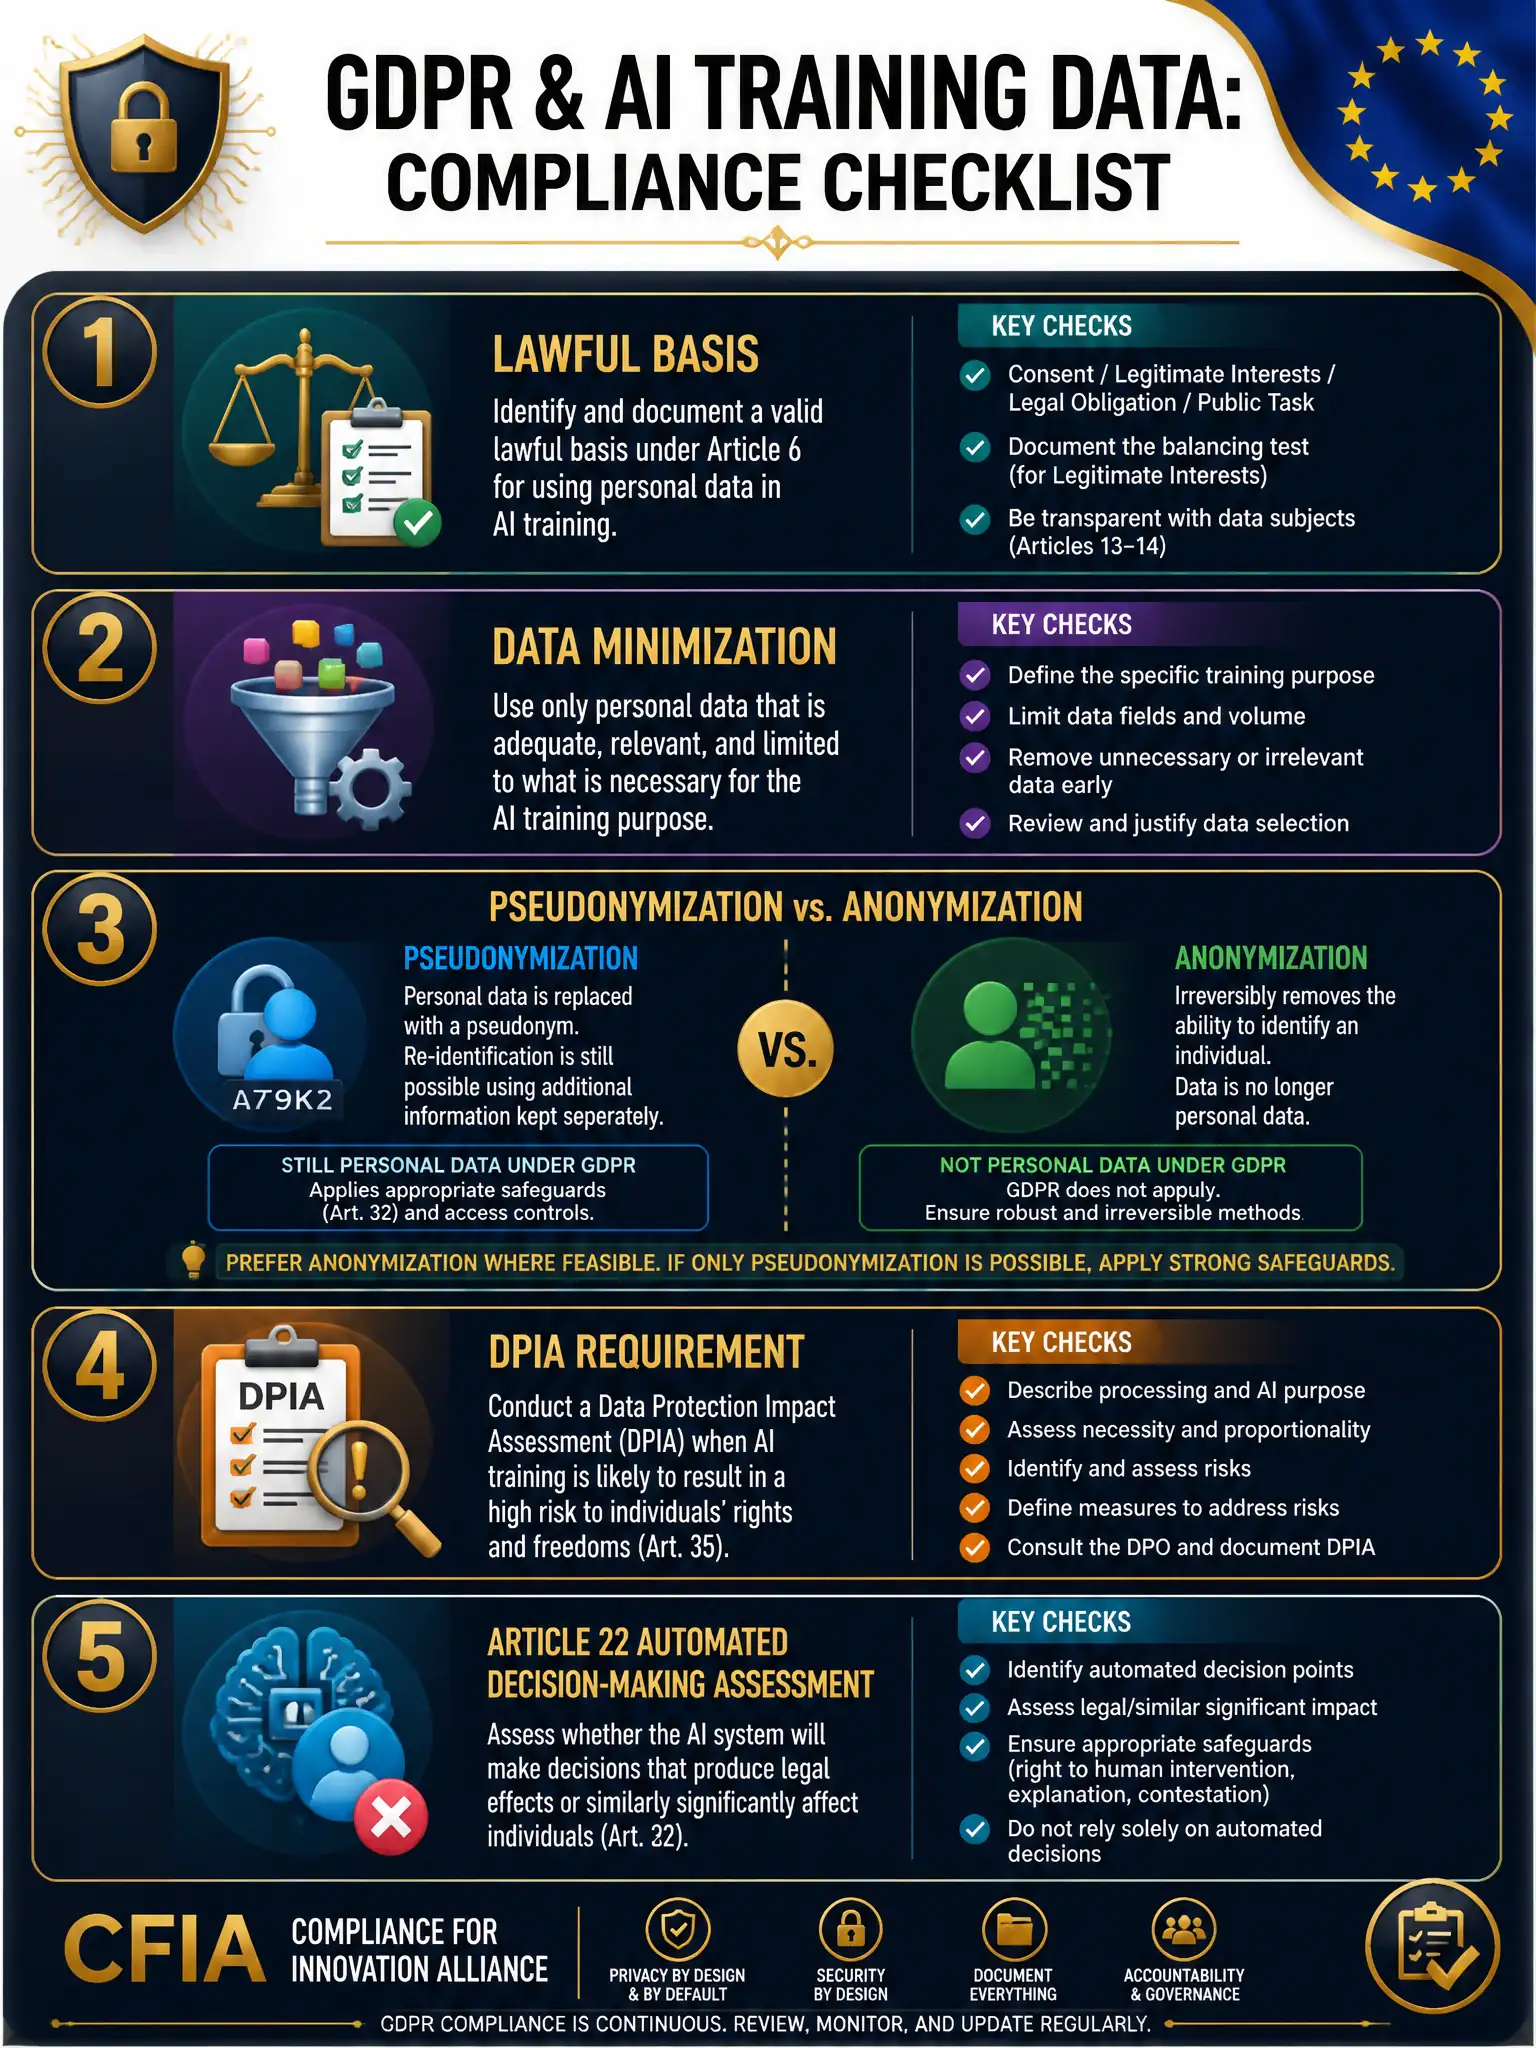
GDPR doesn't disappear just because you're building an AI model — it follows the data. Think of it as a chain of custody: every step from collection to model output needs a lawful basis and documented safeguards. The right path is to establish lawful processing, minimize and pseudonymize the data, run a DPIA, and check Article 22 if the model drives significant client decisions.
Full Explanation
GDPR (EU Regulation 2016/679) applies to the processing of personal data of EU data subjects regardless of the purpose — including AI model training. Financial services firms are not exempt; the Recital 47 legitimate interests basis and Article 6 lawful bases apply to internal analytics and AI development in the same way they apply to direct marketing or profiling. The option claiming financial firms are exempt from GDPR when processing client data for internal risk management purposes is incorrect because no blanket financial services exemption exists under GDPR for AI training. The option proposing broad upfront consent from all clients for any future AI development purposes misrepresents consent requirements — GDPR requires consent to be specific, informed, and granular. Broad upfront consent for any future AI development purposes would likely fail the specificity test under Article 7 and Recital 32 and could be challenged by regulators. The option relying on industry-standard tokenization as anonymization and proceeding without further GDPR analysis addresses a real GDPR carve-out, because anonymized data falls outside GDPR scope, but it critically understates the difficulty of achieving true anonymization. Tokenization is a pseudonymization technique, not anonymization — the original data remains re-linkable using the tokenization key. GDPR Recital 26 clarifies that pseudonymous data is still personal data. True anonymization is a high bar that survives regulatory scrutiny only when re-identification is effectively impossible, not merely unlikely. The correct option establishes a lawful processing basis, such as legitimate interests with a documented balancing test, applies data minimization and pseudonymization, conducts a DPIA, and assesses whether automated decision-making provisions under Article 22 apply. That pathway covers the full compliance picture: establish a lawful basis documented with a legitimate interests assessment if relying on Article 6 legitimate interests; apply data minimization by using only the data necessary for the model purpose; conduct a Data Protection Impact Assessment per Article 35 when processing is likely to result in high risk to individuals; and evaluate Article 22 obligations if the churn model feeds into automated decisions that produce legal or similarly significant effects on clients. CFIA candidates operating in EU-regulated environments must treat GDPR as a design constraint, not a post-hoc checkbox.