
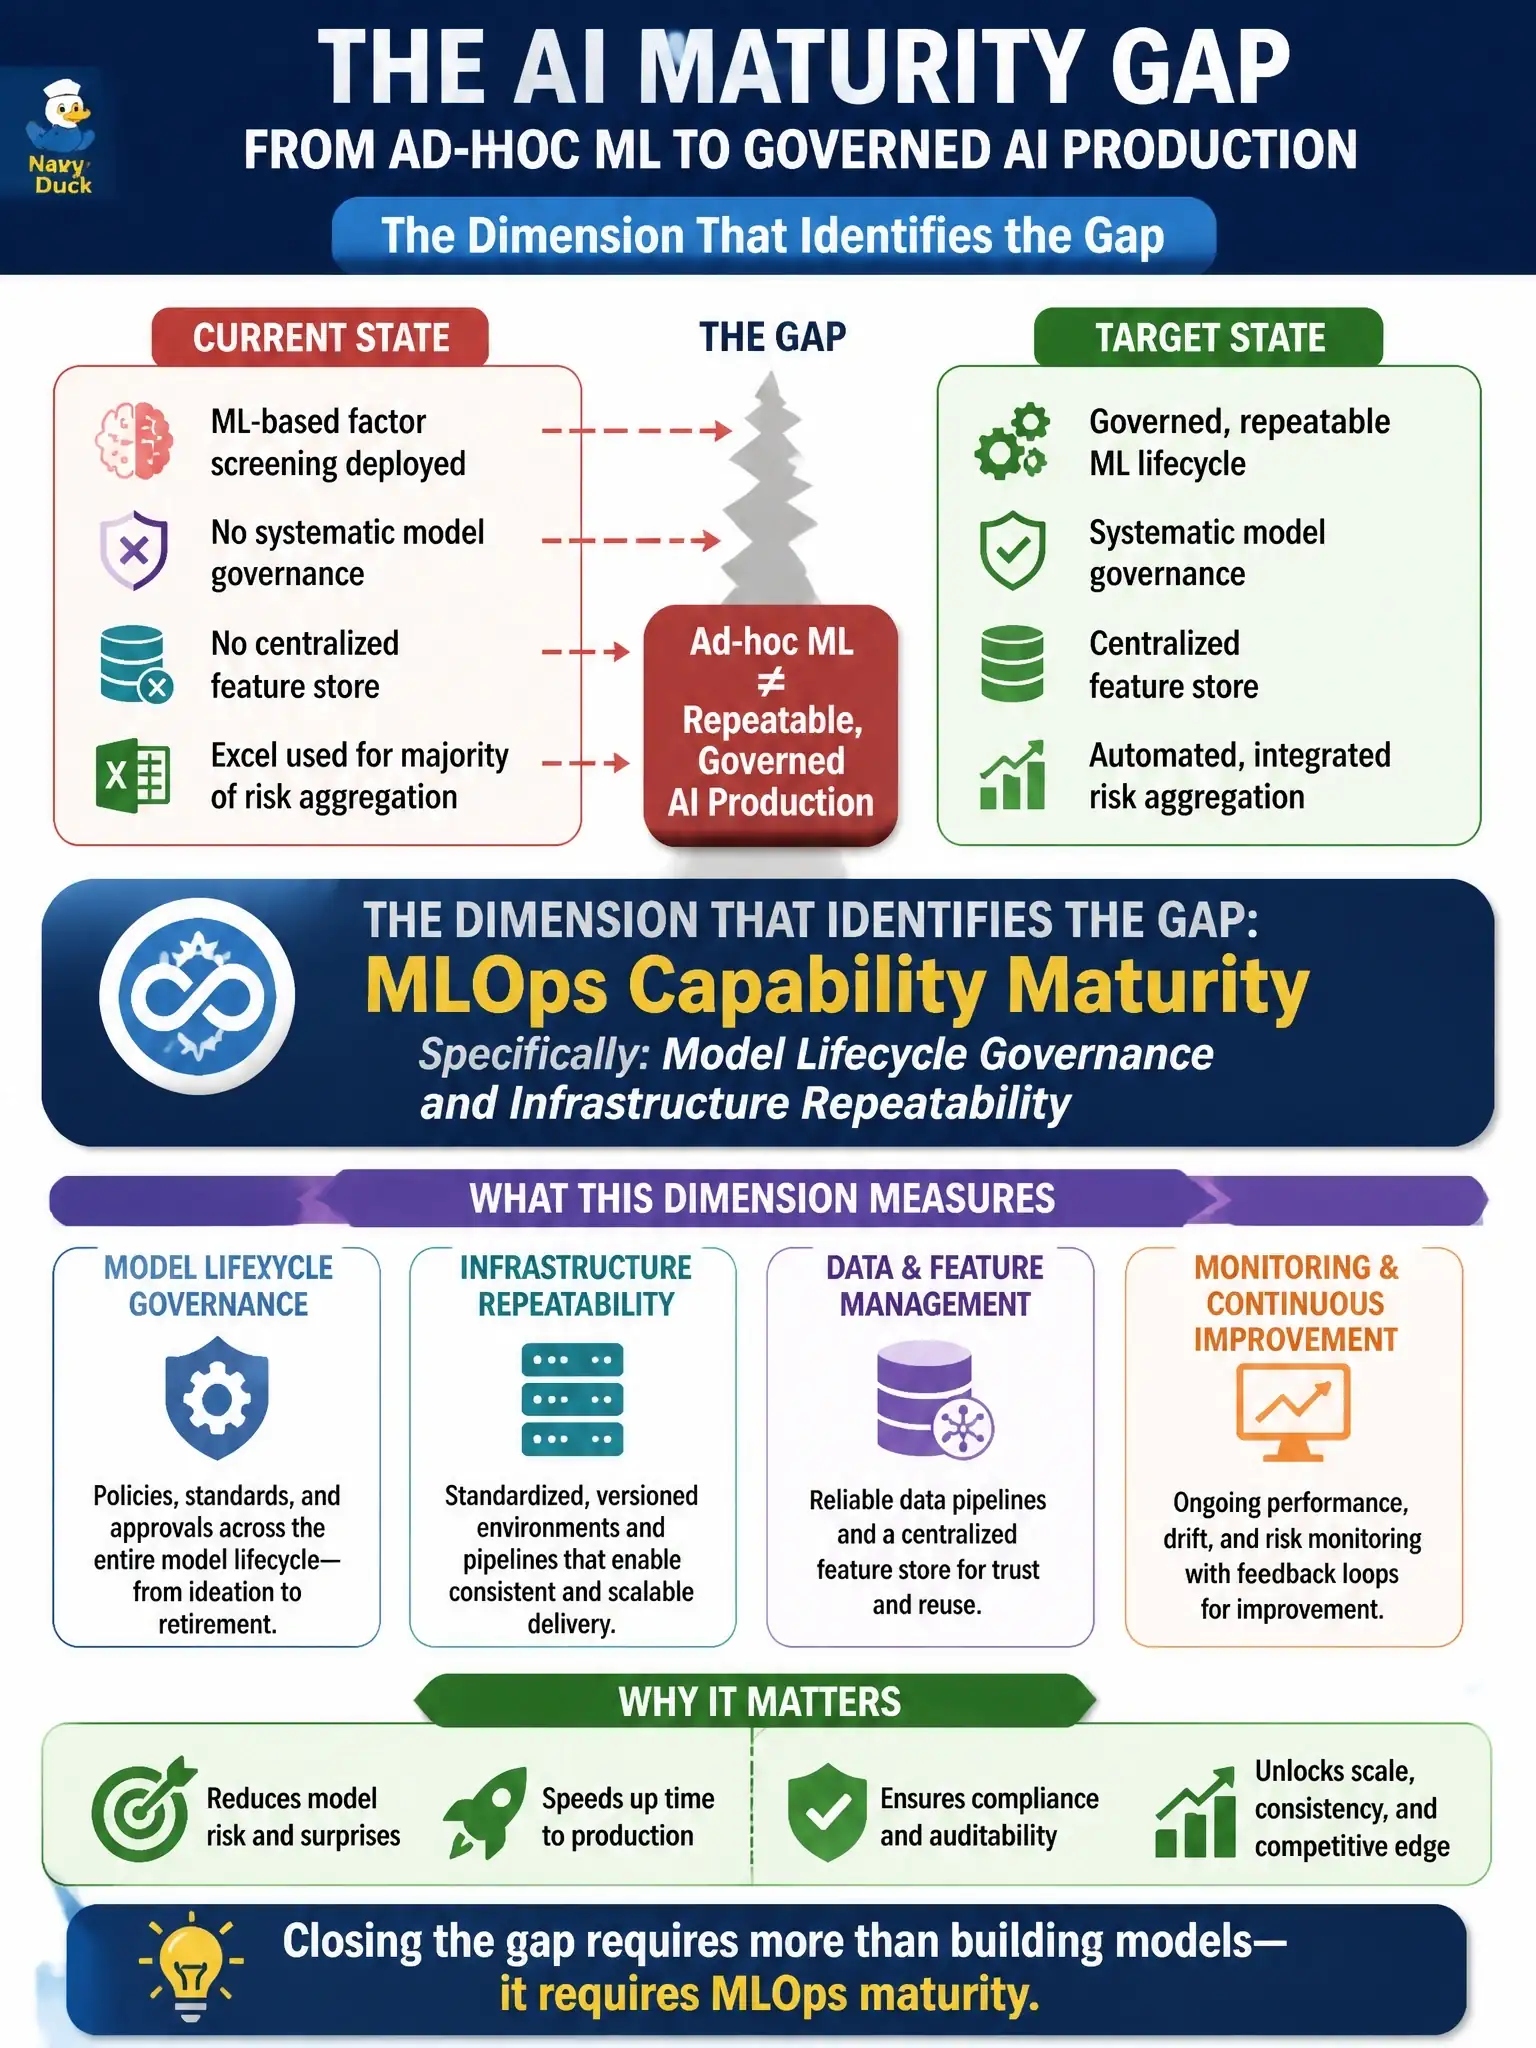
A $40B long-only equity manager wants to assess where it stands on the AI adoption curve relative to quantitative competitors. The CIO commissions an internal maturity review and discovers the firm has deployed ML-based factor screening but lacks systematic model governance, has no centralized feature store, and still uses Excel for a majority of risk aggregation. Which AI maturity framework dimension most directly identifies the gap between ad-hoc ML deployment and repeatable, governed AI production?
Select an answer to reveal the explanation.
Short Explanation
Think of AI maturity like a pilot's checklist — having ML models isn't the same as having repeatable, documented procedures that work the same way every time. You've got the plane, but you're missing the MLOps checklist: model lifecycle governance, feature stores, monitoring, and deployment pipelines. That's what turns ad-hoc ML into reliable AI production.
Full Explanation
AI maturity frameworks used in financial services — including variants of Google's MLOps Maturity Model, Gartner's AI Maturity Model, and elements of model risk guidance such as SR 26-2 (which superseded SR 11-7 in April 2026) — consistently identify MLOps capability as the hinge between experimentation and production-grade AI. The firm in this scenario exhibits classic Level 1 (ad-hoc) characteristics: models exist and produce outputs, but there is no centralized feature store (meaning features may be computed inconsistently across models), no model lifecycle governance (meaning champion/challenger regimes, version rollbacks, and drift monitoring are absent), and legacy tools remain in the critical risk path.
MLOps capability maturity, specifically model lifecycle governance and infrastructure repeatability, directly addresses all three gaps. A feature store enforces consistent, auditable feature computation. Model governance frameworks aligned with SR 26-2 call for documentation, validation, and ongoing monitoring scaled to model materiality. Replacing Excel in risk aggregation with governed pipelines eliminates fragility and supports regulatory examination. These are structural, repeatable capabilities, not one-off improvements.
Data volume benchmarking against peer AUM-weighted datasets confuses data scale with operational maturity. Firms can have petabytes of data and still run models in ad-hoc notebooks. Headcount ratio of data scientists to portfolio managers is a talent metric, not an infrastructure or process metric — a small, well-governed team outperforms a large ungoverned one. Number of live alpha signals deployed across factor strategies measures output quantity, not the quality or repeatability of the processes that produce and sustain those signals. The NIST AI RMF's 'Manage' function similarly emphasizes that operational processes and governance structures — not model count — determine whether AI deployment is trustworthy and sustainable.