
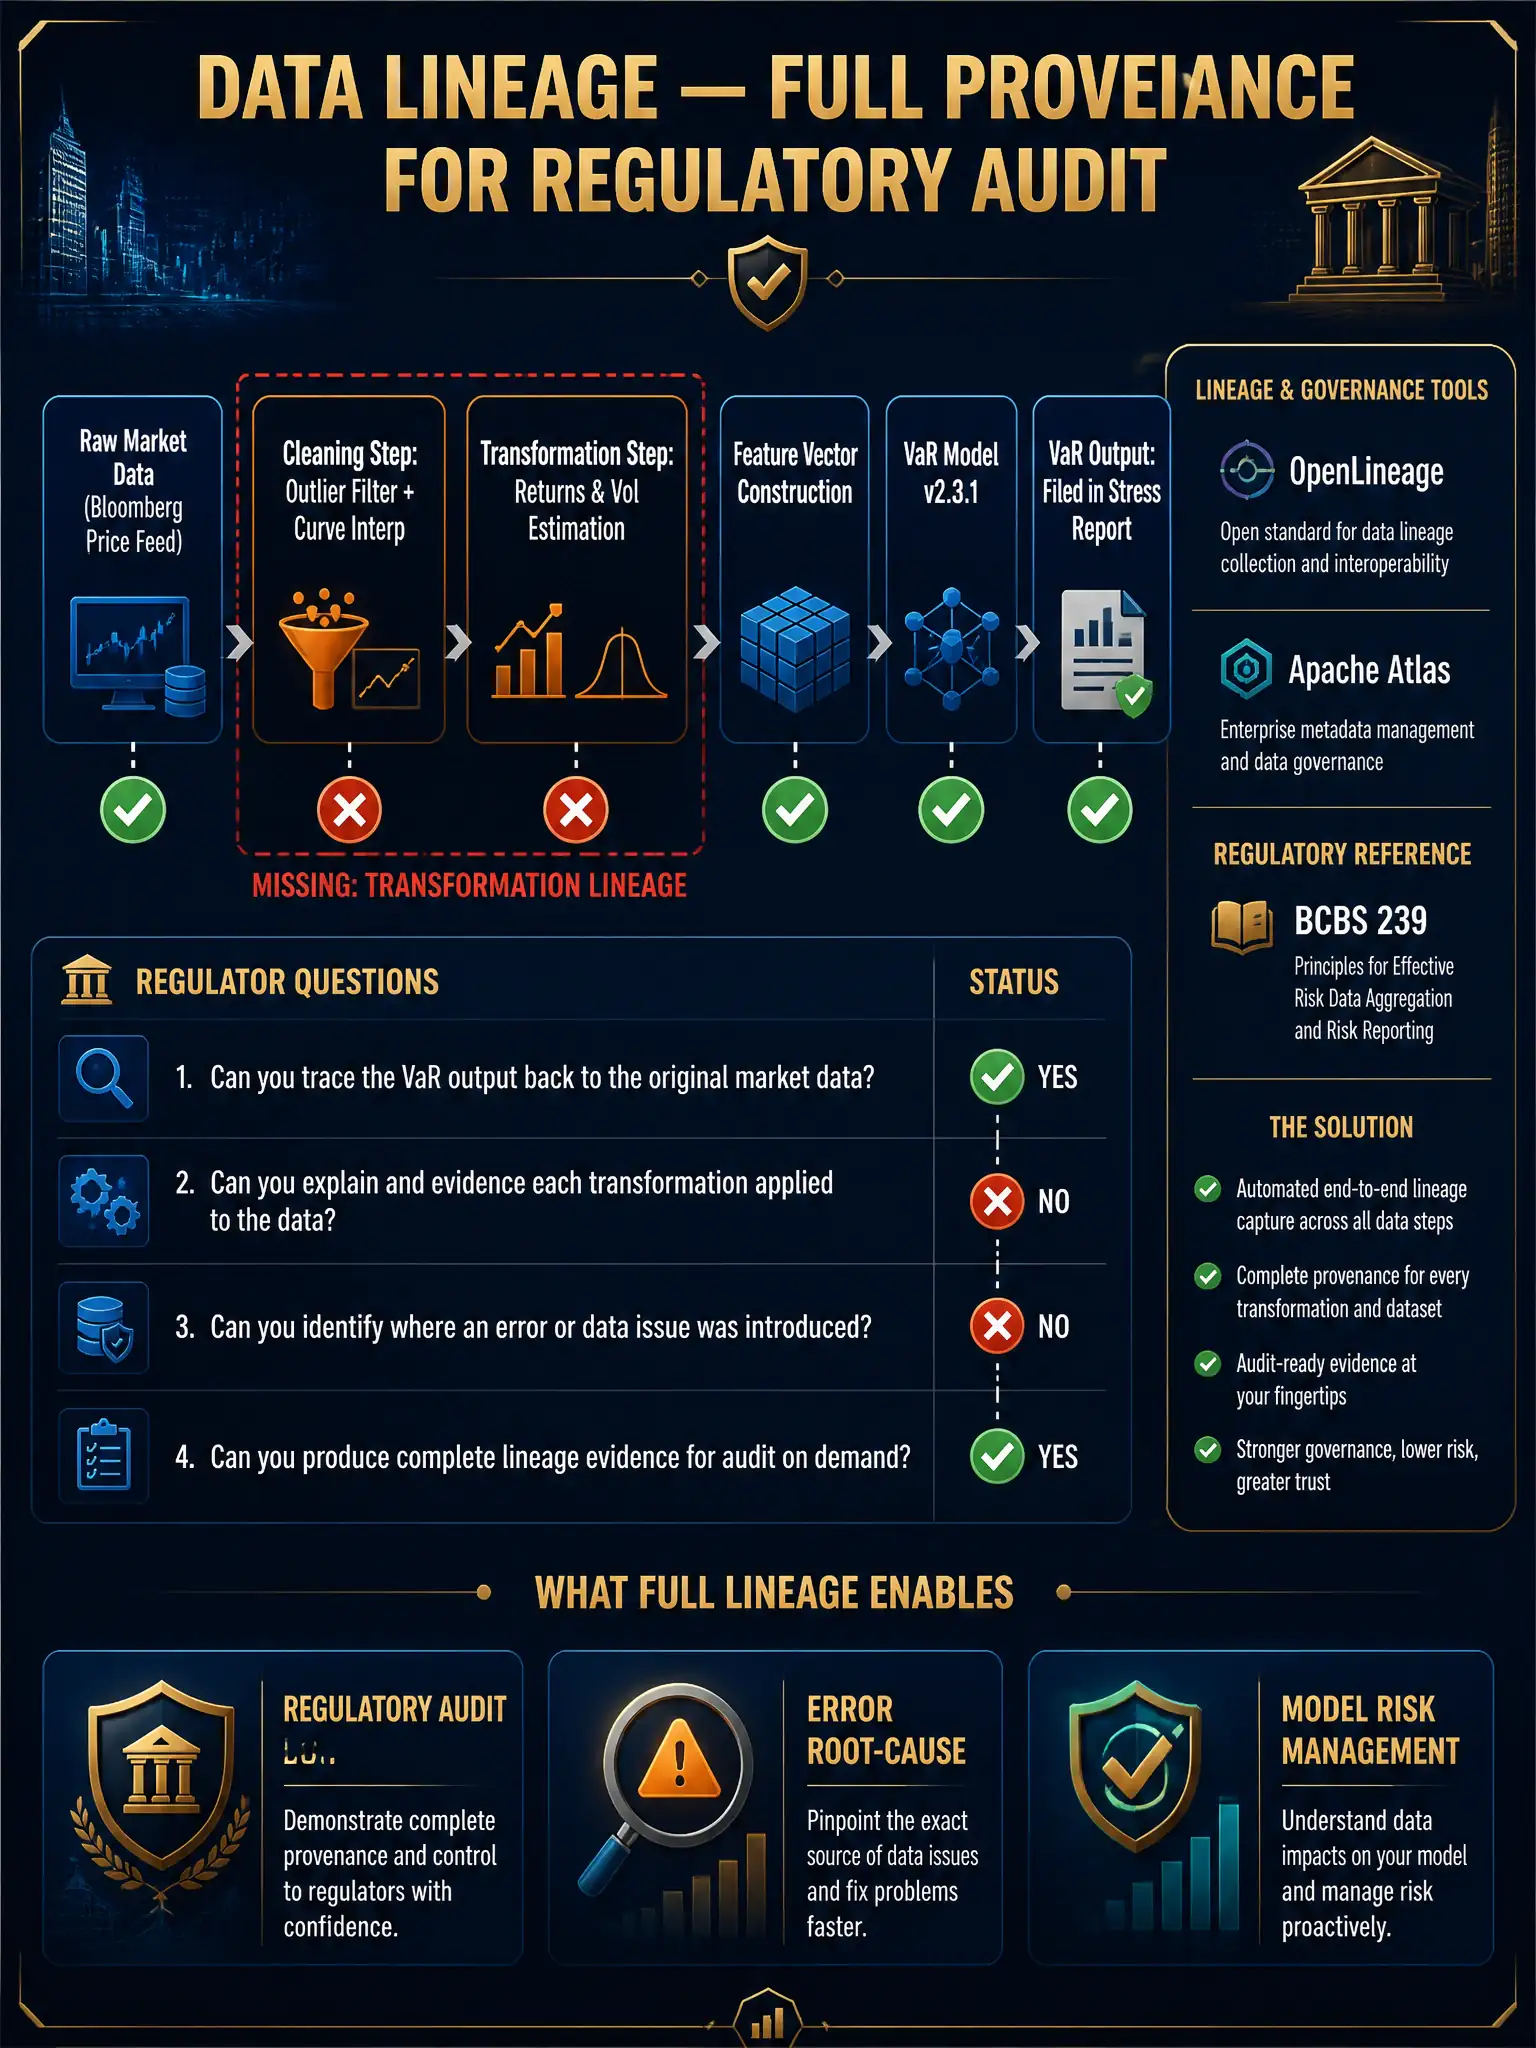
During a post-stress-event regulatory examination, a buy-side risk manager is asked by examiners to provide full provenance for a VaR figure that appeared in a stress report filed 18 months earlier. The examiners specifically request documentation of: (1) the exact raw market data inputs used on that date, (2) each data cleaning and transformation step applied, (3) which model version produced the VaR output, and (4) the compute environment in which the calculation ran. The firm's infrastructure logs model version tags and compute job IDs but does not track how raw market data was transformed before entering the risk engine. What critical data infrastructure capability is the firm MISSING?
Select an answer to reveal the explanation.
Short Explanation
You already know which model version ran, but you can't prove how raw market data became the VaR input. End-to-end data lineage tracks every ingestion, cleaning, join, filter, and transformation step from raw tick to final report. Without that provenance chain, you can't reconstruct the calculation for regulators.
Full Explanation
End-to-end data lineage tracking that captures the full provenance chain from raw data ingestion through every transformation step to the final model output is the missing capability. Data lineage is the documented record of where data originates, how it moves through a system, and how each transformation modifies it along the way. In the context of financial risk reporting, end-to-end lineage serves multiple critical functions: regulatory auditability (demonstrating to examiners exactly how a reported figure was derived), error investigation (identifying which transformation step introduced a pricing error), and model risk management (showing that model inputs were clean and correctly processed). The gap described in this scenario is specifically in the transformation layer: raw market data is ingested (from a price feed, for example), cleaned (outlier removal, curve interpolation, missing value imputation), transformed (returns computation, volatility estimation, correlation matrix construction), and then fed into the VaR model. None of these intermediate steps are being logged in a recoverable, queryable form. Data lineage systems record, for each calculation: the source dataset version (for example, Bloomberg pricing snapshot ID, timestamp), each transformation operation applied (with its parameter configuration), the intermediate dataset states, and the final input vector presented to the model. Modern data lineage tools (Apache Atlas, OpenLineage/Marquez, dbt's lineage DAG, Alation, Collibra) capture this at the column level, enabling regulators to trace a single VaR input back through the pipeline to its raw source record. The model registry with challenger-champion model comparison history and split-test support tracks model artifacts, hyperparameters, and version history — valuable for model governance, but the firm already has model version logging. The gap is in data transformation provenance, not model metadata. The feature store with point-in-time correct lookups that can replay historical feature values as of any past calculation date addresses the temporal consistency of features during training and inference (preventing future-data leakage), but does not inherently track the transformation logic that produced those features from raw inputs. The data catalog with column-level business glossary tagging and stewardship assignment workflows provides a searchable inventory of datasets, their business definitions, and ownership — valuable for data discovery and governance, but not a lineage system. Lineage tracks the dynamic flow of data through computations, not just the static descriptions of datasets. Regulatory frameworks requiring demonstrable data lineage in buy-side risk include BCBS 239 (principles for risk data aggregation), SEC Rule 18f-4 (derivatives risk management for funds), and ESMA's AIFMD reporting requirements.