
A buy-side research team wants to build a system that allows analysts to query the firm's proprietary research database — comprising 15 years of internal memos, model outputs, and annotated earnings transcripts — using natural language. The firm's CTO is evaluating whether to use Retrieval-Augmented Generation (RAG) or to fine-tune a foundation model on the internal corpus. The data is updated daily with new research. Which architectural choice is most appropriate, and what is the primary justification?
Select an answer to reveal the explanation.
Short Explanation
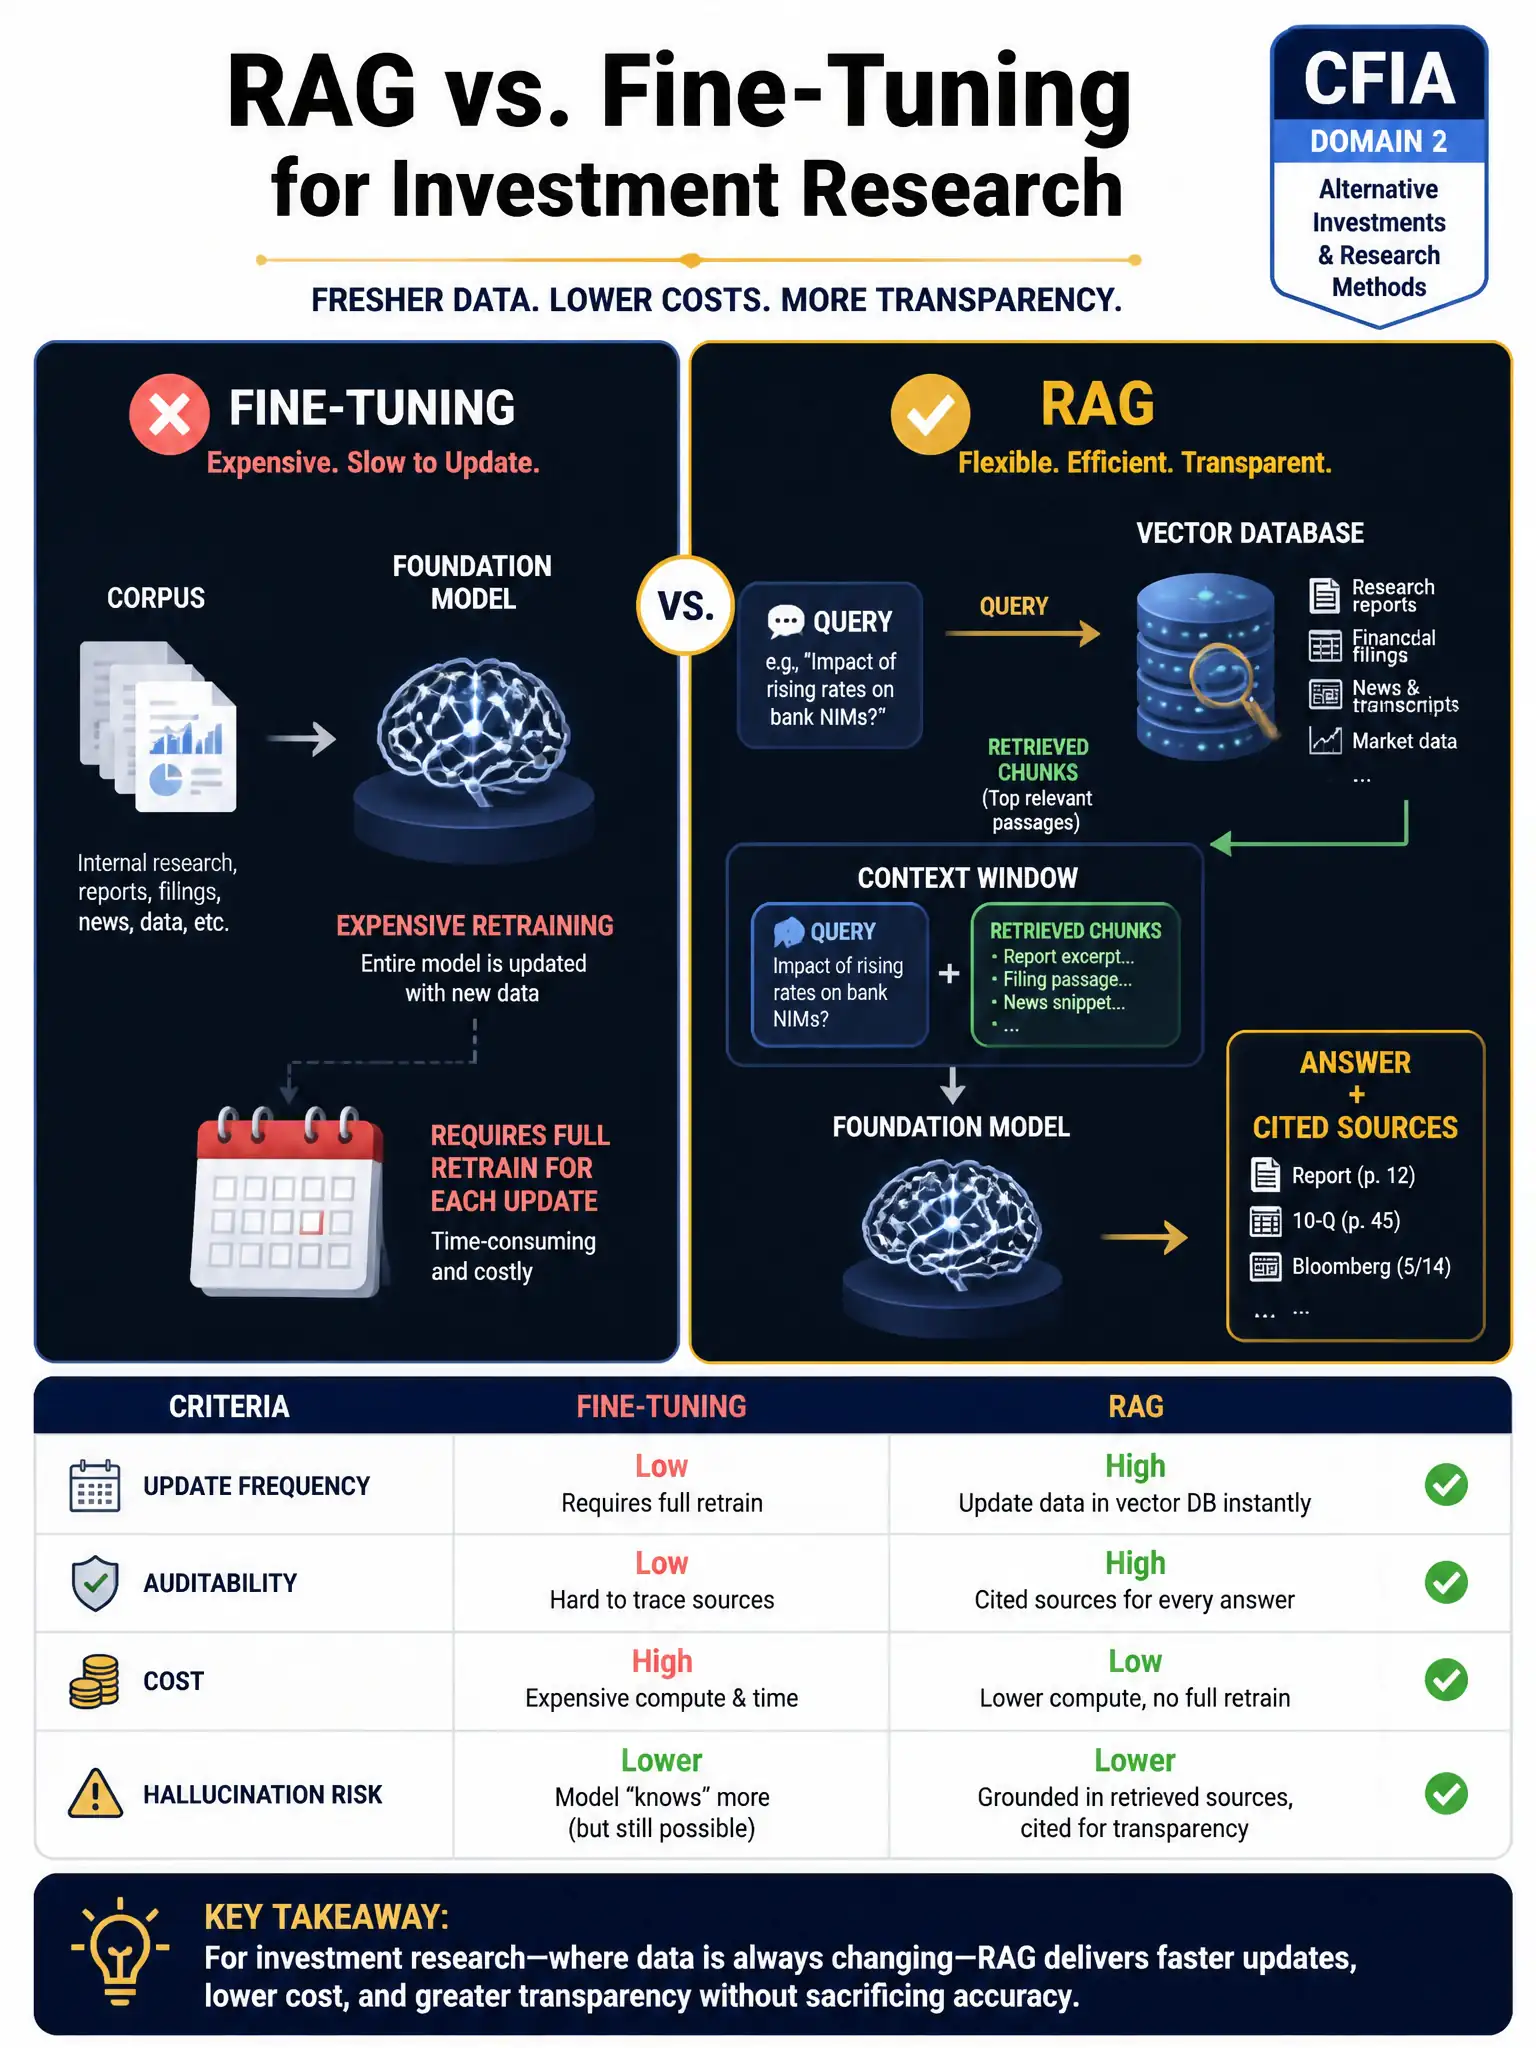
Think of fine-tuning as reprinting the whole book every time a new memo lands, while RAG just adds the memo to a searchable shelf. For a research database that changes daily, you want RAG because it retrieves current documents, cites sources, and avoids constant retraining.
Full Explanation
The choice between RAG and fine-tuning is one of the most consequential architectural decisions in enterprise AI for financial services, and understanding the correct use case for each is essential for an AI architect role.
RAG separates knowledge storage from model inference. A retrieval system, typically a vector database using dense embeddings, identifies the most relevant document chunks for a query, and those chunks are passed as context to the foundation model alongside the user's question. The model then generates an answer grounded in the retrieved content. This architecture has three decisive advantages in the scenario: daily data updates require only re-embedding new documents into the vector store, with no model retraining; outputs are grounded in source documents that can be cited and audited, which is critical for compliance in investment research workflows; and the system can be updated, rolled back, or expanded without touching the foundation model.
Fine-tuning bakes knowledge into the model's weights through additional training on a target corpus. It is appropriate when you want to change the model's behavior or style, such as producing structured output in a specific format, adopting firm-specific terminology, or reasoning in a domain-specific way. It is not appropriate for knowledge injection in a dynamic corpus because it requires periodic retraining as the corpus updates, which is expensive and time-consuming; fine-tuned knowledge can degrade over time relative to new information through catastrophic forgetting; and the model cannot cite specific source documents because the knowledge is distributed across weights rather than retrieved from a specific chunk, which is a compliance failure in regulated research environments.
The fine-tuning answer claiming that embedding proprietary knowledge into weights makes querying faster and cheaper than maintaining a separate vector database is wrong because that embedding is a disadvantage for daily-update use cases, not an advantage. Query latency differences are marginal and not the primary consideration. The fine-tuning answer claiming that foundation models have fixed knowledge cutoffs and cannot access external databases without retraining is factually wrong because foundation models can access external databases through RAG without retraining; the knowledge cutoff is a property of parametric memory, not an inability to process new content supplied via context. The RAG answer claiming that RAG eliminates hallucination entirely by grounding all outputs in retrieved documents is wrong because RAG does not eliminate hallucination entirely. The model can still misinterpret retrieved documents, generate claims not present in the context, or produce plausible-sounding interpolations. RAG substantially reduces hallucination risk relative to pure parametric generation, but practitioners must implement output validation and confidence scoring.