
Timing becomes a point of contention: when should risk identification for a new AI system happen relative to deployment?
Select an answer to reveal the explanation.
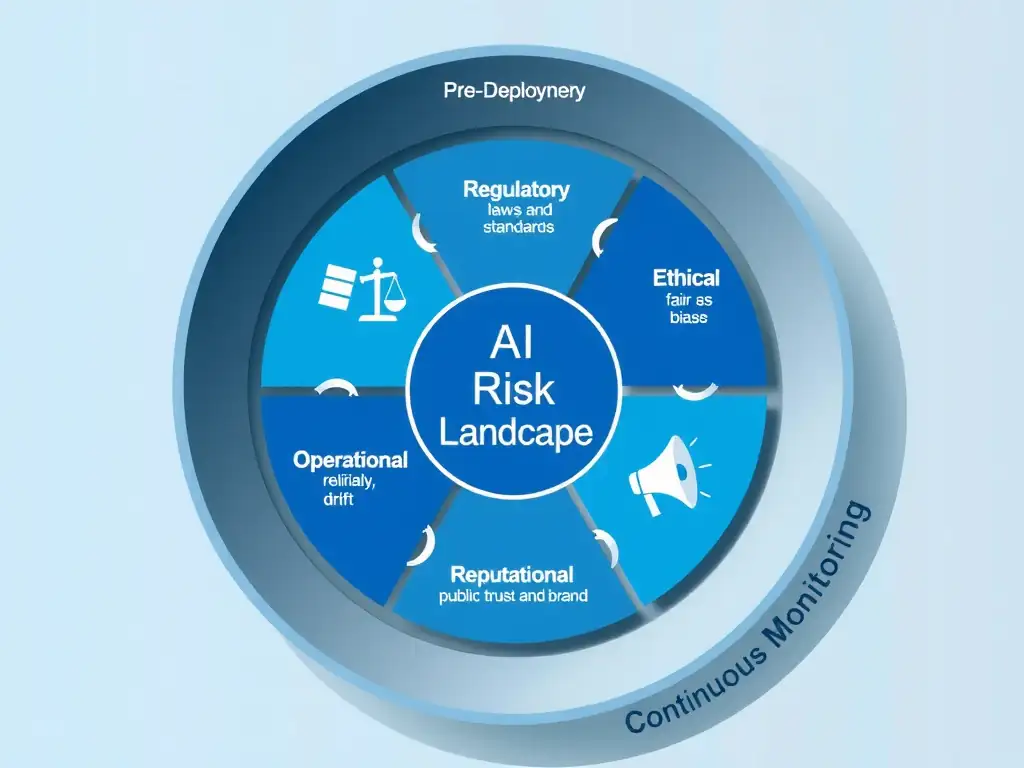
Short Explanation
Do it before deployment so you catch what launching would create. Do it again during deployment, because launching doesn't freeze the world in place.
Full Explanation
Risk identification should happen before deployment as a gating activity, and again during deployment as conditions and usage evolve. Pre-deployment assessment catches risks that would be introduced by launching at all, while ongoing assessment during deployment catches risks that emerge as real usage, data, and context shift over time. The option limiting risk identification to before deployment, claiming post-launch conditions are outside scope, is wrong because usage patterns or drifting inputs can introduce risk that a pre-launch snapshot could not foresee. The option limiting it to during deployment, treating pre-launch risk as theoretical, is wrong because it accepts avoidable harm as the cost of gathering evidence, when pre-launch assessment exists to prevent that. The option limiting it to major version changes is wrong because material risk can emerge between major versions, before the next scheduled review. For the exam, remember risk identification spans both the pre-launch gate and the ongoing deployment period.