
When a developer triggers code generation in the wca4z IDE plugin, where does the actual AI inference occur?
Select an answer to reveal the explanation.
Short Explanation
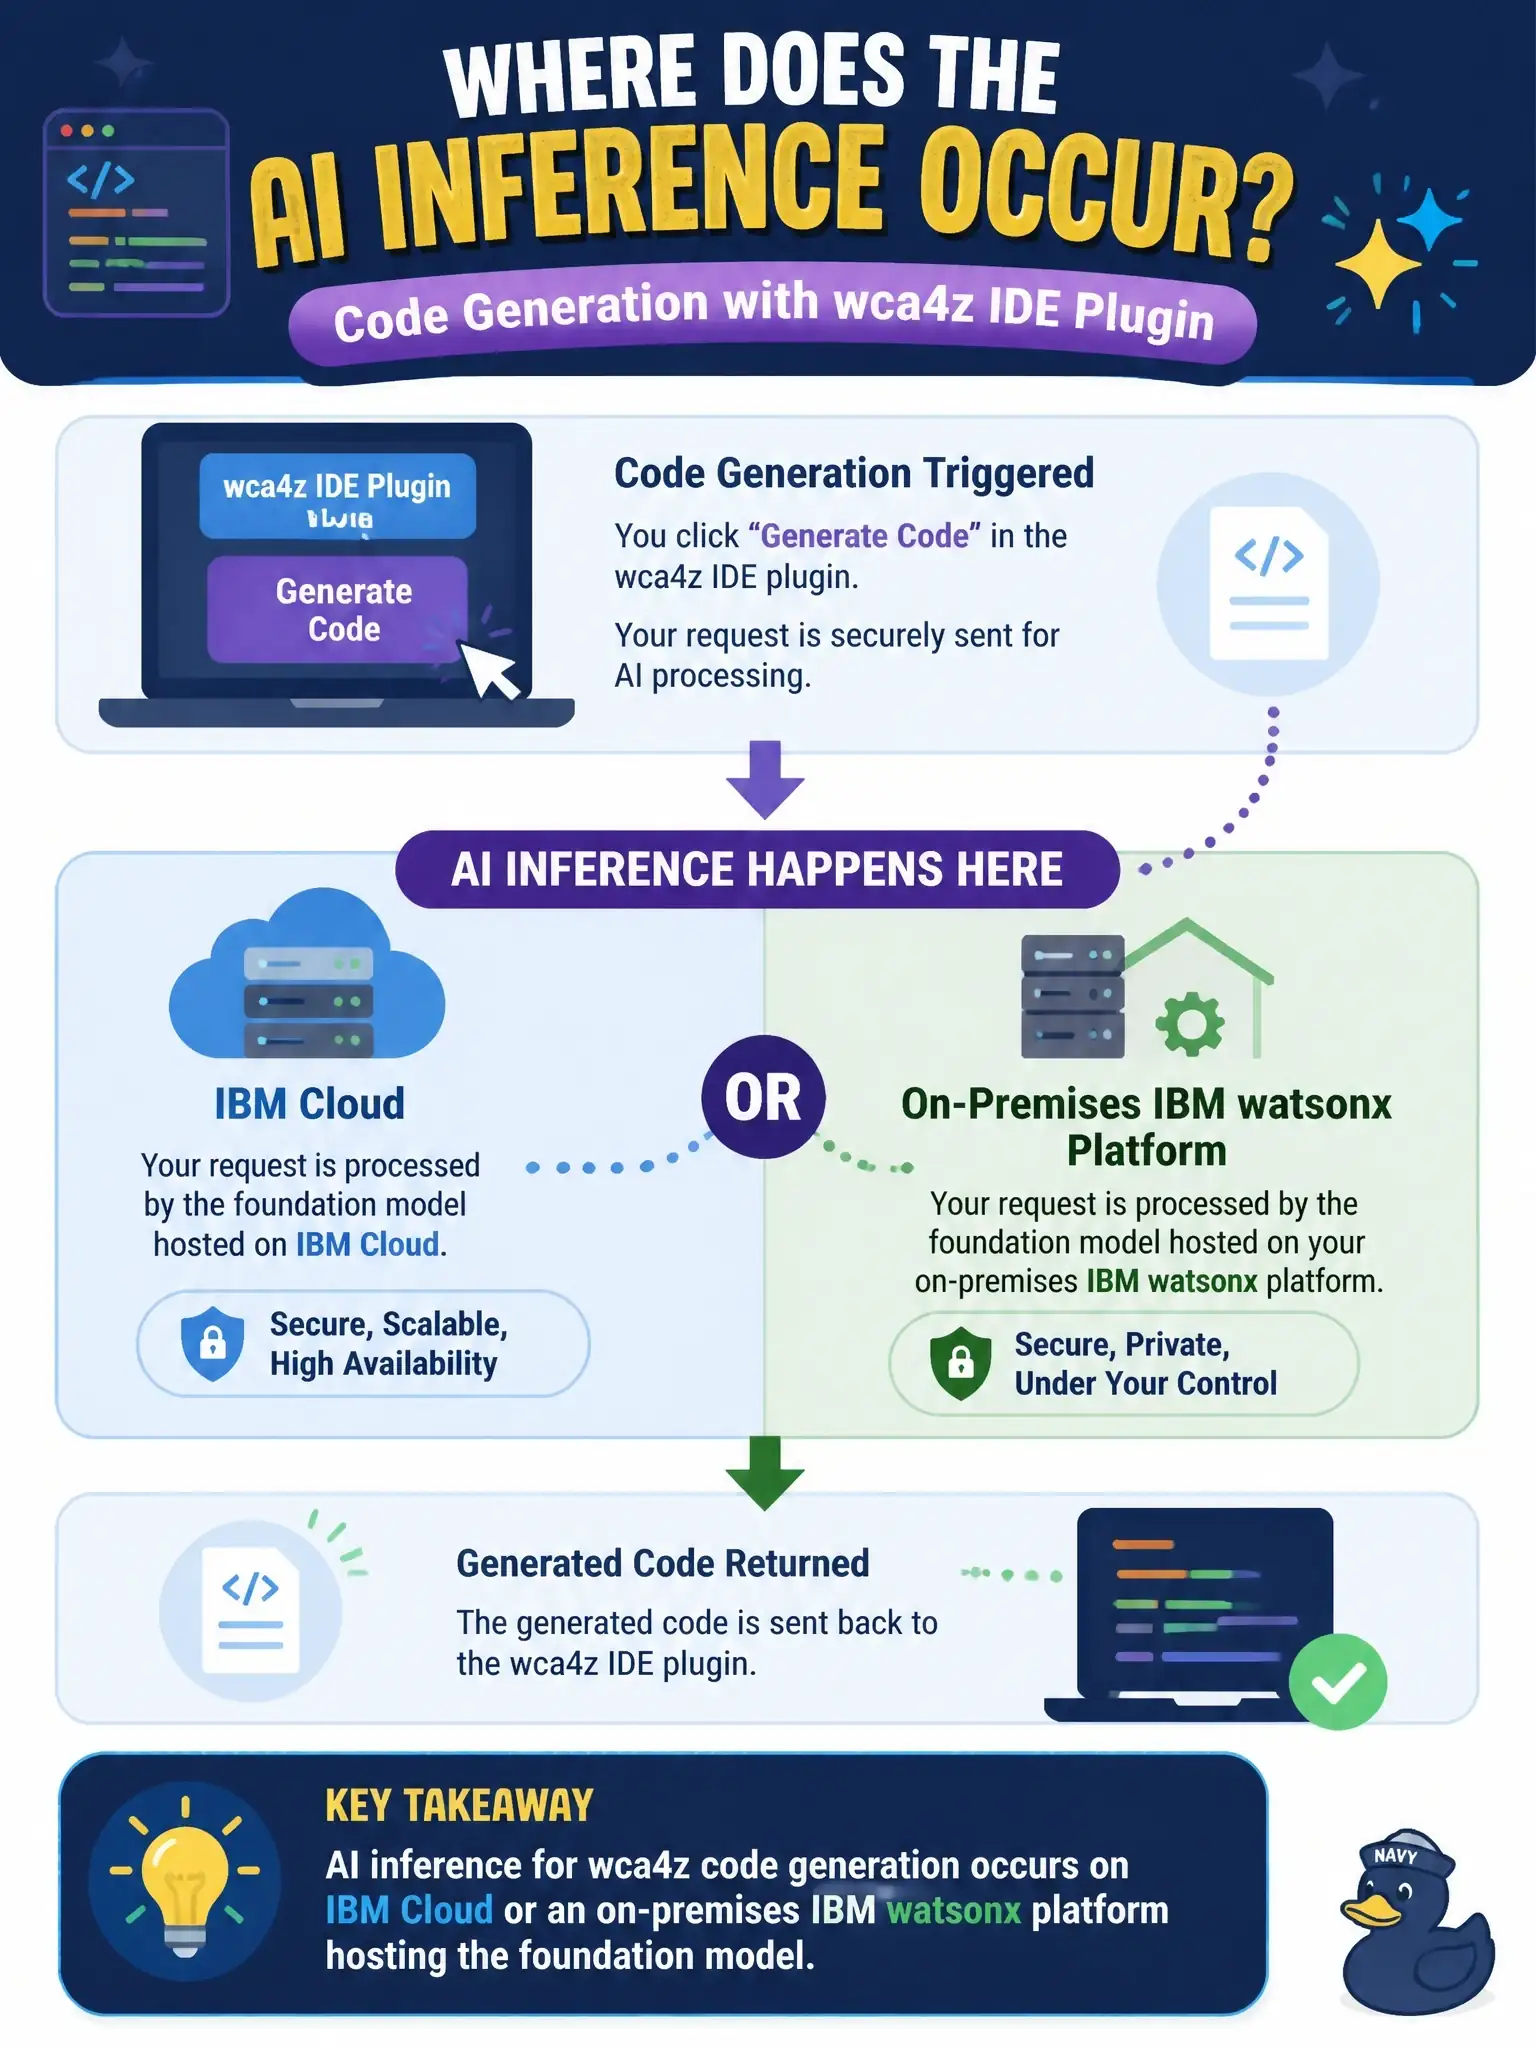
You trigger code generation from the plugin, but the inference runs on IBM Cloud or an on-premises IBM watsonx platform. The service returns generated Java code to your IDE.
Full Explanation
The plugin sends prompts to IBM Cloud/on-prem watsonx, where the foundation model runs inference and returns Java code. Local ONNX, z/OS accelerators, and ADDI COBOL parsing are wrong because they are not the inference endpoint.