
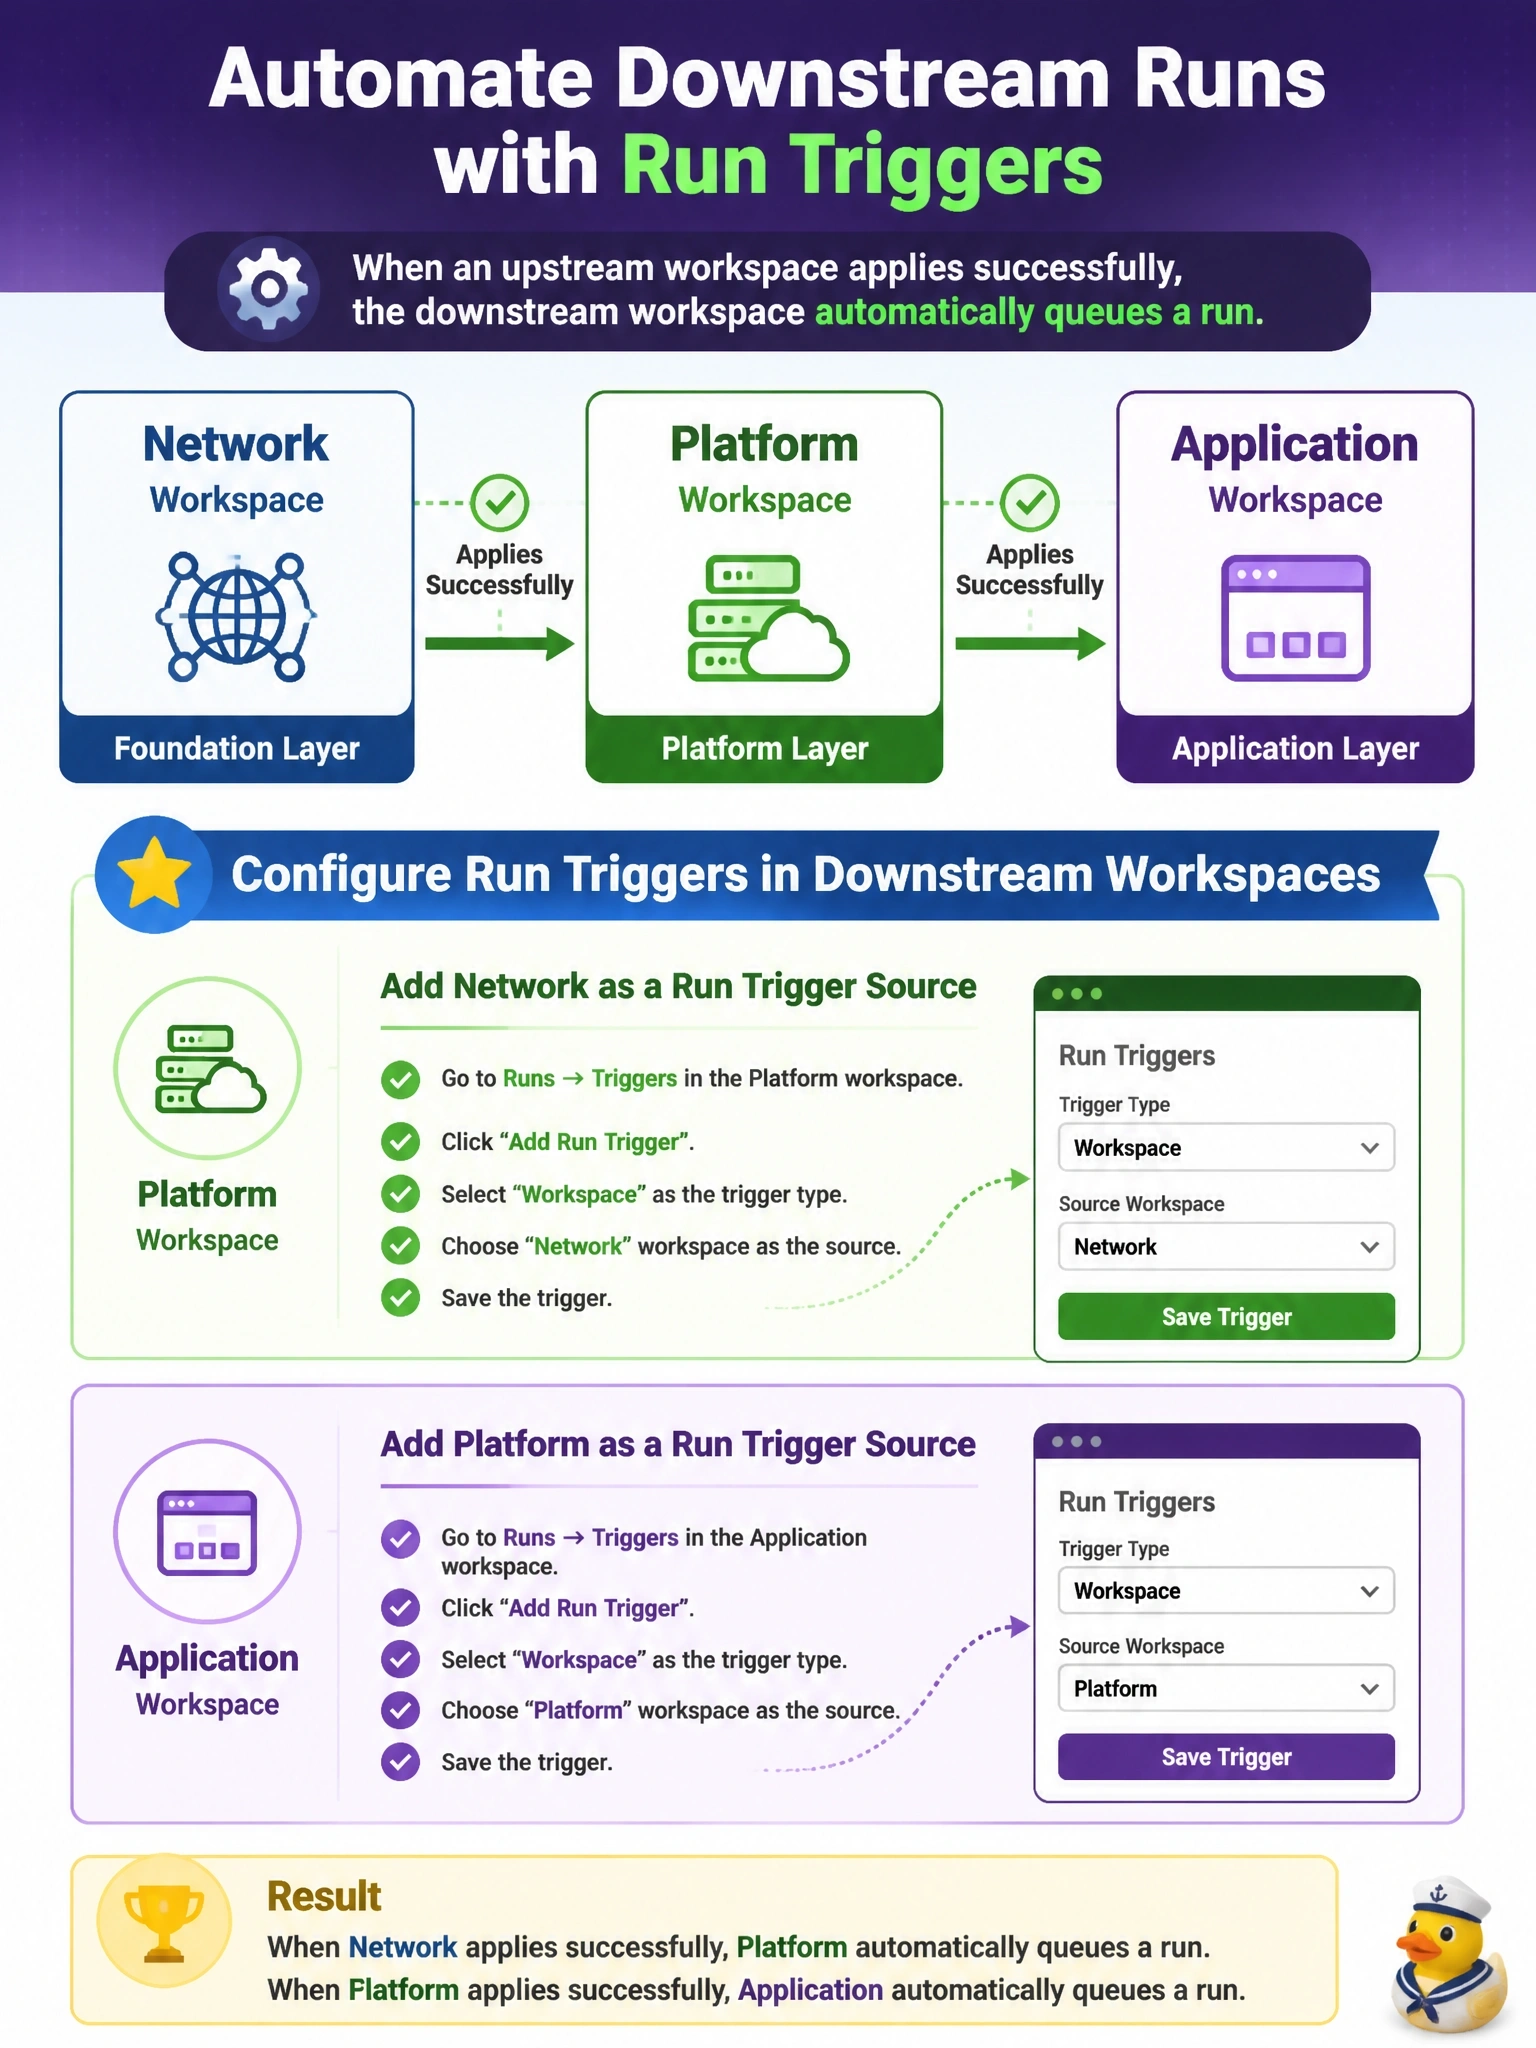
In HCP Terraform, a network workspace feeds a platform workspace, which feeds an application workspace. The team wants each downstream workspace to queue a run automatically after its upstream workspace applies successfully. How should this be configured?
Select an answer to reveal the explanation.
Short Explanation
You set up run triggers from the listening side: each downstream workspace says 'tell me when that one finishes'. Chain them one link at a time and the order takes care of itself. The trap is configuring the trigger on the upstream workspace, which isn't how it works.
Full Explanation
Run triggers connect a workspace to one or more source workspaces in the same organization. They are configured in the downstream workspace's settings, by adding the workspace it depends on as a source, and any run in a source workspace that applies successfully then queues a new run in the downstream workspace. Configuring the platform workspace with network as its source and the application workspace with platform as its source produces the ordered chain: network applies, platform plans, and after platform applies, application plans. Configuring a run trigger requires admin access to the downstream workspace and permission to read runs in the source. Run triggers are not defined from the upstream side as a list of destinations; the source workspace only reports which workspaces it will start runs in. Variable sets share variable values across workspaces but never queue runs. Data sources such as terraform_remote_state or tfe_outputs read upstream outputs during a run but do not cause runs to start; run triggers exist to make that dependency explicit. Exam caveat: runs started by a run trigger do not auto-apply unless the separate Auto-apply run triggers setting is enabled, and each workspace can connect to a limited number of source workspaces. Operational check: apply a harmless change in the network workspace and confirm a run is queued in platform with a link back to the source run.