
A team wants to evaluate the quality of pull request feedback generated by their code review agent. They need signals that can be tracked over time and used to detect regressions in agent quality. A data scientist proposes using only quantitative signals (e.g., number of comments per PR, average comment length). A senior engineer argues that qualitative signals are also necessary. Which evaluation signal design BEST captures both dimensions for ongoing agent quality assessment?
Select an answer to reveal the explanation.
Short Explanation
You can't judge a code review agent by comment count alone; that's like rating a doctor by how many words they write. Use both objective metrics and human feedback, with baselines and thresholds, so you catch quality regressions over time.
Full Explanation
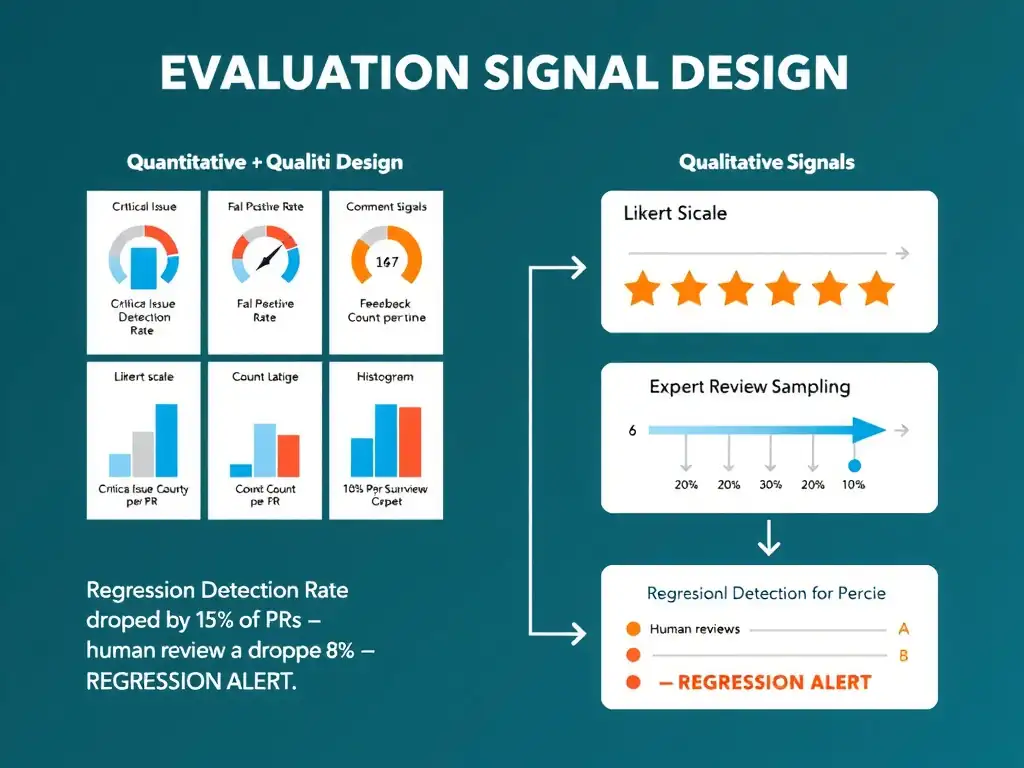
Effective evaluation signal design for agentic systems requires a portfolio of signals, not a single measure. This is because different failure modes are visible to different instruments. The combined design is best because it pairs quantitative signals such as comment count, false positive rate, critical issue detection rate, and time-to-feedback latency with qualitative signals such as structured developer satisfaction surveys rated on a Likert scale and expert review sampling of 5% of outputs, while establishing baseline values and regression thresholds for each. Quantitative signals catch measurable regressions: critical issue detection rate, because if the agent misses SQL injection vulnerabilities this rate drops and can be detected without human review; false positive rate, because too many spurious warnings causes developer fatigue and degrades trust and can be measured against a labeled dataset; and time-to-feedback latency, because if processing time increases from 2 to 15 minutes something changed in the agent's execution and this can be measured automatically. Qualitative signals catch semantic regressions that metrics miss: structured developer surveys, such as asking whether feedback was actionable on a 1-5 Likert scale, provide a human-grounded quality signal that quantitative metrics cannot replicate; even if the agent posts the same number of comments at the same rate, those comments might become less actionable, and only developers can detect this. Expert review sampling, where a senior engineer reviews a 5% random sample of agent outputs, provides a ground-truth quality check against which the automated signals can be calibrated. Baseline values and regression thresholds are critical because without them you know current values but cannot detect change over time. The quantitative-only approach creates metric blindspots: an agent that generates the same comment count but with increasingly vague or irrelevant content will pass all quantitative metrics while degrading in actual value. The qualitative-only approach cannot be tracked programmatically or at scale, because surveying developers on every PR is impractical for large teams. The single composite score generated by a second LLM replaces one uncertain evaluator, the primary agent, with another uncertain evaluator, a judge LLM; this introduces systematic LLM bias and cannot be independently verified. The exam principle: use both quantitative, automatable signals and qualitative, human-grounded signals together.