
An agent is designed to assist a software team continuously over several weeks, tracking which PRs it has reviewed, what architectural decisions it has recorded, and the conversational context from each daily session. Which memory architecture MOST correctly handles these different types of information?
Select an answer to reveal the explanation.
Short Explanation
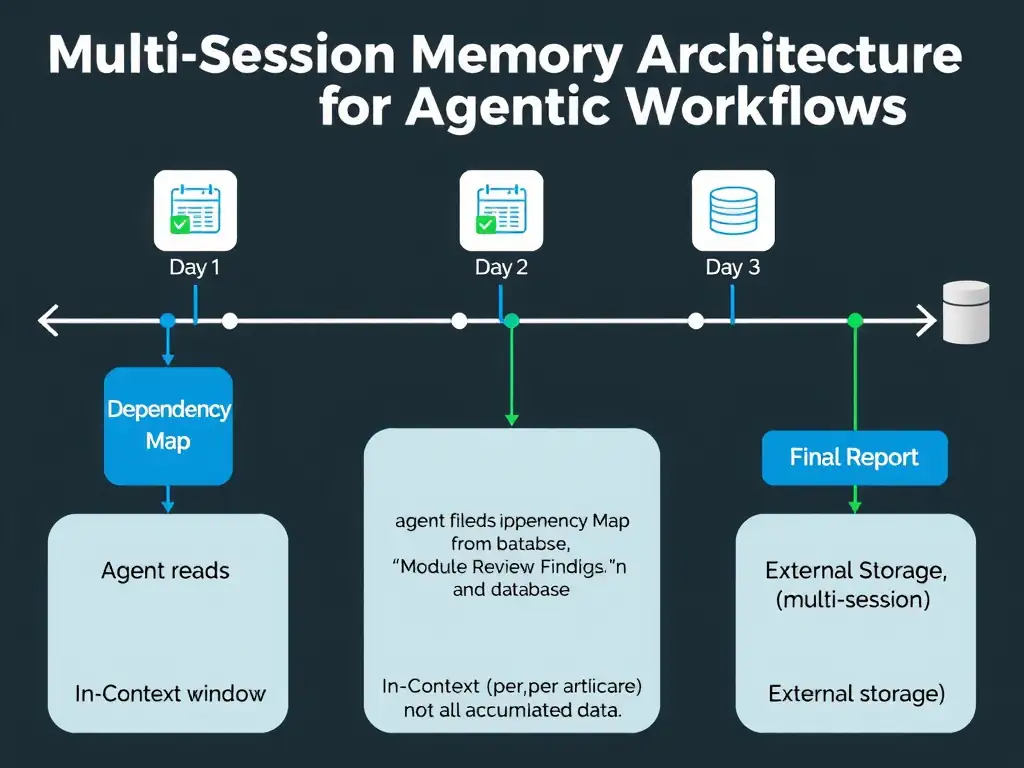
You don't force all memory into one place. Keep current conversational context in-context, put PR review history in an external task-state store, and store architectural decisions in a structured knowledge store with timestamps and rationale.
Full Explanation
Memory architecture for long-running agents requires matching each memory type to the storage mechanism best suited to its access pattern, lifespan, and importance.
The context-window-only approach, cleared weekly, is wrong on multiple fronts. Weeks of PR review history and architectural decisions will overflow any context window. Clearing weekly discards organizational knowledge that should persist indefinitely. Context windows are ephemeral by nature and are lost on any session termination.
The tiered approach is correct because it applies the right tier to each type: conversational context from the current daily session is naturally in-context — it is what the agent is actively using, it has a session scope, and it does not need to persist after the session ends. Injecting the previous session's summary as needed is the standard pattern. PR review history needs structured querying, such as whether a specific PR was reviewed and what conclusion was reached, which requires an external store with indexing — a relational database or structured vector store. Architectural decisions are organizational knowledge with long-term strategic value. They need timestamps, author attribution, rationale, and searchability — characteristics of a knowledge base, not a task queue.
The single flat file in the repository approach creates an ever-growing file that becomes increasingly difficult to query. Git commit history makes PRs for memory updates noisy. Concurrent agent sessions create merge conflicts on the file. This does not scale beyond a few weeks.
The only-external-storage approach, retrieving everything from the database at the start of each session, defeats the purpose of in-context memory for current session context. Loading the entire database into context at session start is expensive and may overflow the context window. More critically, conversational context is built up during the session — it cannot be loaded at the start because it does not exist yet.