
An agent workflow has an escalation path that creates a GitHub Issue and assigns it to the on-call engineer when it encounters a problem it cannot resolve autonomously. After implementing this system, the team discovers that 23% of escalation issues are never acknowledged or closed — the on-call engineer receives no notification because the Issue assignment notification emails are going to spam. The unacknowledged issues accumulate while the agent continues creating new ones. Which design change MOST appropriately implements a dead-letter handler for this escalation pattern?
Select an answer to reveal the explanation.
Short Explanation
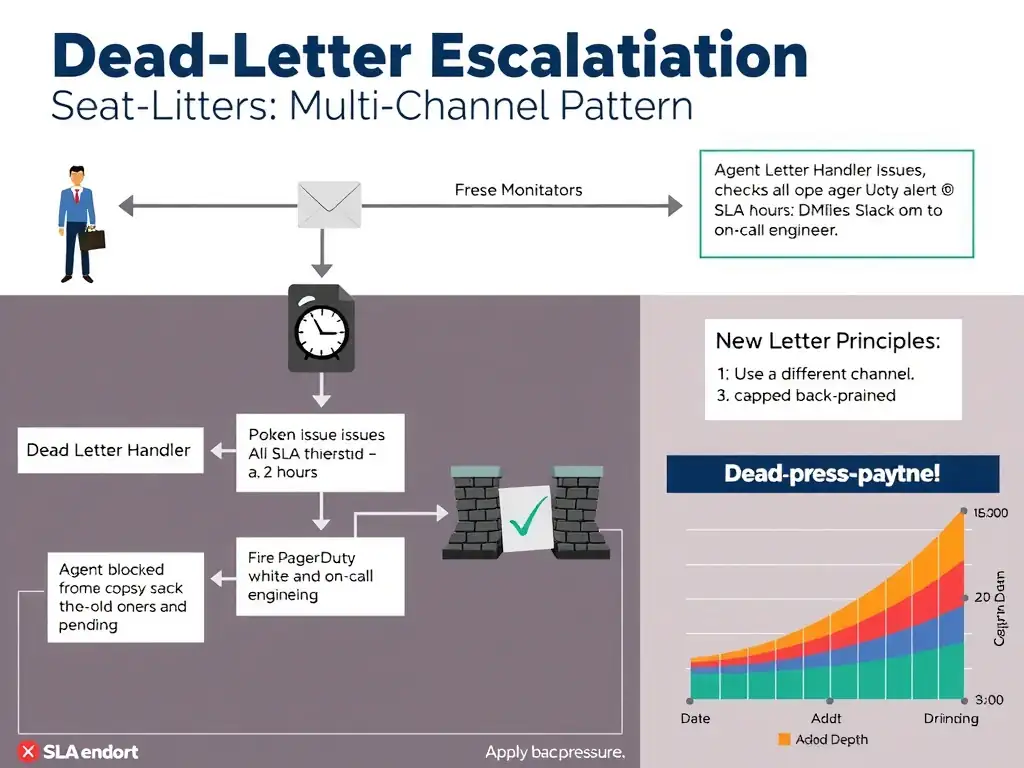
A dead-letter handler shouldn't just shout louder on the same broken channel. You need a watchdog that spots stalled escalations, alerts someone through a different path like Slack or PagerDuty, and stops the agent from piling on new issues until the old ones get handled.
Full Explanation
Dead-letter handling in agent systems addresses the scenario where an escalation path itself becomes unresponsive. The core problems here are two: the primary notification channel is failing silently, and the agent has no feedback that its escalations are going unresolved, so it continues generating more.
The duplicate-email notification approach addresses the symptom of notification delivery but uses the same channel that is already failing, email to spam. Adding a second email to a different address might work temporarily but does not address the architectural weakness: relying on a single notification channel type.
The SLA-based monitoring workflow with secondary-channel escalation and back-pressure is correct for three reasons. It implements SLA-based monitoring on the escalation queue itself, treating unresolved issues as a metric to be tracked, not just created. It escalates through a secondary, higher-urgency channel, such as a Slack DM or PagerDuty alert, when the primary channel, a GitHub Issue plus email, fails to produce acknowledgment. That is the key dead-letter pattern: when message processing fails in one channel, route to another channel. It also adds back-pressure by preventing new escalations from being created while prior ones are unresolved, which prevents the escalation queue from becoming a graveyard that engineers stop paying attention to because it's overwhelming.
The 24-hour comment ping approach adds noise to the same failing channel. If email notifications from Issue assignments go to spam, comments on those Issues will likely trigger the same email type and also go to spam.
The GitHub spam-setting configuration approach is an operational workaround, not an architectural solution. It requires someone to fix the problem, but provides no automated handling for future cases where the primary channel fails for different reasons.