
A startup wants to introduce its first agent into the SDLC but has limited engineering bandwidth to manage agent infrastructure. They are choosing between: (A) an agent that monitors issues and automatically creates implementation-ready GitHub Issues from support tickets, (B) an agent that autonomously writes, tests, and deploys hotfixes to production with no human review, or (C) an agent that generates draft PR descriptions from commit diffs. Which option provides the BEST balance of value and appropriate scope for a first agent deployment?
Select an answer to reveal the explanation.
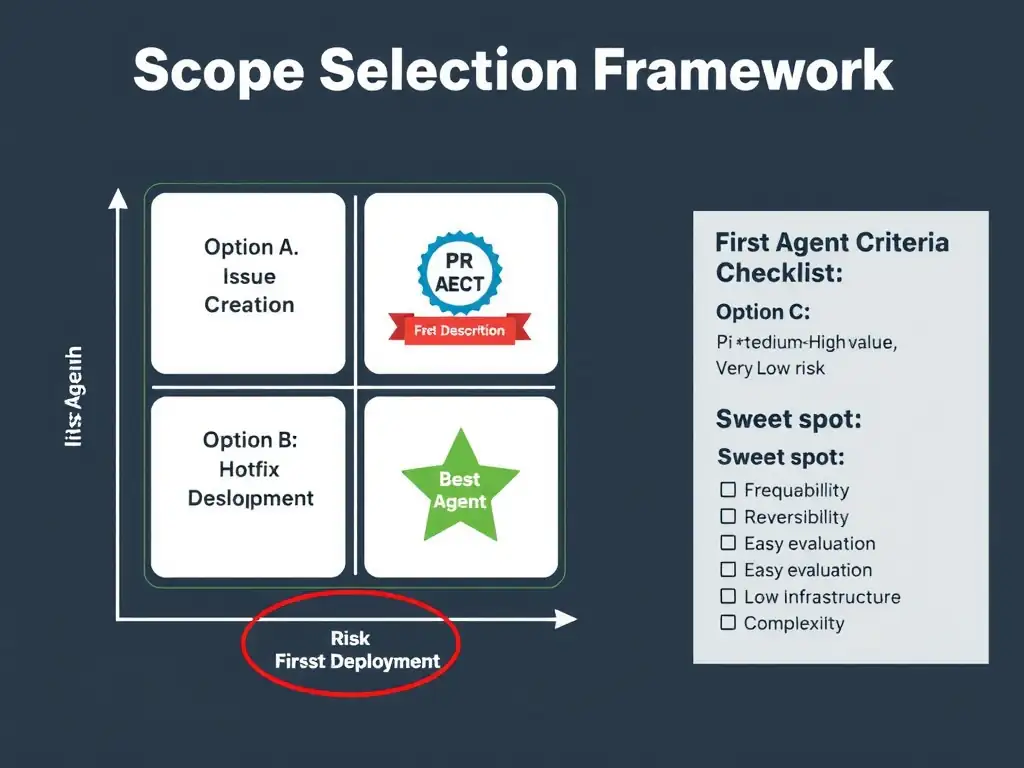
Short Explanation
Your first agent is like a new hire on day one — you don't give them the keys to production. Generating draft pull request descriptions from commit diffs is the perfect starter role: it happens dozens of times per day, saves real time, produces output developers can instantly verify, and the cost of a bad output is a developer editing a description. It builds confidence without exposure, while autonomous hotfix deployment would be the exact wrong first step.
Full Explanation
First-agent deployments should be optimized for learning and trust-building, not maximum theoretical value. The team needs to understand how to monitor, tune, escalate, and maintain agents before the stakes are high.
The choice that generates draft pull request descriptions from commit diffs is correct. It is ideal for a first agent deployment for four reasons. It is high frequency, because developers write pull request descriptions for every pull request, so the agent activates constantly and provides many data points for evaluation. It is low risk, because a poor pull request description is annoying but causes no system damage, and humans naturally review and edit it. It is easy to evaluate, because humans read the description alongside the diff and immediately know if it is accurate. It builds confidence, because the team develops operational intuition about monitoring, prompts, and agent behavior in a safe environment that scales to more complex deployments.
The choice that monitors issues and automatically creates implementation-ready GitHub Issues from support tickets has genuine value, but it involves interpreting ambiguous support language, making prioritization judgments, and potentially misrepresenting customer issues as work items, all judgment-heavy activities. It also touches the planning process, which can create downstream misalignment if the agent misunderstands ticket intent. The claim that this creates structured work items that improve planning efficiency without touching code is therefore not the best first-agent balance.
The choice that autonomously writes, tests, and deploys hotfixes to production with no human review may promise high business value by minimizing production downtime, but it is dangerous as a first agent for any team. Hotfixes touch production, are time-pressured, and require deep contextual understanding of why something broke. An immature agent operating autonomously in this context with no human review is a production incident waiting to happen. This violates every principle of graduated autonomy.
The claim that creating issues from tickets automates the most intellectually demanding part of software development is also wrong. Issue creation from tickets is not the most intellectually demanding part of software development. It is medium-complexity judgment work that is harder to automate reliably than structural transformation tasks like description generation.