
A team starts with two agents and observes them effectively using structured logs per agent. They then scale to 20 agents across five repositories. Which observability design change is MOST critical to maintain diagnostic capability at 20-agent scale?
Select an answer to reveal the explanation.
Short Explanation
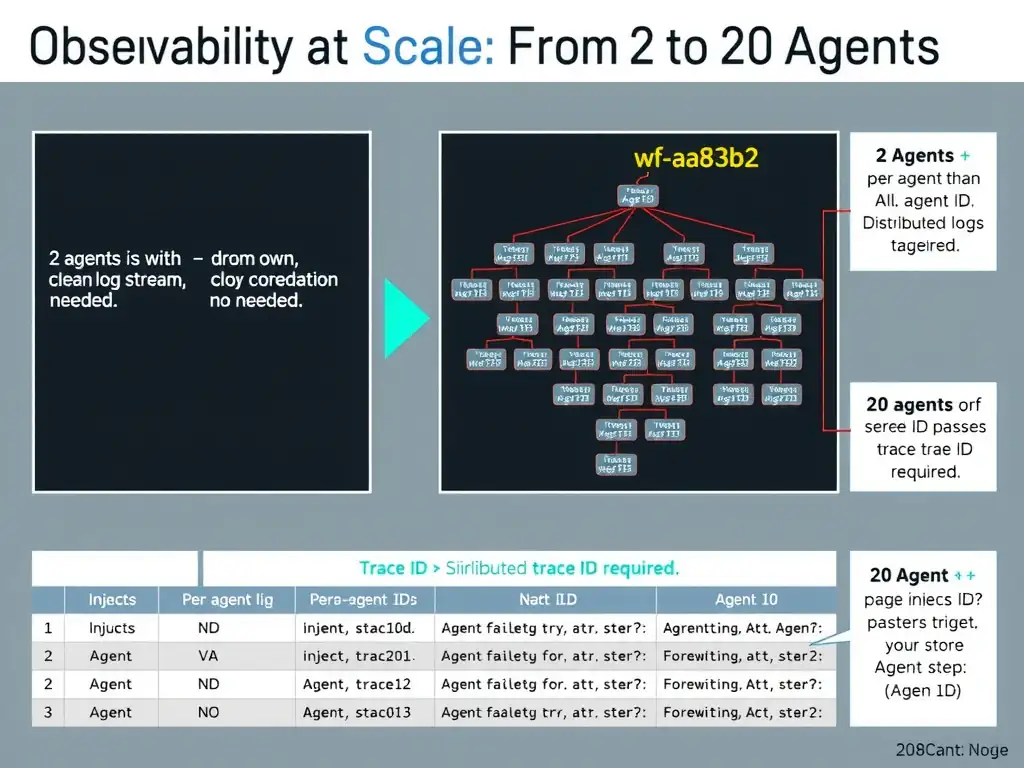
At two agents, structured logs are easy to follow. At 20 agents across five repos, you need a distributed trace ID that propagates across all agent invocations in a workflow so you can correlate events from trigger through final output even when agents run concurrently. Without that shared ID, you're stitching together disconnected logs and losing the causal chain.
Full Explanation
Observability design must scale with the complexity of agent coordination, not just the count of individual agents. The shift from two to 20 agents introduces concurrency, multi-repo spans, and cascading dependencies that make per-agent logs insufficient.
The longer log retention change addresses storage duration, not diagnostic capability. You can retain logs for a year and still be unable to correlate a failure in Agent 14 with the upstream context provided by Agent 3 if those logs have no shared identifier.
The distributed trace ID change is correct. A distributed trace ID — sometimes called a workflow ID or correlation ID — is injected at the point where a workflow begins, such as a GitHub event trigger, and propagated to every agent invocation, tool call, and sub-task within that workflow. This enables engineers to filter all observability systems, including logs, metrics, and traces, by a single ID and reconstruct the complete causal chain: which agent received what input, what it decided, what tools it called, what it produced, and how that output flowed to the next agent. Without this, debugging a failure at Agent 17 in a 20-agent chain requires manually correlating timestamps across 17 separate log streams, which is an exponentially hard problem.
The dedicated runner change prevents log interleaving within a single runner but does not address cross-agent correlation. You would still have 20 clean but disconnected log streams.
The per-agent dashboard change improves individual agent visibility but creates the inverse problem: it makes it easy to see each agent in isolation but impossible to see the cross-agent workflow as a whole. When a downstream failure needs to be traced to an upstream agent, siloed dashboards actively hinder diagnosis.