
A code-refactoring agent loads repository state at the start of a long task. After 45 minutes of operation, the agent continues making changes based on its initial snapshot, but 12 other PRs have been merged in the meantime, creating conflicts. Which technique best prevents this context drift?
Select an answer to reveal the explanation.
Short Explanation
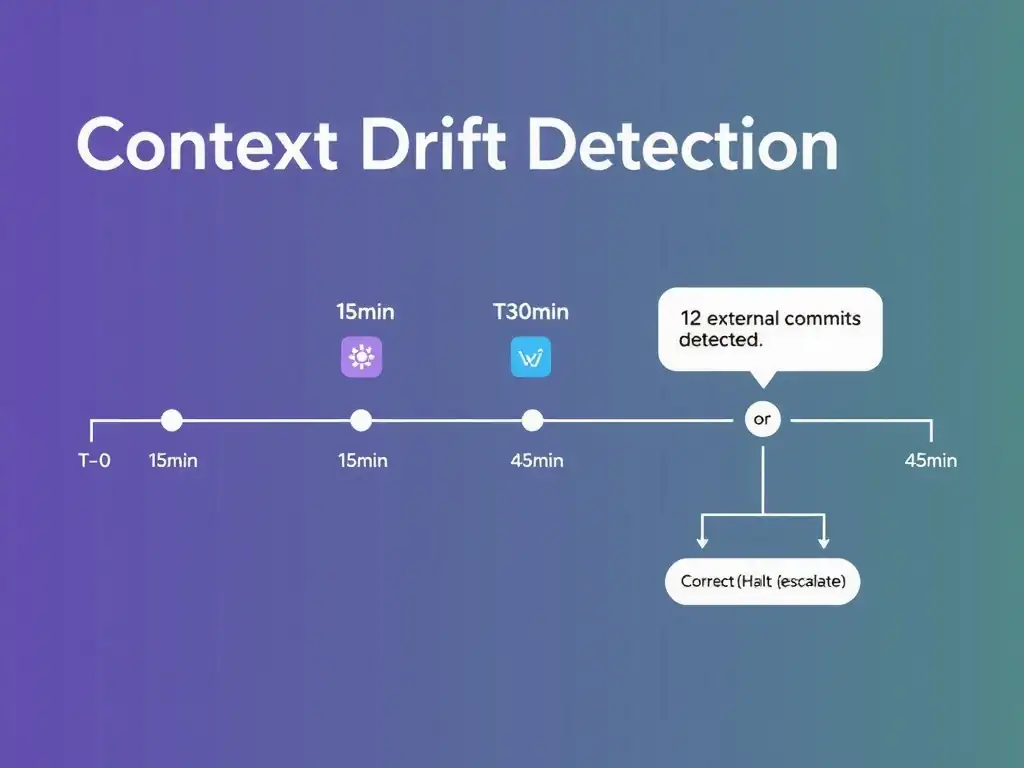
You can’t let a long-running agent trust a stale snapshot forever. You need periodic state validation that re-reads critical metadata, compares it to the working snapshot, and corrects or halts when divergence shows up. On the exam, that’s the answer: detect drift and respond, don’t just hope the repo stayed still.
Full Explanation
Context drift occurs when an agent operates on a stale snapshot of external state while the real-world state continues to change. For a long-running agent, this is especially dangerous because the gap between perceived and actual state grows over time. The best technique is to implement periodic state validation steps where the agent re-reads critical repository metadata, such as the current commit hash, branch state, and file modification times, and compares it to its working snapshot. If divergence exceeds a threshold, the agent can either self-correct by rebasing its work or halt and escalate for human review.
The approach that tells the agent to complete its task as quickly as possible to minimize the time window for external changes is incorrect because speed alone cannot guarantee correctness — in a busy repository, 12 PRs can merge in minutes. Rushing also increases error risk. The root cause is the lack of drift detection, not execution speed.
The approach that implements periodic repository state refresh checkpoints that compare the current commit pointer to the agent’s cached snapshot and halt if drift exceeds a threshold describes a similar concept but frames it as halt-only behavior, missing the correction capability. The periodic state validation approach is preferred because it explicitly includes both correction and halting as responses, making it the more complete and accurate answer.
The approach that configures the agent to work only on a dedicated branch isolated from the main branch, and rebase against main before submitting changes, is partially correct practice because isolated branches are good hygiene, but it does not address drift detection itself. An isolated branch can still drift from its base while the agent works, and rebasing at the end is a single point of failure — if the agent has made 100 changes based on stale state, late detection means much more rework than periodic validation would have required.
Exam caveat: long-running agents must periodically validate that their cached state still matches reality, and either self-correct or halt when it doesn’t.