
An orchestrator agent calls an MCP tool to deploy a configuration change to a staging environment. The tool call exceeds its timeout threshold and returns a timeout error — but the agent cannot determine whether the deployment actually completed before the timeout occurred. What is the most appropriate error-handling strategy?
Select an answer to reveal the explanation.
Short Explanation
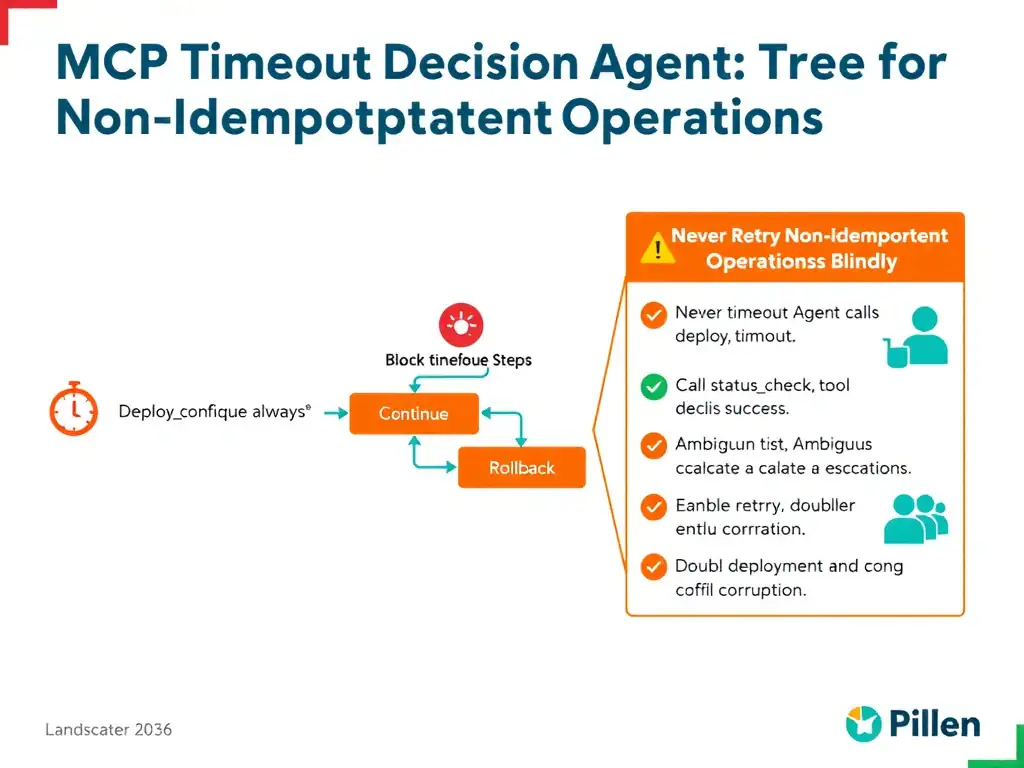
Timeout on a non-idempotent operation is like mailing a check without getting a delivery receipt — retrying blindly means you might pay twice. Stop dependent steps, check the actual state, then proceed, roll back, or escalate if it's still ambiguous. Humans need to be in the loop on non-recoverable uncertainty, not just on failure.
Full Explanation
Deployment operations are typically non-idempotent — running one twice may create duplicate infrastructure, double-apply configuration, or cause partial state corruption. When an MCP tool call times out and the success/failure state is unknown, the agent cannot safely retry without risk. The strategy of immediately retrying the deployment MCP tool call up to three times with exponential backoff, treating the timeout as a transient failure, is wrong. Blind retries with exponential backoff are appropriate for idempotent operations where running the same call multiple times produces the same result safely. Deployment operations are often not idempotent. Retrying without first checking deployment state could result in duplicate deployments, conflicting configuration, or partially applied changes on top of partially applied changes. The strategy of marking the pipeline as failed and waiting for a human operator to manually verify the deployment state before any further action is wrong. While it is correct to halt and not proceed, simply marking the pipeline as failed and waiting passively is insufficient. The agent should actively attempt to determine the deployment state using available status-check tooling before purely handing off to a human. Passive waiting wastes time when automated state verification is possible. The strategy of logging the timeout event, halting further pipeline steps that depend on this deployment, and invoking a status-check tool to determine the actual deployment state before deciding to retry or rollback is wrong. It is a strong partial answer, but it stops at checking state and deciding to retry or rollback — it omits the critical escalation step when state remains ambiguous after the status check. Some deployments may show inconclusive status, for example in progress indefinitely, requiring human judgment. An agent must know its own limits and escalate appropriately. The correct strategy is to block all downstream pipeline steps that depend on this deployment, invoke a status-check tool to determine actual deployment state, then proceed if confirmed success, roll back if confirmed failure, or escalate to a human if state remains ambiguous. This combines automated recovery where possible with appropriate human escalation for non-recoverable uncertainty.