
An agent consistently passes all automated test assertions — code compiles, unit tests pass, and no linting errors appear — but a post-deploy review team reports that the agent's pull requests are confusing, poorly documented, and violate team conventions. What is the most likely root cause of this discrepancy?
Select an answer to reveal the explanation.
Short Explanation
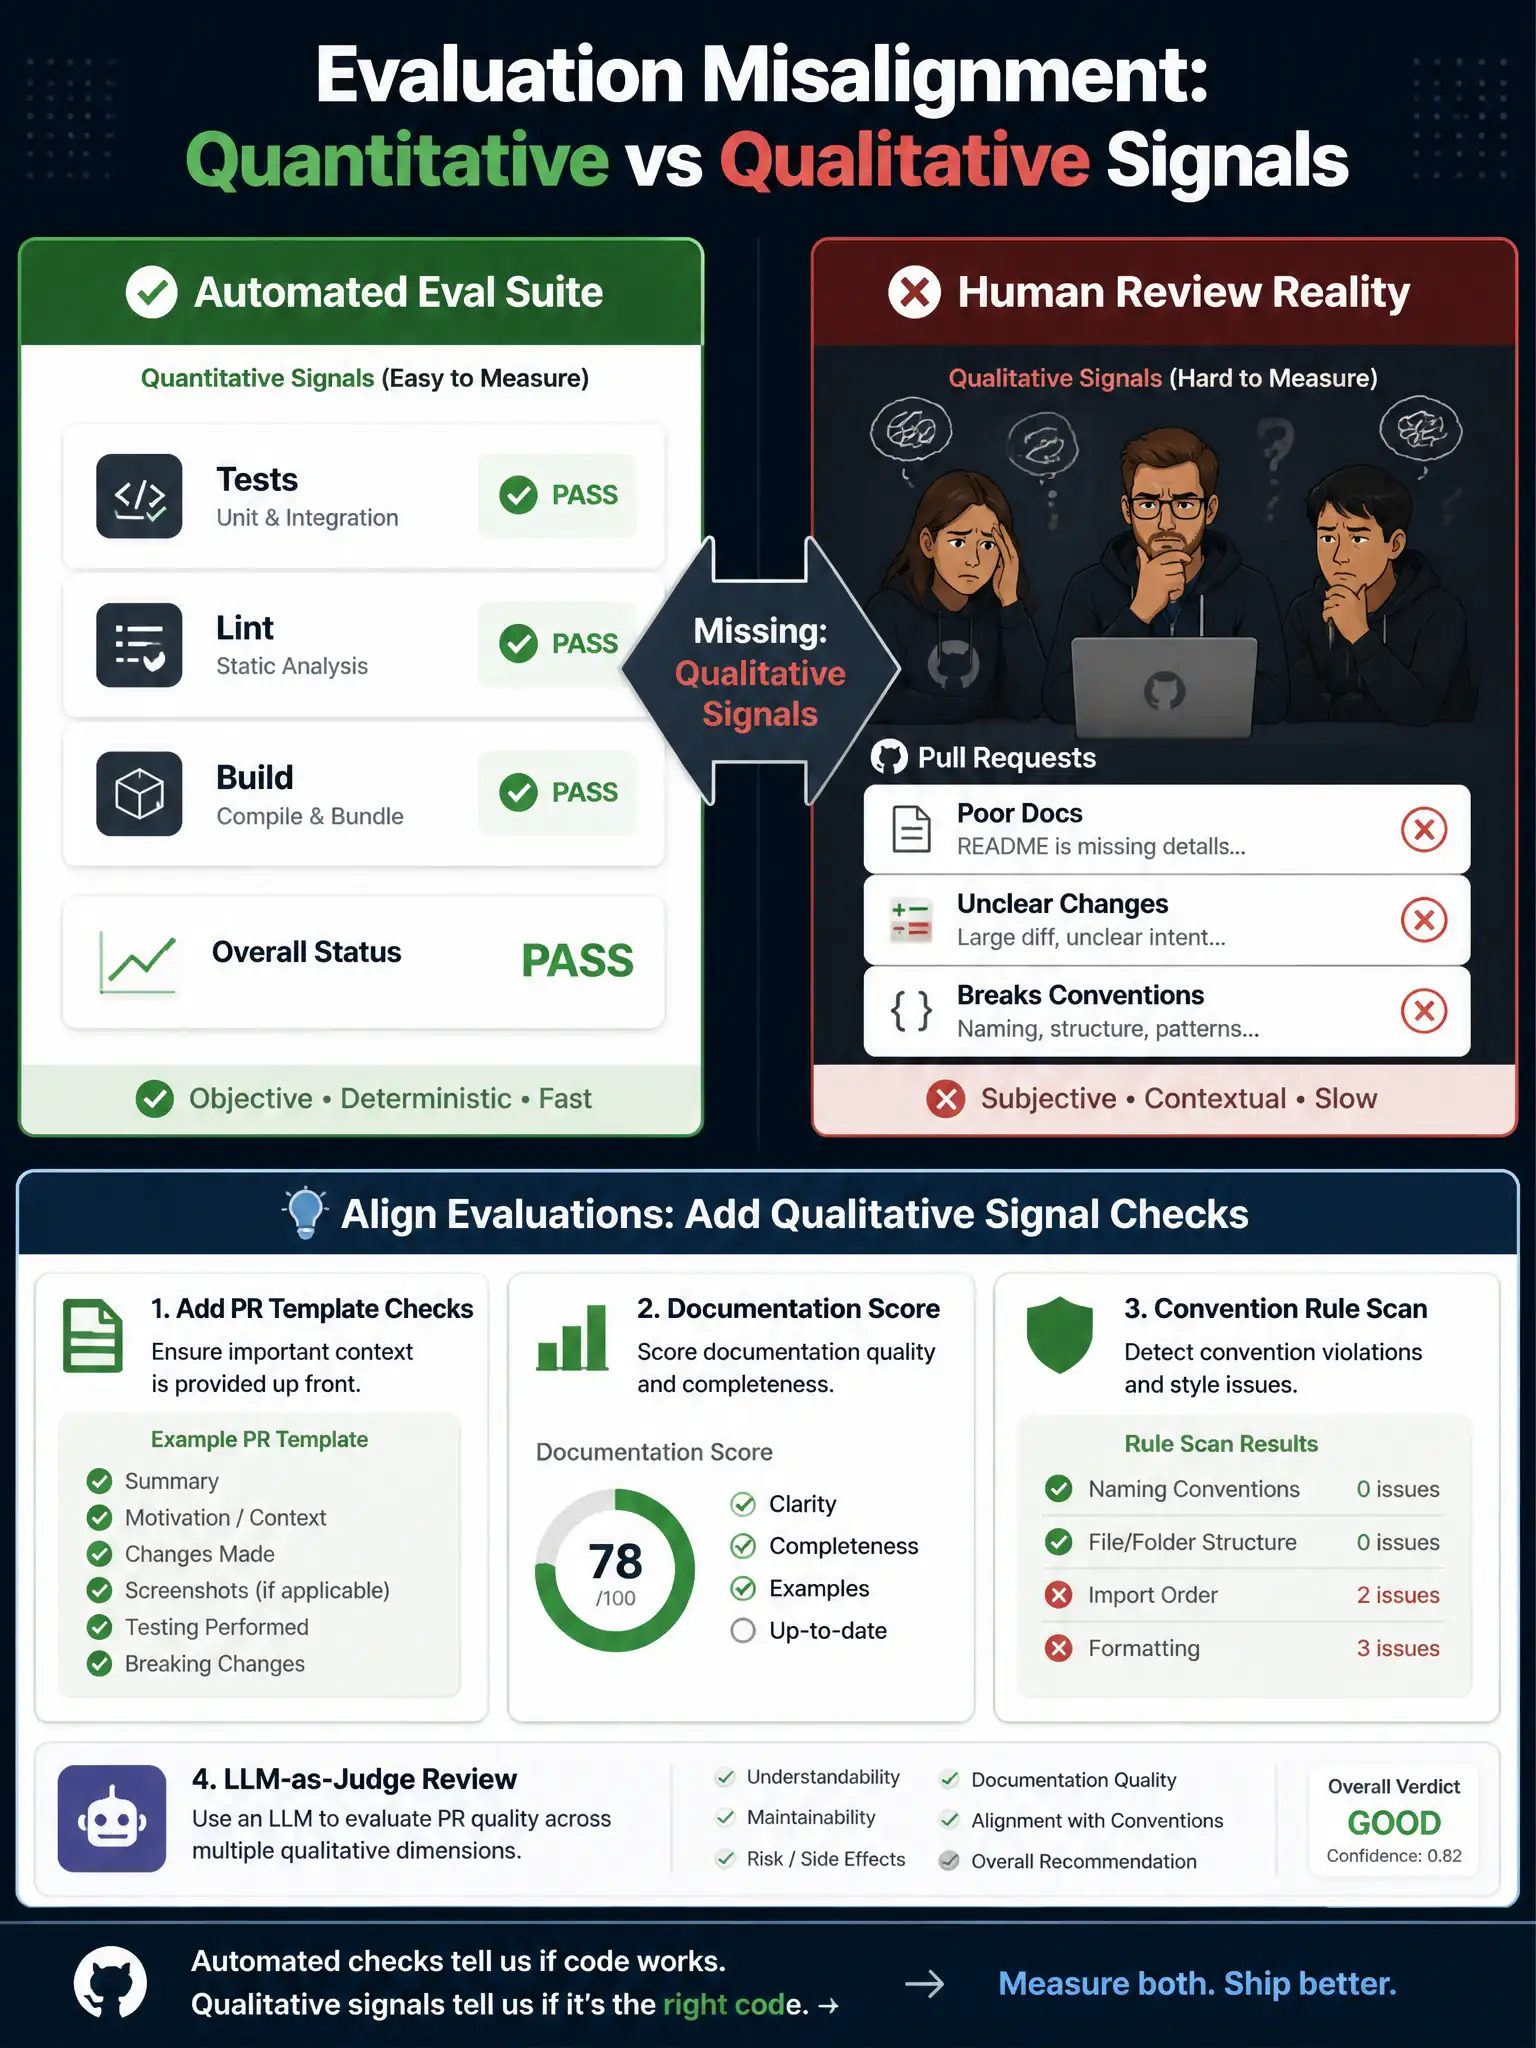
You passed the automated checks because that’s all they measure. If your eval suite doesn’t score readability, docs, and conventions, the agent won’t care about them. Fix the eval, not the agent.
Full Explanation
This question tests your ability to identify evaluation misalignment — a situation where the agent satisfies its formal evaluation criteria but fails to meet the actual intent of the task.
The most likely root cause is the explanation that the evaluation suite is aligned only with quantitative signals and does not capture qualitative success criteria such as readability and convention adherence. Automated evaluation suites excel at quantitative signals: does the code compile? Do tests pass? Are there linting violations? These are binary, easily measurable outcomes. However, pull request quality involves qualitative dimensions — clarity of commit messages, adequacy of inline documentation, adherence to team conventions like naming patterns or PR templates — that require rubrics, human review integration, or LLM-as-judge evaluation to capture. When these qualitative signals are absent from the evaluation pipeline, the agent has no feedback mechanism to improve on them.
The explanation that the agent lacks sufficient compute resources during CI execution, causing it to skip documentation steps, is incorrect. Compute resource constraints during CI would produce timeout errors or incomplete builds — observable failure signals — not consistently passing tests paired with qualitative deficiencies.
The explanation that the automated tests are flawed and should be replaced with a manual review process for all agent outputs is incorrect and overly broad. Replacing all automated testing with manual review eliminates the efficiency benefits of evaluation automation. The fix is to augment the automated suite with qualitative signals, not abandon automation entirely.
The explanation that the agent's model needs to be retrained with higher-quality training data before qualitative improvements are possible is incorrect. Model retraining is an expensive, high-effort intervention and is not the appropriate first response to an evaluation design gap. Before concluding the model itself is deficient, you must first ensure the evaluation suite actually captures the desired behavior. This is a fundamental principle of evaluation-driven development: fix the eval before blaming the model.
The remediation here is to add qualitative evaluation signals — PR template adherence checks, documentation completeness scoring, convention rule scans — to the automated suite, and potentially integrate an LLM-as-judge step that reviews outputs for readability and team alignment.