
An agent that processes multi-step code review tasks is failing to resume correctly after an interruption — every time it restarts, it starts the entire review from the beginning instead of picking up where it left off. Which root cause is most likely responsible?
Select an answer to reveal the explanation.
Short Explanation
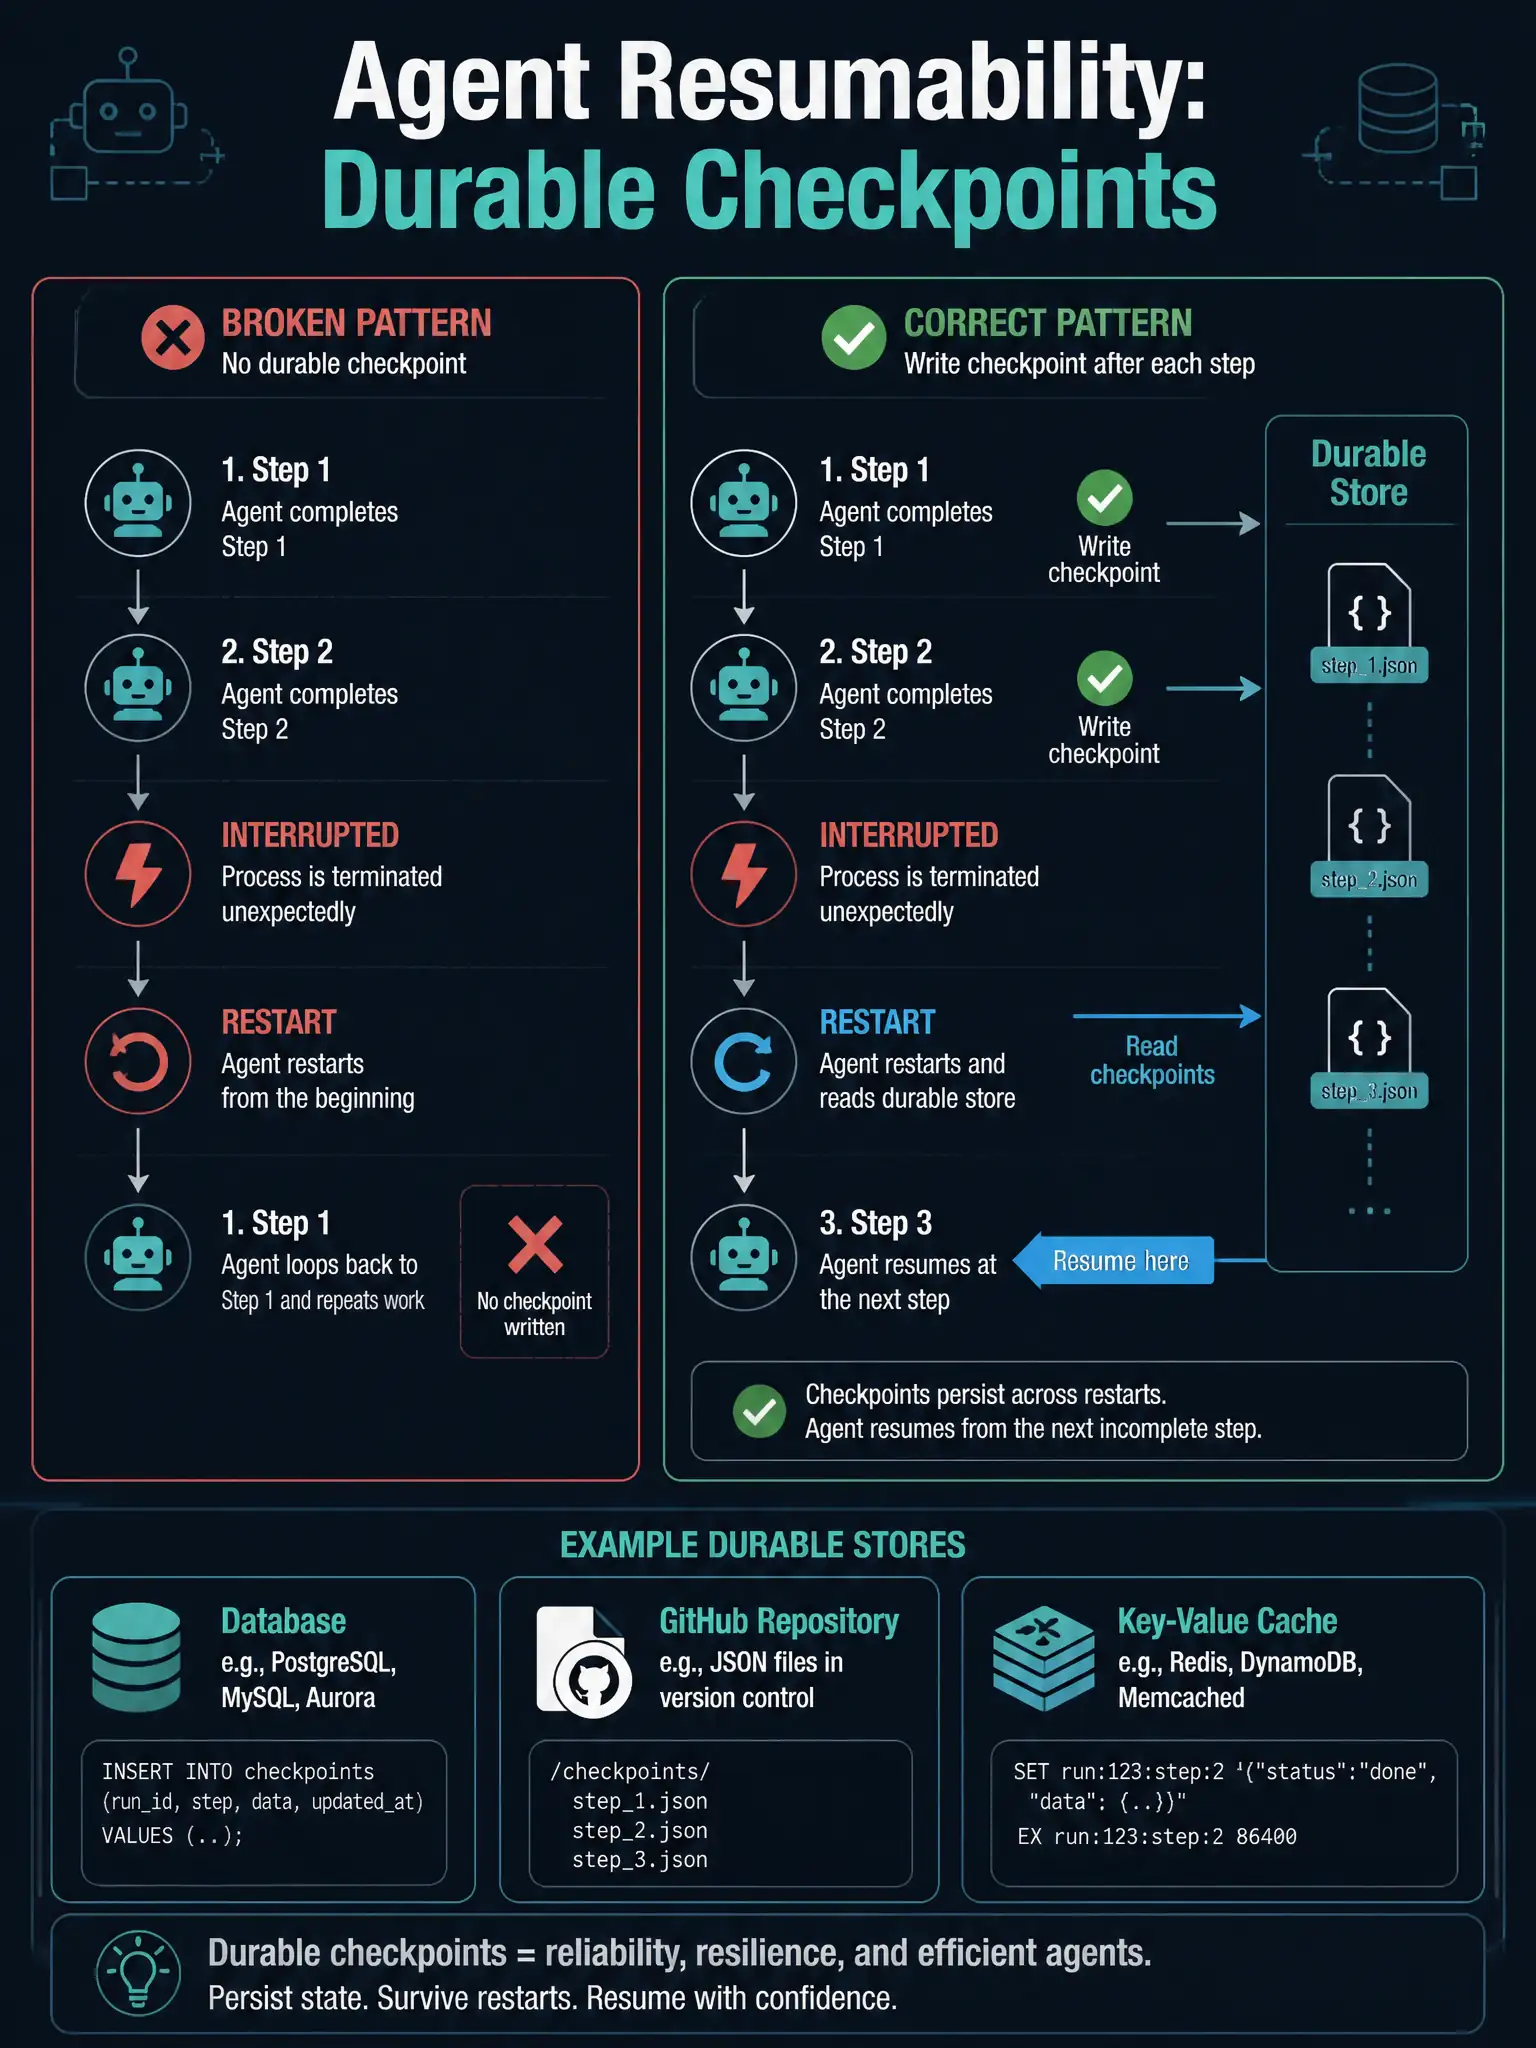
Think of durable checkpoints like game save files — without them, you restart the whole level every time you die. If your agent starts the entire review from the beginning after restarting, it's almost always missing step-level persistence. Write checkpoint artifacts to stores, files, or databases after each completed step so it can read that state on startup and skip finished work.
Full Explanation
When an agent restarts after an interruption and begins from scratch, the root cause is almost universally missing durable artifact writes. In-context memory — the conversation history held in the model's context window — is ephemeral by design. Once the session ends or the process is killed, that memory is gone. To support resumability, agents must write explicit checkpoint state to durable stores (databases, files in repositories, GitHub Gists, external key-value stores, etc.) after each meaningful step completes. On startup, the agent reads that checkpoint and determines which steps are already done. The explanation that blames an overly long system prompt is incorrect: system prompt length affects instruction-following quality within the session, not cross-restart behavior. An overly long system prompt does not cause the agent to restart from the beginning after an interruption. The explanation that short-term in-context memory is cleared between turns but retained between restarts is subtly wrong and one common distractor. Short-term in-context memory is cleared between sessions — but it is not retained between restarts. That statement gets the direction backwards. In-context memory is exactly what disappears, which is why durable artifacts are necessary. The explanation that the GitHub Actions runner does not support stateful workflows across job failures is incorrect: GitHub Actions does support resumability patterns via artifact storage and caching. The issue is not platform limitation — it is application-level design gap where the developer has not implemented checkpoint writes. Runners are stateless by design, but that is one known constraint to design around, not platform bug. The correct fix is to implement step-level checkpointing: after each review step completes, write the step name and any relevant output to durable store. On restart, the agent loads that store, sees which steps are complete, and skips them. This pattern is sometimes called write-ahead logging for agents and is foundational reliability technique for long-running agentic workflows.