
A team reports that their code-review agent continues running and submitting new review comments long after the pull request has already been approved and merged. The agent never stops on its own. What is the most likely root cause of this behavior?
Select an answer to reveal the explanation.
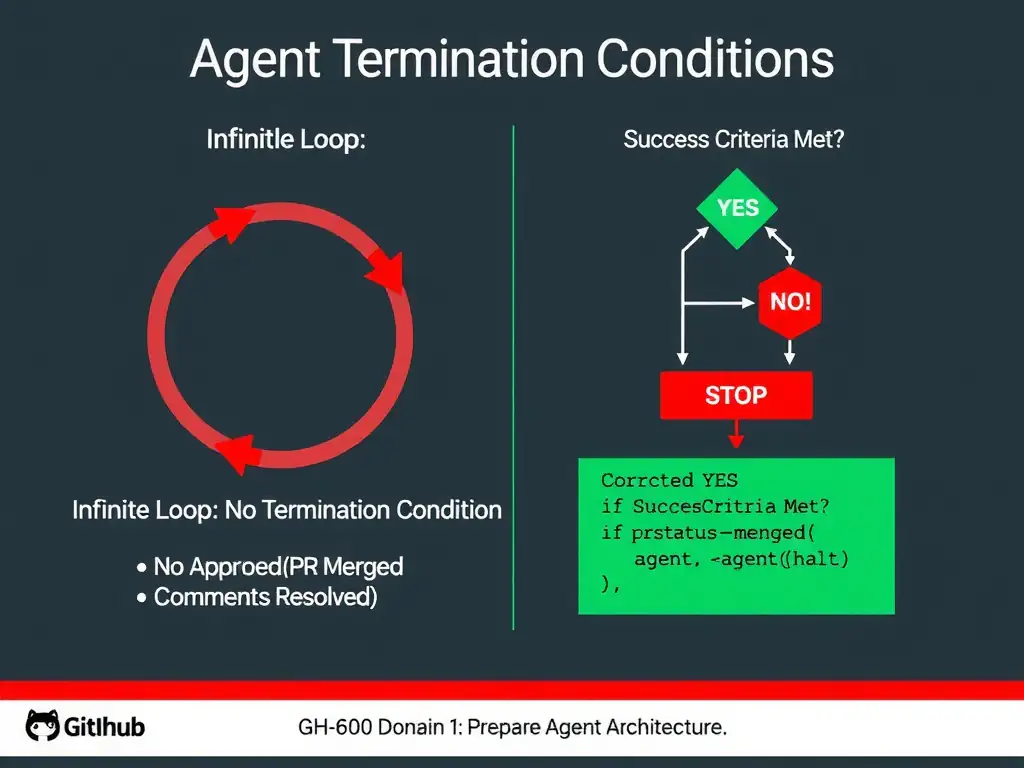
Short Explanation
Picture a security guard who has never been told the building closes at five o'clock — they'd patrol forever. Your agent was never told what 'done' looks like. You need success criteria and a termination condition that tells it when to stop.
Full Explanation
An agent that runs indefinitely is exhibiting one of the most common agentic design failures: missing termination conditions. This is distinct from a bug — the agent is working as coded, but the code never specifies when it should stop.
The correct explanation is that the agent lacks defined success criteria and a termination condition that signals when its objective has been met. Success criteria define what the agent is trying to achieve, and termination conditions are the concrete, checkable states that confirm the objective has been met. For a code-review agent, the success criterion might be 'all review comments have been addressed and the PR has received at least two approvals.' The termination condition that signals this in code would be: 'if PR status == merged OR PR status == approved AND comment_thread_count_open == 0, halt execution.' Without both of these, the agent has no basis on which to stop — it will continue executing its loop indefinitely.
The explanation that blames a system prompt that is too long is a red herring. Losing track of instructions due to context length is a separate problem, and it is more common in long conversations than in short agentic tasks. Even a perfectly concise prompt does not help if there is no termination logic.
The explanation that blames using the wrong LLM model and needing a more capable version does not address the root cause. A more capable model will still loop forever if there is no condition instructing it to stop. Model capability is about reasoning quality, not control flow.
The explanation that blames a tool-calling loop bug that prevents reading the PR status API correctly would manifest as incorrect status checks, not as infinite continuation. If the agent could not read the status interface at all, it would likely throw errors, not quietly keep posting comments. The scenario describes normal operation that simply never terminates, which points to a design omission rather than a code bug.
For the exam: 'runs indefinitely,' 'never stops,' or 'keeps retrying after completion' always indicate missing success criteria and/or termination conditions — a foundational Domain 1 concept.