
A multi-agent system has five coordinating agents. One subagent begins returning malformed JSON in its inter-agent messages. The other four agents are consuming this malformed JSON, failing to parse it, and propagating the error by passing partial data to their own downstream consumers. The cascading failure is spreading across the system. What is the correct immediate response?
Select an answer to reveal the explanation.
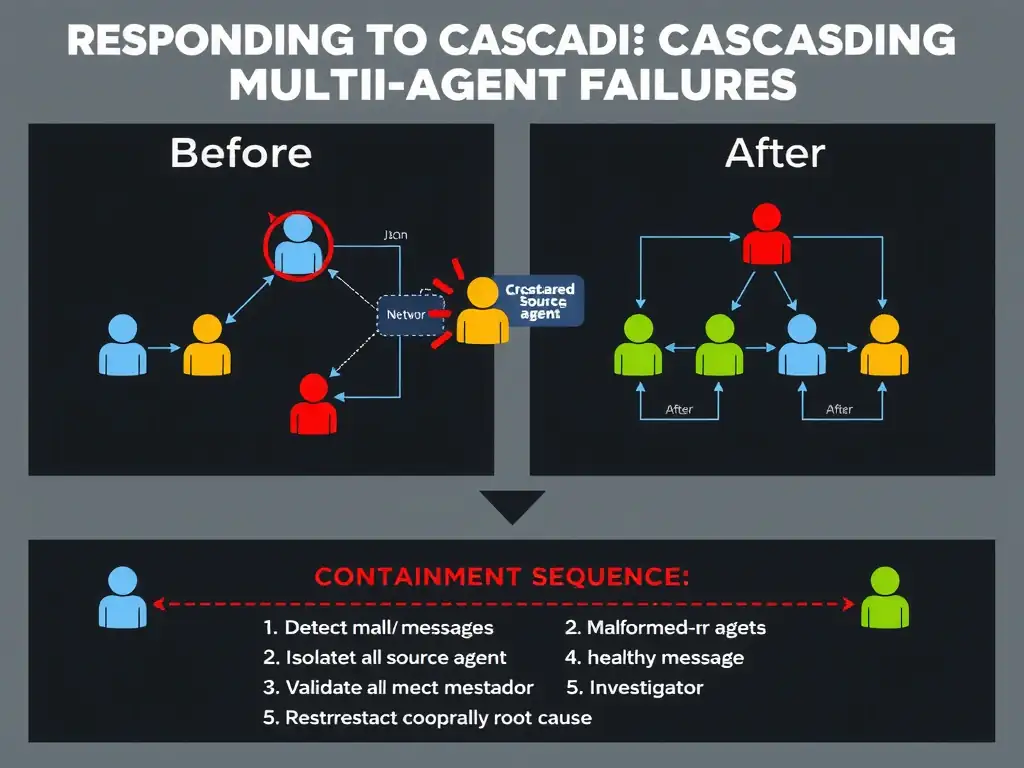
Short Explanation
When one agent is poisoning the coordination network, you isolate it immediately, then have the orchestrator intercept and validate messages before forwarding. Stop the spread first, then diagnose the root cause on the isolated node.
Full Explanation
Cascading failures in multi-agent systems occur when a malfunctioning agent's bad output propagates through inter-agent communication channels to downstream consumers. The immediate priority is containment — stopping the cascade from spreading further — before attempting diagnosis or repair. This is the same containment principle used in network security and epidemiology: stop the spread before diagnosing the cause.
The correct immediate response has two components:
- Isolate the malfunctioning agent: Remove the bad actor from the coordination network so it cannot send additional malformed messages. This may mean suspending its task, revoking its access to the shared communication channel, or having the orchestrator stop forwarding its messages to downstream agents.
- Stop propagation: The orchestrator should intercept all inter-agent messages and validate them before forwarding. Malformed messages should be discarded or quarantined rather than passed to consumers. This prevents further contamination of downstream agents.
After containment, the team can investigate the root cause of the malformed JSON, such as a bug, a model change, or a corrupted context, and decide whether to restart the isolated agent, replace it, or escalate.
Why the other approaches fail: - The restart-all-agents approach is too disruptive. The four healthy agents are not the problem — restarting them loses their current work state unnecessarily. Targeted isolation of the failing agent is more precise than a full system restart. - The continue-operating-with-partial-data approach accepts the cascade and allows corrupted state to spread further through the system. Partial data in coordination messages produces increasingly unreliable behavior in all downstream agents. The failure must be stopped. - The increase-timeout approach addresses a completely different failure mode — timeout errors, not malformed data. Longer timeouts give agents more time to process bad input, which doesn't fix the parsing failure and simply delays when the error surfaces.
The correct immediate response to any cascade failure is: isolate the source, stop the spread, then diagnose.