
A team evaluating a code refactoring agent has two signals: (1) the percentage of unit tests that pass after the agent's changes, and (2) senior developer ratings of code readability on a 1–5 scale. How should these signals be classified, and how should they be used together in the evaluation framework?
Select an answer to reveal the explanation.
Short Explanation
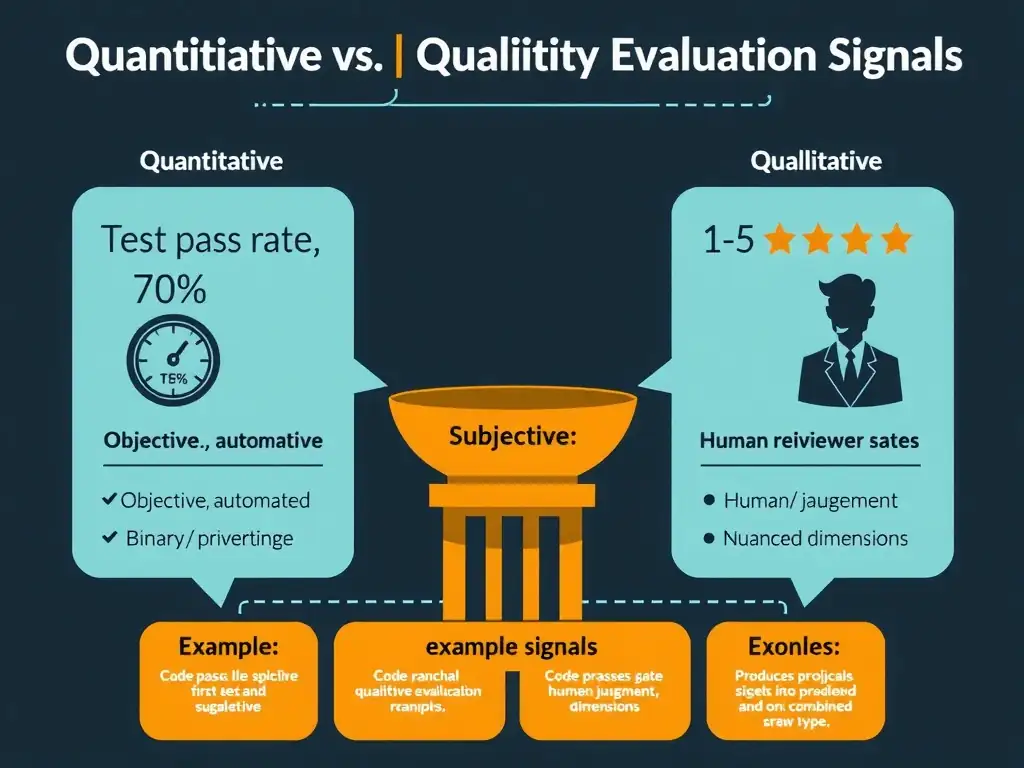
Numbers answer 'did it work?' while human judgment answers 'is it good?'. Test pass rate is a hard quantitative gate, while developer readability ratings are qualitative and capture nuance no test can measure. You need both: one for correctness, one for quality dimensions beyond correctness.
Full Explanation
Quantitative evaluation signals are objective and directly measurable: test pass rate, line count, cyclomatic complexity, build time. They yield consistent results regardless of who measures them and can be automated. For code correctness, test pass rate is the canonical quantitative signal.
Qualitative evaluation signals involve human judgment on dimensions that are difficult to reduce to a single number: readability, elegance, maintainability, naming quality, logical flow. Developer ratings on a 1–5 scale are qualitative — they capture structured human perception but involve subjective judgment that varies between raters.
The correct approach is to use both together in a complementary framework: the quantitative signal, test pass rate, provides an objective correctness gate. Code that fails tests is rejected regardless of readability scores. The qualitative signal, readability ratings, captures dimensions that tests cannot measure, such as whether the code will be maintainable six months from now by a developer who didn't write it. Used together, the two signals provide a more complete picture of agent output quality than either signal alone.
Why the other proposals fail: - the proposal that both are quantitative and should be averaged together into a single composite score is factually incorrect. The 1–5 scale based on human perception is a qualitative Likert-type rating, not a quantitative measurement, even though it produces a number. - the proposal that developer ratings are more reliable than test pass rates and should be prioritized inverts the correct hierarchy. Qualitative signals capture nuance but are inherently subjective and can be inconsistent. Objective correctness gate must come first — human-rated readability of broken code is irrelevant. - the proposal to use only automated quantitative signals discards valuable signal. Code can pass all tests and still be unmaintainable, insecure by convention, or architecturally misaligned. Qualitative signals capture these dimensions and should not be discarded simply because they introduce some subjectivity.
Robust evaluation framework uses quantitative signals as gates and qualitative signals as enrichment.