
In a three-agent pipeline where Agent A researches requirements, Agent B implements code, and Agent C reviews the implementation, which documentation practice best captures the handoffs and key decisions across all three agents?
Select an answer to reveal the explanation.
Short Explanation
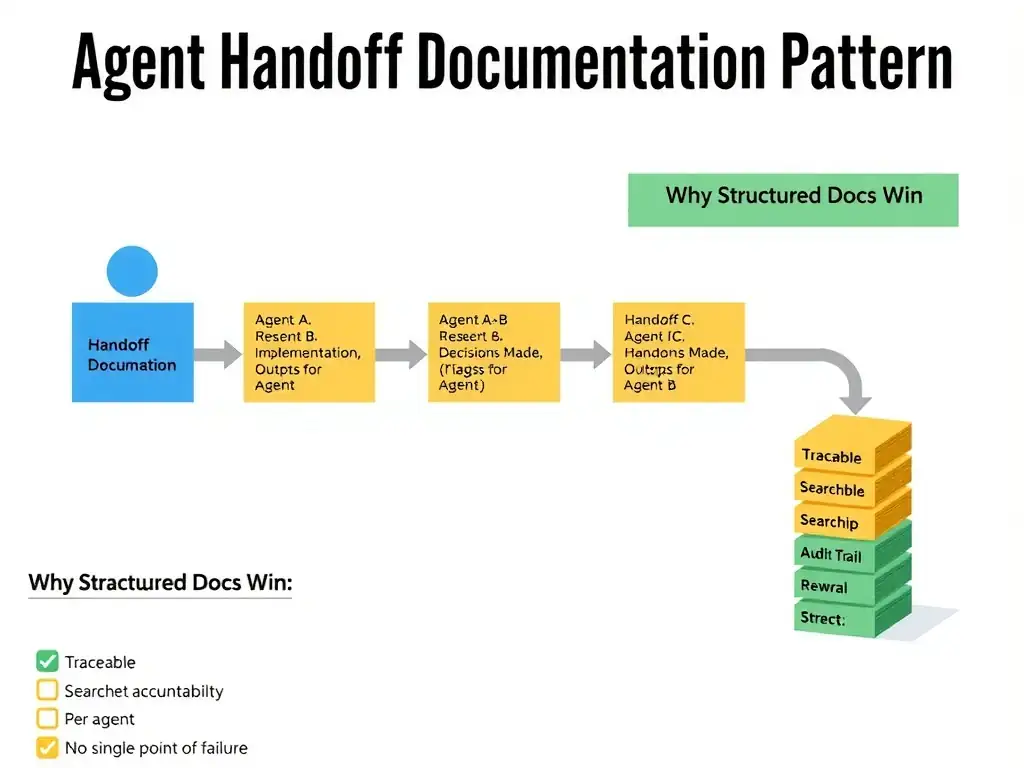
Think of a relay race — every runner needs a clean baton pass with a clear signal of where they are in the race. In a multi-agent pipeline, handoff documents are the baton: each agent writes down what it received, what it decided, what it produced, and what the next agent needs to know. This structured record is how you trace accountability and troubleshoot when something goes wrong downstream.
Full Explanation
Documenting agent handoffs in a multi-agent pipeline is essential for traceability, debugging, and compliance. The best practice is for each agent to produce a structured handoff document at the end of its execution that answers four key questions:
1. What inputs did I receive? (The context or artifacts passed from the prior agent or orchestrator) 2. What decisions did I make? (Key choices, rationale, alternatives considered) 3. What outputs did I produce? (Artifacts, code changes, findings) 4. What does the next agent need to know? (Flags, caveats, open questions, assumptions made)
This approach creates a complete, per-agent audit trail that can be read independently or as a chain.
Why the structured handoff document is correct: Structured per-agent handoff documents give each agent a defined accountability boundary. They capture causality, such as why the implementation agent made a specific implementation choice based on the research agent's requirements, and they give the review agent the context it needs to review effectively.
Why the running chat log option is wrong: An appended chat log of internal reasoning is unstructured and hard to parse. Internal reasoning includes noise — dead-end thoughts, restatements — that is not meaningful for audit or handoff purposes. Structured output beats raw logs for downstream usability.
Why the final-agent summary option is wrong: Having only the review agent write a retrospective summary for all agents is problematic because the review agent may not have visibility into the full reasoning of prior agents, may mischaracterize earlier decisions, and creates a single point of documentation failure. If the review agent fails or is skipped, no documentation exists.
Why the full-context-window storage option is wrong: Storing raw context windows is both impractical (context windows can be very large) and unhelpful (they include system prompts, retrieval results, and other noise). Structured documents are far more useful for review than raw dumps of model input.