
An agent tasked with updating API documentation produced output that appears incomplete — several endpoints are missing from the generated docs. A developer wants to identify where in the agent's execution the failure occurred. Which artifact should the developer examine first?
Select an answer to reveal the explanation.
Short Explanation
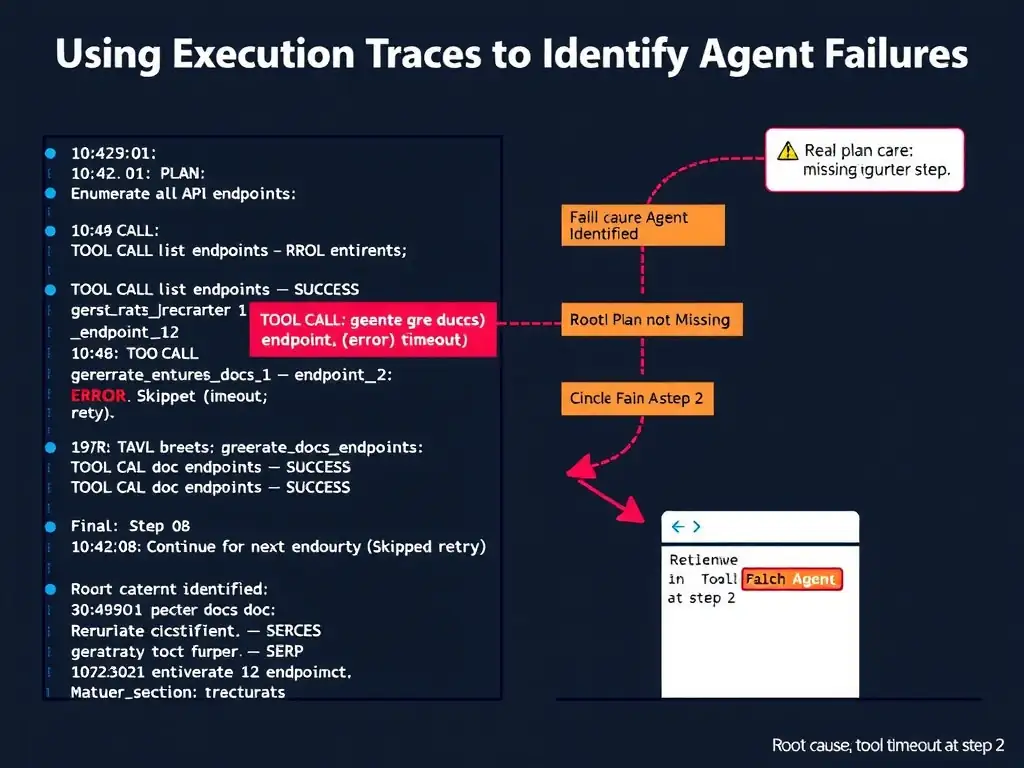
When a flight goes wrong, investigators don't just look at the wreckage — they pull the flight data recorder. For agents, that's the execution trace and logs. They show you exactly what the agent saw, what decisions it made, which tools it called, and what came back, so you can find why and where the run went wrong.
Full Explanation
Execution traces and logs are the primary diagnostic tool for identifying failures in agent workflows. A trace records the agent's full decision sequence: what it planned, which tools it invoked, what arguments it passed, and what responses it received. When an agent produces incomplete output, the trace allows a developer to pinpoint exactly which step in the reasoning or tool-call chain caused the gap. The correct artifact is the agent's execution trace and logs, which show the sequence of steps the agent took, which tools it called, and what inputs and outputs each tool received. Examining that trace first gives the developer a chronological view of the agent's behavior during the run. For a documentation task, the trace might reveal that the agent only called the API schema tool for a subset of the endpoints, or that a tool call returned an error that the agent silently ignored and continued past. Without the trace, the developer is guessing about the cause. The final output file produced by the agent, compared line by line to the expected documentation template, is a verification step — it confirms the failure but provides no insight into its cause. It may be a useful starting point to confirm that something is wrong, but it cannot identify where in execution the failure occurred. The repository's git history, used to identify which commits were made before the agent ran, is irrelevant to diagnosing an agent execution failure. Pre-run commits describe the state of the repository, not the agent's runtime behavior. The system prompt used to configure the agent, checked to see whether the instructions mention all endpoints, might be useful as a secondary step — if the instructions don't mention certain endpoints, the agent may not know to document them. However, checking the system prompt before the trace is premature. The trace will reveal whether the agent attempted to cover those endpoints and failed, or never attempted them at all. That distinction changes the diagnosis: a missing instruction versus a tool failure versus a reasoning error are three different root causes requiring different fixes. In practice, good agent frameworks like GitHub Copilot's agent mode, LangChain, and similar tools produce structured trace logs that can be analyzed to identify failures systematically.