
A GitHub Copilot agent is designed to flag potential security vulnerabilities in pull requests. The team evaluates it solely on the number of flags it produces per PR. After one month, developers are ignoring the agent's feedback entirely. What evaluation misalignment caused this?
Select an answer to reveal the explanation.
Short Explanation
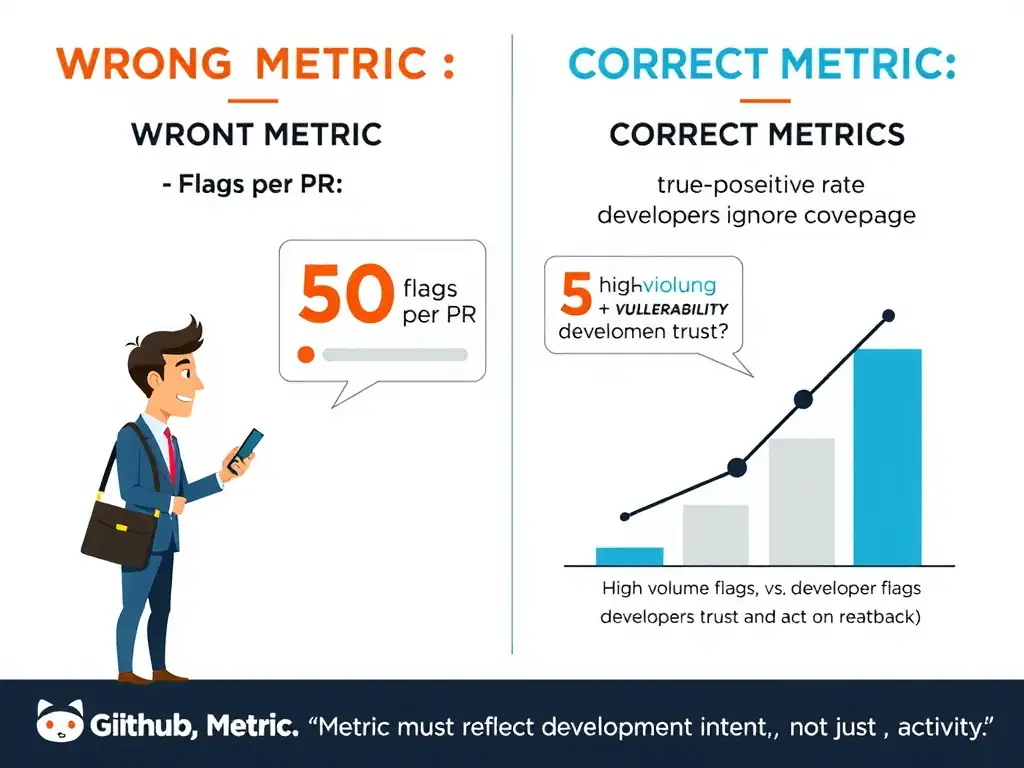
Measuring a smoke detector by how many times it beeps tells you nothing about how useful it is — what matters is whether it fires when there's actual smoke. You optimized for flag count rather than flag accuracy, so the agent became a noisy alarm instead of a trusted security advisor.
Full Explanation
Evaluation metrics must be aligned with the actual intent behind the agent's design. Misaligned metrics can cause the agent to be optimized for the wrong behavior, leading to outcomes that are technically measurable but practically counterproductive.
The correct explanation is that the team evaluated throughput, measured as flags per pull request, instead of precision, measured as the proportion of flags that represent real vulnerabilities. The team's intent was to help developers identify real security issues. The metric used measures volume, not accuracy. An agent optimized for this metric produces more flags — many of which are false positives — leading developers to distrust and ignore all flags. The correct metric should be precision, the percentage of flags that are true vulnerabilities, and recall, the percentage of true vulnerabilities that are flagged.
The claim that the team evaluated the agent too frequently, causing alert fatigue in the evaluation process itself, is wrong because evaluation frequency is about how often you measure, not what you measure. Evaluating too frequently does not cause the metric to be misaligned with intent.
The claim that the agent's model version was too old, and updating it would fix the evaluation misalignment, is wrong because model version affects capability, not metric alignment. Even with the best model, evaluating on flags per pull request would produce the same misalignment.
The claim that the team should have used only qualitative signals instead of any quantitative metric is wrong because the problem is not that a quantitative metric was used, but that the wrong quantitative metric was chosen. Precision and recall are quantitative metrics that would be correctly aligned with the agent's intent.