
An agent is running a multi-hour migration task when the GitHub Actions runner times out at 6 hours. The agent must restart but has no way to know what steps were already completed. What design pattern prevents this from becoming a wasted restart?
Select an answer to reveal the explanation.
Short Explanation
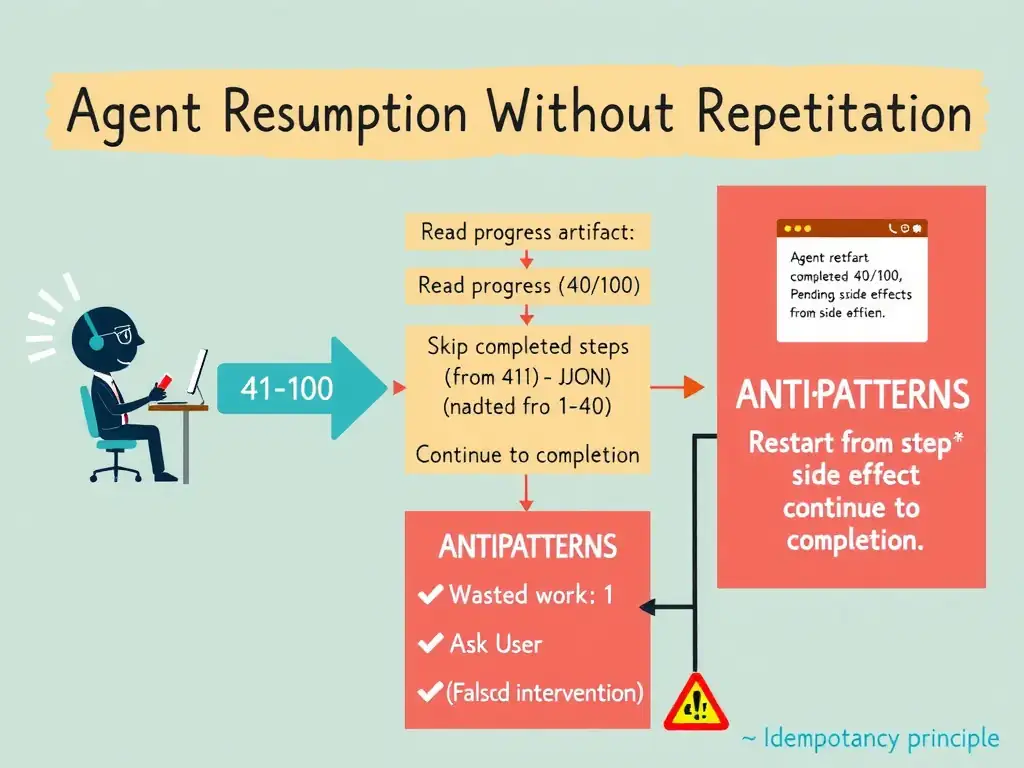
When GPS signal is lost, it doesn't make you drive back home and start over — it picks up from your current position. Checkpointing does the same: the agent writes its position after every step, so restart means 'continue from step 47' not 'begin from step 1'.
Full Explanation
Checkpointing is the pattern of writing agent execution state to durable storage after each significant step, enabling restart to resume from the last successful checkpoint rather than from scratch.
Implementation approach: 1. Before each step, check persistent store for existing checkpoint. 2. If checkpoint exists, skip all already-completed steps. 3. Execute the next step. 4. Write updated checkpoint (step ID, completed items, any accumulated output). 5. On timeout or failure, next run reads checkpoint and continues.
The checkpointing option is correct because checkpointing is the canonical solution for long-running agent tasks that may be interrupted. It makes the agent idempotent and resumable.
The option to increase the Actions runner timeout to 24 hours may delay the problem but does not solve it. Very long migrations may still exceed even extended timeouts, and GitHub Actions imposes hard maximum job timeout. The underlying design flaw — no checkpointing — remains.
The option to run migration steps only on weekends when runner interruptions are less likely is not reliability pattern. It does not address the fundamental problem of non-resumable tasks, and it is not scalable operational strategy.
The try/catch option cannot suppress OS-level or infrastructure timeout. When runner times out, the job is killed — there is no exception to catch in the running process.
Checkpoint stores commonly used: JSON files committed to the repo, GitHub Gists, external databases, or cache services like Redis.